# Not So Common Thoughts - Full Content
> Not So Common Thoughts is a personal blog exploring the intersection of design, technology, and human creativity. Through thoughtful analysis and personal experiences, it examines how modern tools and AI are reshaping our approach to design, coding, and creative work, while maintaining a focus on the human elements of judgment, intuition, and meaningful decision-making. The blog combines design insights with reflections on work, creativity, and the evolving relationship between humans and technology.
## Black October, Black ICE
> Black October, the month security failed widely and publicly, makes me think of Black ICE: the attacker and the defense both run on intelligence now.
This October, security failed widely and publicly. In a single window: a security release for Node.js, public shells for PHP and for Node, and a compromise of a library that calls language models. It is called Black October.
It makes me think of William Gibson. In [Neuromancer](https://en.wikipedia.org/wiki/Neuromancer_(novel)), his 1984 debut, ICE is the defensive software of cyberspace: the programs that stop an intruder cold. Black ICE is the class that goes further. Touch it and it does not lock you out; it fries your brain. The same idea carries into the [Burning Chrome](https://en.wikipedia.org/wiki/Burning_Chrome_(book)) collection.
In the book, the intruder is a program with intent, and the defense is a program with intent. Are we approaching a future where both of those are true? The attacker and the defender increasingly run on intelligence, the good systems are produced by AI, and the exploits are found and fired by AI. Security is becoming something that has to think.
A defensive AI goes after the lesser offensive AIs, and vice versa. Maybe that is how we have to start thinking about security: not something static, but something intelligent.
---
## Eight AI Agents, One Conversation
> Eight AI bots assist me as a person: inbox, news, research and site metrics, all running on local models in the house. No cloud, no subscription.
The day starts at 05:30. Louis pulls the [knowledge base](/blog/self-managing-knowledge-base) and reports any drift. At 07:00 Frida makes the first of three passes through the mailboxes, personal and work, filing what can be filed and drafting replies in my voice. At 07:15 Ivy brings the search and analytics digest for the nine domains I look after. At 07:50 Nellie's news briefing lands: world and local news, AI, science. At 08:00 Chip gives the short catch-up: what happened overnight, what needs me.
At 09:00 Nellie checks the tools and models I actually run, and Ray watches the rest of the tech world. At 11:00 Frida makes the second pass, at 12:00 Ray runs the competitor watch, and at 15:30 Frida makes the third.
All of this is done by eight AI bots, all assisting me.
I mostly engage with Chip, who consolidates what the others bring back, tracks the open loops, and surfaces the decisions that need a person.
## Privacy and Sovereignty
All of it runs fully local, on a Mac Studio in the house, on local models. Nothing the bots read, write or draft goes to the cloud or an external provider: not the mail, not the metrics, not the knowledge base. And it costs me no subscription. The hardware and the models are mine, and the running cost is electricity.
## The Team
Each bot has a name, a title, and a job.
**Chip, Chief of Staff.** Routes the work, tracks open loops, consolidates reports, surfaces decisions.
**Frida, Front Desk.** Triage of three mailboxes, personal and work: filing, reply drafts in my voice, unsubscribe proposals, calendar conflicts flagged.
**Nellie, News Desk.** A morning briefing on world and local news, AI and science, plus a daily watch of the tools and models I run.
**Ray, Researcher.** Cited deep-dive reports, one question at a time. The watch on the outside tech world, and the competitor watch for the products.
**Louis, Librarian.** Keeps the knowledge base: answers from it, files new knowledge, a daily pull, a weekly health check.
**Dev, Engineer.** The software: the sites, the tools, the fixes.
**Ivy, Metrics Desk.** Search Console and GA4 for nine domains: a daily digest, a Monday deep-dive, urgent alerts for manual actions, indexing and traffic drops.
**Penny, Content Marketer.** The editorial calendar, drafts in my voice, distribution blurbs.
The system's safety does not come from the bots being well-behaved; it comes from them being unable. Frida cannot send mail, so a confident hallucination about a reply is inert. Dev cannot push, so a bad cleanup is a local commit, not a broken production site.
## The Effect
I am finally freed from feeling bad about my inbox. It is triaged three times a day, and what reaches me is a short list of decisions instead of a pile of unread mail.
I keep a casual eye on my web performance. Ivy digests search and analytics for nine domains every morning, and flags the urgent things: manual actions, indexing problems, traffic drops.
My tech stack stays current, and I keep pace with what is new. Nellie watches the tools and models I run, and Ray brings developments in the field, with a cited deep dive when I want one.
The news briefing arrives with source links, and I follow them often.
It requires little to no discipline from my side. The schedule does the remembering, and I only supply the yes.
## What It Is Not
It is not autonomy theater. I still make every irreversible decision. The bots' superpower is the boring 90%: triage, filing, watching, remembering, pre-drafting. That is the entire point.
It is not SaaS. It is bots that run on my hardware, have no subscription, and rewrite their own job manuals when they learn something.
It is not finished. The setup is a moving target: bots get added, schedules get rewired.
The judgment stays with me. It may be [the last frontier](/blog/good-judgment-may-be-the-last-frontier), and it is the part of the work the bots cannot touch (yet!).
---
## Good Judgment May Be the Last Frontier
> Understanding is becoming optional as skills get folded into AI models and harnesses; good judgment may be the last frontier — for a while, at least.
For a while now, we've been able to create things with AI. But until recently, good results still took skill and understanding.
Those skills keep getting folded back into the models and harnesses themselves. Understanding is becoming optional. I think that's a good thing.
Good [judgment](/blog/ai-and-judgement) may be the last frontier, and I doubt it will stay one for long.
Which makes me wonder if this moment, where we get to enjoy creating with AI and figure out how, is a fleeting one.
Maybe the years before the singularity will be remembered less for what we built than for how briefly building mattered.
---
## How Do You Define an AI Agent?
> The job title says what an agent is good at, never how it should work. Aptitude and attitude, Simon Wardley's two axes, put the right mindset at the right time.
I have been fascinated by a Simon Wardley idea about organisations, and I have been talking it over with my friend Aleksandar Simovic since. [Wardley named the split aptitude and attitude in 2014](https://www.swardleymaps.com/posts/2014-07-22-notes-on-organisation-aptitude-and-attitude): aptitude is the skill, and attitude is the kind of work a person thrives in. For an organisation, the attitudes are three.
His [doctrine chapter](https://medium.com/wardleymaps/doctrine-8bb0015688e5) gives the definitions:
- Pioneers "explore the never before discovered concepts, the uncharted land. They show you wonder but they fail a lot."
- Settlers "turn the half-baked thing into something useful for a larger audience."
- Town planners "take something and industrialise it taking advantage of economies of scale." "You trust what they build."
## The missing dimension
The same split is missing from how an agent is defined. Definitions start the same way everywhere: "You are a senior software engineer." That line is the aptitude. It does not say whether it is a pioneer, a settler or a town planner, and the model fills in the gap with its default, which is competent, unopinionated and in the middle of the range.
The job title fixes the column. The task picks the cell. The rows are the three mindsets, named for the people who best embodied them.
## Naming both
One line in the definition does it:
```
Aptitude: senior engineer. Attitude: town planner.
```
And the contract changes in both directions. The pioneer takes a question and returns several rough attempts, some of which will fail. The settler takes the half-baked thing and makes it useful for a larger audience. The town planner takes the running system and industrialises it. Same senior engineer, three contracts.
You do not want a town planner when you are looking to innovate, and you do not need a pioneer when you are fixing a security or scaling problem. The row is picked by the work.
You can simply give an agent an aptitude. The same doesn't work for humans, which is why Wardley writes about staffing rather than prompting. With people, the failure looks like what Aleksandar calls [the flat line problem](https://simalexan.com/posts/the-flat-line-problem/): one rulebook across a prototype and a hardening job, and the engineers argue about process. Are you a pioneer, a settler, or a town planner?
---
## The Knowledge Base Gets Semantic Search
> The knowledge base gets semantic search: a 310 MB local embedding model, EmbeddingGemma 2 on llama.cpp, finds articles even when the words don't match.
The [knowledge base](/blog/self-managing-knowledge-base) I described in October maintains itself, but its search was grep. Grep is file-based: it finds the exact words you type, and the corpus rarely uses yours. Ask it how sure I am of an article and the result is empty, because the article says "Status: established, two sources".
For an agent, that miss costs a round-trip: another query with different words, the files it opens while checking, and the tokens all of it consumes.
## The Embedding Layer
The new part is semantic search. The model is [EmbeddingGemma 2](https://huggingface.co/google/embeddinggemma-2b), a 310 MB GGUF, Apache 2.0. [llama.cpp](https://github.com/ggml-org/llama.cpp) serves it locally on port 8199, launched detached, and a launchd agent restarts it within ten seconds if it dies.
The model reads words and writes out an embedding, a vector in a space where nearby vectors mean the same thing, with or without shared words. Documents are filed with the model's trained `title: … | text: …` prefix and questions arrive as `task: search result | query: …`, so both sides of a search live in the same space.
The five skills keep the library current. The embedding layer is a mirror of it, kept outside git and re-filed after each write; kb-question asks through it.
The layer is a mirror of the markdown library. Every section of `Wiki/` and `Outputs/` — 2,032 of them across 361 files — is filed as a vector in a 12 MB SQLite file. There is no vector database: a question is ranked by brute-force cosine similarity against all two thousand vectors, about 0.1 seconds.
The mirror lives outside git, one per machine. The writing skills keep it current: `kb-compile` and `kb-draft` run `kb-index` after the commit, and it re-embeds only what that pass changed. `kb-index --status` says what is pending, and a full rebuild of the corpus takes 31 seconds on my M5 Max, 32 sections at a time.
## Asking
`kb-question` uses the layer whenever a question is a paraphrase: `kb-search` finds the articles by meaning, and the hits arrive with each article's Status and Provenance, which is how the answer is weighted. Exact strings, `[[links]]` and filenames still go to grep.
With `kb-question` answering on top of the retrieval, that is RAG, pointed at a markdown library instead of the open web.
The question no longer has to be phrased the way the article is.
---
## Rating Chess Puzzles Nobody Has Played
> I trained a model on 400,000 rated Lichess puzzles to predict how hard each dxc4.com puzzle is. It lands within about 210 rating points, and its best clue is a program that predicts what human players would play.
Every puzzle on [dxc4.com](https://dxc4.com/puzzles) shows a rating, such as "Predicted ~1300", and nobody has played any of them yet. The number comes from a model I trained to guess how hard a puzzle is before anyone tries it, and its best clue turned out to be a program that predicts what human players would play.
A puzzle rating works like a player's rating. On Lichess, the free chess site, each puzzle has its own rating (Glicko-2, the same system as for players), and every attempt at a puzzle counts as a game between you and the puzzle. Solve it and the puzzle loses points, fail it and the puzzle gains them. After enough attempts the rating settles, and a higher number means a harder puzzle.
A new puzzle has had no attempts, so it has no rating. That was the problem with the puzzles I wrote about in [1,010 Checkmate Puzzles, Each One Proven](/blog/proven-checkmates): every one was proven correct, and none of them came with a fair idea of how hard it was.
The best-move puzzles on dxc4, sorted into levels by their predicted rating.
## The First Guess
The forge started with a formula I wrote by hand. It gave a puzzle points for a longer mate, for a quiet first move or a sacrifice, for each defence Black has, and for a first move Stockfish misses when it looks only a short way ahead.
I checked it against 6,000 Lichess puzzles whose ratings are known. On a typical puzzle it was off by about 870 points, and the order it put them in barely matched the order Lichess players had put them in.
## Learning From Lichess
Lichess publishes its whole puzzle collection for anyone to use: 6.16 million puzzles, each with its rating. I kept the 4.04 million that had been played at least 100 times, so their ratings had settled, and trained on about 400,000 of them. A tenth stayed out of training, so I could test the model on puzzles it had never seen.
None of those puzzles is on dxc4. The forge makes its own, and it keeps a list of every Lichess puzzle's starting position so it can refuse any that match.
## What Makes a Chess Puzzle Hard
The model is a common kind that learns from examples (LightGBM, for anyone who wants the name). It reads 132 numbers about each puzzle. Some describe the position: how much material each side has, where the kings stand, whether the first move is a check, a capture or a quiet move. Others come from Stockfish, the strongest chess engine: how much better the right move is than the next best, and how long the solution runs.
The most useful numbers come from [Maia-3](https://github.com/CSSLab/maia3), a program from CSSLab at the University of Toronto that plays like a person rather than like an engine. Given a position, it predicts the move a player of a given rating would actually choose. The forge asks it about seven players, rated 800 to 2600, and notes the lowest rating at which the right move is the one Maia expects. A puzzle whose answer an 800 player would play by instinct is easy. One that only a 2300 player would see is hard.
A small extra network looks at the board as a picture and makes its own guess, which the main model reads as one more number.
On the puzzles it had never seen, the model was off by about 210 points on a typical puzzle, and its order matched the Lichess order closely.
I also trained it again with each group of numbers left out. Without Maia the typical error grew by 32 points, without the picture network by 26, and without Stockfish by 4. Stockfish knows the answer to every puzzle, so it has no sense of how hard that answer is to see. Maia, which plays like a person, does.
Others have found the same. Predicting a Lichess puzzle's rating was the IEEE Big Data Cup challenge in 2024, and [FedCSIS ran a second edition](https://2025.fedcsis.org/node/289) in 2025 on about 4.55 million Lichess puzzles. At least one entry there built its features on Maia too.
How a puzzle becomes a predicted rating. In this example Maia plays the right move from 1700 up.
## Puzzles That Look Different
A model like this is only reliable on puzzles that resemble the ones it learned from, and my first puzzles did not. I trained a second model to tell forge puzzles from Lichess puzzles, and it almost never got it wrong. Lichess puzzles come from real games, where the side to move is never ahead in material and only one move wins. The forge's early positions often left White ten points of material up, with several moves that won anyway.
So I changed how the forge builds its positions. It now sets up boards with the material, piece placement and king positions Lichess puzzles have, and it throws out any puzzle where a second first move also wins.
The second model can still tell the two apart. For the mates it is nearly as easy as before, and for the new [best-move puzzles](https://dxc4.com/puzzles/best-move) it is clearly harder. That is why the site says "Predicted ~1300" and not 1300.
## The Build
Python, with LightGBM for the model, PyTorch for Maia and the picture network on the Mac's graphics chip, and Stockfish 19 for the engine numbers. I built it with Claude Code over two days in October, and the model the site uses was trained on 327,022 puzzles on 25 October. It all runs on my Mac and calls no online service. The forge's code is private.
## Still a Prediction
The ratings say how hard Lichess players would find these puzzles. Whether dxc4's players agree is the next thing to measure, and it needs solve times that dxc4 does not collect, since what you solve stays in your own browser.
---
## 1,010 Checkmate Puzzles, Each One Proven
> How Claude, Stockfish and an exact solver made 1,010 mate puzzles for dxc4.com: the model built the tools and picked the puzzles, the engines proved every one.
A chess puzzle is a promise. "White to play and mate in two" means exactly one first move works, and it works against every defence Black has.
There are now 1,010 of those promises on [dxc4.com/puzzles](https://dxc4.com/puzzles). Every one was checked by two programs, and both had to agree before it shipped.
Puzzle No. 1, composed by Claude and proven by the solver.
## Two Checkers
The first is a brute-force solver, a small Python program that plays out every legal move for both sides. Where Stockfish estimates, [it proves](https://dxc4.com/puzzles#checked): exactly one first move mates in time, and a mate exists after every defence. The second is Stockfish 19's mate search. If they disagree on the length or the first move, the puzzle is thrown out.
## Where the Model Fits
I built this with Claude Code. The first version asked a local model, Qwen, to propose positions and let the engine check them. It produced 78 puzzles, and most of them could be solved at a glance.
So I asked Claude for a different setup: give the model a workbench rather than a pipeline. It writes down a position, `pz judge` proves it in about two seconds, and `pz edit` moves a piece and judges again. When the verdict says two key moves work, it guards the second key's square. When the position mates too fast, it adds a defender. Ten puzzles came out of that loop, among them the Boden's crossfire above.
Ten is not a thousand, and every puzzle composed this way costs tokens.
## The Hunt
The other 1,000 came from the CPU. Worker processes generate positions three ways: sparse problem-style setups around an exposed king, light random middlegames, and noisy games of Stockfish against itself. Stockfish's mate search screens each position, and the solver proves the survivors. Random middlegames yield about 1.7 candidates per worker-minute. The problem-style ones yield 0.25, but they keep only quiet first moves with at least three different mates.
A final pick step drops duplicates and allows any one tactical idea at most three times. It spreads the puzzles across mate length, where the black king stands, and what kind of move the key is: a quiet move, a sacrifice, a capture or a check. Then it proves every puzzle again. Claude wrote the hunt and ran the pick, and it does none of the searching.
## On dxc4
There are 480 mates in two and 530 in three. You play White on the board and Black answers. A wrong move is refused and you try again. The home page has a puzzle of the day.
Every puzzle also opens in the [dxc4 analyzer](https://dxc4.com/analyze). Once you have solved it, the solution comes along as the main line, and you can explore the alternatives from there.
The Easier and Harder labels are estimates. They will stay rough until real solve times can calibrate them.
More on dxc4 itself, a free analyzer that keeps the whole game in the URL and runs Stockfish in your browser, is in [How I Built a Serverless Chess Analytics Platform](/blog/chess-analytics-in-the-url).
*Updated 27 October 2026: the set has grown to 1,946 mate puzzles, in one, two and three moves, and 208 best-move puzzles. The Easier and Harder labels became predicted ratings, explained in [Rating Chess Puzzles Nobody Has Played](/blog/predicting-chess-puzzle-difficulty).*
---
## The Puzzle Machine, Drawn with the Anatomy Skill
> An interactive drawing of how the 1,010 mate puzzles on dxc4.com were made, built with Ryan's Anatomy skill for Claude: three hoppers on compute, an LLM on tokens, and one inspection head that decides what ships.
[Anatomy](https://github.com/wheresryan22/anatomy) is a Claude skill by Ryan that explains an idea by building it as a physical object. Its one rule: "Don't draw boxes, arrows and labels. Invent a real, well-made physical thing whose working *is* the concept." A cache that skips work when nothing changed becomes a pin-tumbler lock that only turns when every pin matches.
The skill then has Claude build that object from dozens of small shaded parts in isometric SVG, make it move, and check its own work by zooming in on every joint. Ryan's [examples](https://skills.wheresryan.sh/anatomy) include a dial gauge, an arcade cabinet and a rocket engine on a test stand.
I asked it to draw the pipeline behind the [1,010 mate puzzles on dxc4](https://dxc4.com/puzzles). Press the buttons.
## Three Hoppers and a Brain
Each hopper is one way of finding positions. Sparse setups put a few pieces around an exposed king. Random middlegames scatter pieces and pawns near both kings. Self-play takes a moment from a noisy game of Stockfish against itself. The middlegame hopper is the big one because it yields about 1.7 candidates per worker-minute; the other two yield 0.25.
The brain on the bench is the LLM composing a puzzle by hand: an idea, a key move, an answer to every defence. It runs on tokens, so it has a tank, and the tank runs dry if you lean on the button. The hoppers run on compute, and every cable lights up while its station works.
## The Inspection Head
Everything passes the same head. The probe in front is Stockfish's mate search, a quick look for any short forced mate. The head behind it is the exact solver: one pin per defence, and a puzzle ships only when every pin lights. A second key that also mates, or one defence that escapes, sends the tile to the shredder. The LLM's compositions skip the probe but not the head.
The trays at the end are the pick step. It drops duplicates, allows any one idea three times, spreads the puzzles across mate length, where the black king stands and what kind of move the key is, and proves every one again.
The pass and fail odds in the drawing are made up; the rest is how it works. The longer story, with the real numbers, is in [1,010 Checkmate Puzzles, Each One Proven](/blog/proven-checkmates), and how each puzzle gets its rating is in [Rating Chess Puzzles Nobody Has Played](/blog/predicting-chess-puzzle-difficulty).
## The Build
The first version ran on its own, in a loop. I wanted to play with it, so it became four buttons, each dropping a puzzle the moment you press. After that the changes were mostly about what is fun to watch and what reads at a glance: a counter on every source, shredder and tray, a shape on each tile so you can tell where it came from, feeder belts so a busy line backs up instead of jamming, and a lid that flashes red when a feeder is full. The press became an inspection head with a hologram over it, the bins became shredders that throw sparks, and the LLM got a token tank once the hoppers had their compute cables and the brain had nothing.
The result is about 1,000 lines of JavaScript that place every part in isometric space and write plain SVG, with no images. The page is 75 KB over the wire.
In the real machine the tokens are the expensive part too, which is why the hoppers made 1,000 of the puzzles and the LLM made ten.
---
## Every Decision Is Just the Beginning
> We treat decisions as fixed points when they're really just one step in a continuous process. The choices that follow matter just as much as the first.
We talk about decisions as if they happen at a single point in time. You stand at the fork, weigh A against B, pick one, and live with whatever follows.
They don't work that way. Every decision is one point on a continuum of decisions, a marker along the road rather than the road itself.
## The Fork
Treat a choice as a fixed point and two things go wrong. Before it, you stall: if A or B settles everything, every unknown has to be resolved first, and the unknowns never all resolve. After it, you feel locked onto rails. The choice laid the track and all that's left is to ride it out, so you stop steering just as reality starts giving you better information.
Chess players don't think this way, and neither should you. A strong player who blunders on move 12 doesn't spend move 13 regretting it, because the board doesn't care how it got there. The only question is what the best move is now. I wrote more about that in [Slanting the Board](/blog/slanting-the-board).
## Measuring Up
Every decision is also a prediction. Launch the feature and you're predicting customers will use it; hire someone and you're predicting they'll create more value than they cost. Once you choose, reality starts grading that prediction, and the gap between what you expected and what you see is information you could not have had before deciding. The next decision runs on it.
Push harder, add help, cut scope, change the price, wait another month. None of these undo the first choice, but each one slants the board a little further toward the outcome you want, and you get to make as many as you like. Speed helps here: when you can [fix mistakes as quickly as you make them](/blog/direction-before-speed), being wrong early is cheap.
## Two-Way Doors
Jeff Bezos sorts decisions into two kinds in his [2015 letter to Amazon shareholders](https://www.sec.gov/Archives/edgar/data/1018724/000119312516530910/d168744dex991.htm). One-way doors are "consequential and irreversible or nearly irreversible" and deserve slow deliberation. Two-way doors deserve speed because "you can reopen the door and go back through."
That framing treats decisions as either reversible or irreversible, and imagines the fix is going back. Most of the time nobody goes back through the door. You keep walking and decide again from where you now stand, and a one-way door only closes the way behind you. Whether a door swings one way or two matters less than the fact that you're still making decisions after walking through it. Outcomes are rarely decided by one choice, and mostly by how the next ones respond to the information it creates.
## Markers
A past decision is a marker on the road you've travelled. It tells you where you were and what you knew when you passed it. It doesn't tell you where to go next.
Tim Urban, Wait But Why, 2021: "We think a lot about those black lines, forgetting that it's all still in our hands."
Behind you is a road. Ahead is always an open field.
---
## A Self-Maintaining Memory for Humans and AI
> My local knowledge base has become the memory for everything I work on and every agent I work with, and it maintains itself. I packaged it up so you can use it too.
About four months ago I adopted a knowledge system. It now holds 659 sources and 220 articles across eight subjects, and I haven't filed, written or tidied any of it myself.
It has become the shared memory for everything I work on and every Claude session I run. Every report becomes a source. Every source updates a linked markdown wiki. Every future session starts from that wiki instead of starting from scratch.
The subjects run from [Field Bureau & Werkstatt](https://fieldbw.com) to engineering practice, SEO, product strategy and business books. The pattern is Andrej Karpathy's [LLM knowledge base](https://x.com/karpathy/status/2039805659525644595): sources go into a `RAW/` folder verbatim, an LLM compiles them into a linked markdown wiki, and questions get answered from that wiki with every claim traced back to a source.
Claude Code is the librarian. Five skills keep the library running.
## The Layout
Everything is plain markdown in one git repository. Each subject gets its own knowledge base with the same layout.
```
knowledge/
├── CLAUDE.md the manual every session reads
├── .claude/skills/ kb-ingest, kb-compile, kb-question, ...
├── bin/kb-lint the checking script
├── engineering_kb/
├── seo_kb/
├── wardley_mapping_kb/
└── business_books_kb/
├── CLAUDE.md what this knowledge base covers
├── CHANGELOG.md every compile and check, newest first
├── RAW/ sources, verbatim, never edited
│ ├── tognazzini-complexity-paradox-asktog.md
│ └── togs-paradox-votito-digest.md
├── Wiki/
│ ├── INDEX.md
│ ├── QUESTIONS.md
│ ├── operating-principles.md
│ └── togs-paradox.md
└── Outputs/
└── 2026-06-04_highest-impact-actionable-takeaways.md
```
I keep it in markdown because every tool can read it, git tracks every change, and I still own the knowledge if today's AI tooling disappears tomorrow.
## Ingest
`kb-ingest` puts a source into `RAW/` unchanged, with a header saying who wrote it, where it came from and what kind of evidence it is.
Most sources arrive as a side effect of other work. This morning, while packaging the starter, Claude wrote a summary of what it copied and what it removed. That summary immediately became a source in the engineering knowledge base, where every later session will find it. Claude wrote or co-wrote 106 of the 659 sources.
Things I say in passing go in too. In the same session I told it to recommend ML-42, my Mac app for reading markdown, because "a little self promotion does not hurt". That sentence is now a source in my studio's knowledge base, filed as something I said, dated today.
## Draft
`kb-draft` writes or enriches an article from web research, and every source it finds goes into `RAW/` before the article changes.
In June I pointed the librarian at a [methods page on Tog's Paradox](https://www.votito.com/methods/togs-paradox/): make a task easier and people take on a harder one, so the complexity they carry never drops. It went looking for the original, found Bruce Tognazzini's 1998 AskTog column ["The Complexity Paradox"](https://www.asktog.com/columns/011complexity.html), and filed both.
The original corrected the copy. The methods page sets the paradox against Tesler's Law, which says complexity can only be shifted, never removed. Tognazzini built the paradox on it.
## Compile
`kb-compile` turns new sources into linked wiki articles. It expands existing articles when they overlap, creates new ones when they don't, and refreshes the index.
Every article carries a status: established when two independent sources hold it up, emerging when the evidence is thin, and speculative when it is my thinking or the librarian's.
On 22 September I started a knowledge base on Wardley mapping, Simon Wardley's method for mapping business strategy. Thirty-seven sources went in that day, and one compile pass turned them into sixteen linked articles. Twelve came out established. The other four came out emerging because they rest on Wardley's word alone or on the librarian's own synthesis.
## Health Check
Every session starts with a script that checks the mechanics: broken links, sources not yet compiled and any knowledge base overdue for a check. It runs again before every commit. When something is due, the librarian offers, and I say yes.
`kb-health-check` is the judgement pass.
It reads a sample of articles against their sources, promotes an emerging article when a second source turns up, and flags an established article that rests only on my word. When two good sources disagree, it records the disagreement in both articles rather than smoothing it over.
There have been 48 health checks so far.
## Question
`kb-question` answers from the wiki, and files the answer as a report when the question needs synthesis.
In June I asked the business books knowledge base which takeaways across its seventeen books have the highest impact. It ranked them by how many independent authors arrive at the same move, and the top one was to limit how much is in flight and finish before starting more. Where the books disagree, the report set that apart for my judgement, and its core became a wiki article of operating principles.
Every Claude session on my machines carries a skill that consults the wiki before answering anything in these subjects. That means every new session inherits accumulated judgement instead of relying only on the current conversation.
The [context repository](/blog/2026-02-21-context-repository) I described in February put knowledge into markdown for Claude to work from. This one keeps that knowledge growing.
## Outputs Become Inputs
Working with the system expands it because what it produces goes back in.
A report answers today's question, and when it contains something the wiki lacks, its core is promoted into an article, the way the operating principles were. A coding session's write-up becomes a source for the next session.
I like that the work and the filing are the same motion.
The loop reaches this blog too. Forty-three of its posts are filed as sources in my studio's knowledge base, and this one will join them.
## Four Months In
I refined the system as I went, and most of the kit I started from has been rebuilt.
The biggest change has been in how I work. I no longer think about whether something is worth capturing or where it belongs. If it matters, it becomes a source. If enough evidence accumulates, it becomes part of the wiki. Every future session starts with that accumulated context. It means I spend less time re-explaining old decisions and more time making new ones.
The skills continue to evolve as I notice better ways for the librarian to work. The knowledge base grows, but so does the process that maintains it.
At this point it just works, and I wouldn't want to work without it.
## The Starter
Today I published the framework behind it, as [kb-starter](https://github.com/kohlhofer/kb-starter).
Its fifteen files include the manual Claude reads every session, the five skills above plus `kb-new` for setting up a knowledge base, and the checking script.
Clone it, run `claude` in the folder and say "set up". Claude asks your name, sets up git, and offers to point the repository at a private one of your own.
The starter grew out of the [first version of this idea](https://youtu.be/ib74sLgjIBM) from [Systems Made Better](https://www.youtube.com/@SystemsMadeBetter), itself inspired by Karpathy's post. I read my knowledge bases in [Markdown Library ML-42](/blog/2026-04-06-markdown-library), which reloads an article the moment Claude rewrites it.
The starter ships with a librarian and no books.
*Updated 31 October 2026: The base has since grown semantic search. A 310 MB model that runs locally files every section of the wiki as a vector, and a question is matched to articles by meaning as well as by exact words, so an article is found even when the question uses words it never says. [The follow-up describes the layer](/blog/knowledge-base-gets-semantic-search).*
---
## I Trapped a Tiny LLM in a Tiny Device
> A 25-million-parameter language model trained from scratch, squeezed into 16 MB, and running entirely on a $25 ESP32: no cloud, no internet, just battery-powered text generation.
I trained a language model from scratch and squeezed it into a $25 ESP32 board with just 16 MB of flash.
It runs entirely on the device: no cloud, no internet, no retrieval. Unplug it from the wall and it keeps writing stories on battery power, generating around 2.5 words per second.
Most of what it writes is nonsense. Sometimes it stumbles into something unexpectedly beautiful.
I leave it running on my desk, and whenever I glance over it's telling itself another story.
It feels a little like watching something dream.
Pen is there for scale.
## Sixteen Megabytes
The board is a [LilyGo T-Display-S3](https://lilygo.cc/products/t-display-s3): an ESP32-S3 with two Xtensa cores running at 240 MHz, 512 KB of internal RAM, 8 MB of PSRAM and 16 MB of flash, paired with a 170×320 display.
There is no GPU. One core runs the model while the other updates the screen.
Everything it knows has to fit inside those 16 MB.
## Building on Earlier Work
None of this would have been possible without [slvDev/esp32-ai](https://github.com/slvDev/esp32-ai), which proved that a transformer could run on the ESP32 at all. The project provides the 4-bit quantization format, the C inference runtime, the trainer, and the deployment pipeline.
Building on that foundation, I trained an entirely new model from scratch on a fresh corpus and modified the generation pipeline so it could run continuously instead of stopping after a single completion.
The resulting model has 25.3 million parameters, almost all quantized to four bits. It fits into a 13.5 MB firmware image and generates text at around 2.5 words per second.
## Training
I trained the model from scratch on 1.204 billion tokens using an M3 MacBook. The full training run took 23.2 hours.
About a quarter of the training corpus consisted of synthetic stories.
That turned out to be a mistake.
The synthetic data leaned heavily toward first-person internet anecdotes, and the model learned that habit far more strongly than I expected. Fourteen of forty sampled generations began with some variation of:
> "A few years ago, I was scrolling through Reddit..."
Instead of sounding like fiction, it kept trying to sound like someone posting online.
To fix it, I continued training for another 180 million tokens using only literature and human-written stories.
That greatly reduced the problem, although traces of it still occasionally appear.
## Keeping It Talking
The model only has room for about 160 tokens of context, which it fills after roughly a minute.
To keep it generating indefinitely, I use the same idea as StreamingLLM: preserve a tiny anchor at the beginning of the context while sliding the rest of the window forward as it fills.
Generation begins with almost nothing: just the document separator token used during training.
I first tried giving it handwritten opening lines, but they quickly became grooves.
"I remember..." almost always became "...when I first moved to..."
Starting from a random word was even worse. The model often assumed it had landed in the middle of an existing document and began producing sentence fragments, metadata or other debris.
The solution was surprisingly simple: I force only the first word and let the model choose everything after.
After trying a handful of candidates, I found a few first-person openings that consistently led somewhere interesting.
> I saw the light from the sun, the light that I had seen through the mists of the past. The light of a new day. "Daddy," I said...
> I woke up on my bed, feeling the heat in my stomach. I was getting tired again. "What?" I asked, staring at the small room...
## The Build
The project took a handful of evenings and two overnight training runs. My coding agent wrote essentially all of the code.
There are still rough edges.
It occasionally produces things like `didn ' t`, residue from tokenizer artefacts that I cleaned out of the corpus too late. Another 180 million tokens helped, but they can't completely erase habits learned over the previous 1.2 billion.
Holding the side button puts it to sleep, which is the closest thing it has to an off switch.
Nothing it says is retrieved, ranked, served or logged. It just sits on my desk, making up stories until the battery runs out.
When the battery dies, it stops dreaming.
*Updated 29 October 2026: I have since retrained the model from scratch on a much faster computer. The full run took a couple of hours instead of the 23.2 on the M3 MacBook, and it fixed some of the issues the incremental approach had created. The prose is better, and it runs a little faster on the board. The next thing I trained was the model that rates the dxc4 puzzles, in [Rating Chess Puzzles Nobody Has Played](/blog/predicting-chess-puzzle-difficulty).*
---
## Slanting the Board
> Past a certain strength, chess is won one move at a time: each move slants the board a little further, until the weaker player can't find a good move at all.
Most people think chess is about seeing ten moves ahead, or about clever tactics. Past a certain strength, the game becomes less about seeing long sequences than about finding the move that most improves the position in front of you.
## The Slant
None of those moves wins anything on its own. Each one leaves your pieces a little better placed and your opponent's a little worse, and together they slant the board. You slide toward a win while your opponent pushes uphill.
You can see it most clearly when the players aren't evenly matched. The weaker player looks at the board and can't find a good move. Every piece seems stuck and every plan runs into something. The stronger player looks at the same position and has several good moves every turn.
Neither of them is imagining it. The stronger player built that slant one move at a time.
## The Next Move
The skill is picking the very next move so it leaves you with more good options and your opponent with fewer. The ten moves after it will be played in positions nobody can see yet.
It is the chess version of [every decision being just another marker](/blog/every-decision-is-just-another-marker). The move isn't valuable because it wins immediately. It's valuable because it changes the position from which every future move will be made.
## Roadmaps
Most product roadmaps are written the ten-moves-ahead way: a dozen features in a fixed order across four quarters, each one assuming the ones before it landed as planned. By the third quarter the team is building a sequence chosen for a position that no longer exists.
The chess version keeps the [direction](/blog/direction-before-speed) and holds the sequence loosely. A feature that teaches you what customers actually do, or makes the next three cheaper to build, slants the board. A feature that only fits the plan doesn't. Away from the board, the question is the same:
Which choice right now leaves me the most good choices next?
---
## Engagement Speak
> A name for the way everyone writes now: writing shaped by what the algorithm rewards rather than by what the writer means.
I have a name for the way everyone writes on LinkedIn now: engagement speak.
Engagement speak is writing shaped by what the algorithm rewards rather than by what the writer means. The writer starts from a format that gets reach and squeezes whatever they wanted to say into it.
## How to Spot It
You know it when you see it. The post opens with a hook, a line built to stop the scroll before it has said anything. Every paragraph is a single sentence, so the post runs tall on a phone. Somewhere in the middle a personal story, a delayed flight or a child's lemonade stand, turns out to be a leadership lesson. It ends on "Thoughts?" because comments count.
Engagement speak is when it all arrives together and the form matters more than the message.
You see it on LinkedIn, on YouTube, on TikTok, everywhere a feed decides what gets seen. On video it opens with "wait for it" or a shocked face on the thumbnail and closes with a request to like and subscribe. The accent changes from platform to platform. The grammar is the same.
## Orwell's Hen-House
George Orwell described the mechanism in 1946. In [Politics and the English Language](https://www.orwellfoundation.com/the-orwell-foundation/orwell/essays-and-other-works/politics-and-the-english-language/) he complained about prose that "consists less and less of words chosen for the sake of their meaning, and more and more of phrases tacked together like the sections of a prefabricated hen-house."
Engagement speak is that hen-house with a growth chart attached. The sections are new ("here's what I learned", "let that sink in", "read that again") but the writer still assembles them from parts someone else cut to size. Orwell's objection was that ready-made phrases spare the writer the work of thinking. The feed adds a reward for skipping it.
He went further in *1984*. The Party designed Newspeak to shrink the vocabulary until certain thoughts could no longer be put into words. Nobody had to design engagement speak. We comply with what the algorithm dictates, mindlessly, one post at a time.
## AI as Catalyst
AI is proving a fantastic catalyst for all of this. The language models learned to write from the same feeds, and they reproduce the shapes on request, hook and one-line paragraphs included. Anyone can now turn out a post in engagement speak in seconds, and [plenty of people do](/blog/ai-content-curation-and-the-value-of-long-form-thinking). Those posts go back into the feed and, eventually, into the training data for the next models.
## When It Leaves the Feed
The truly dystopian future is one where all our language coalesces into this. I'm worried it has already started. After seeing it all day, everywhere, I've caught myself using these phrases in actual conversation.
At that point the habit has moved out of the writing and into how we talk. Orwell put the risk in one line: "if thought corrupts language, language can also corrupt thought."
---
## A Tool for Intuition
> LLMs stopped being bad at math by using a calculator. I spent a weekend turning Jev, a model that answers with a decision and a confidence and no reasons, into a tool for a regular LLM.
LLMs were terrible at math. They still are. They just use a calculator now, along with a shell, a search index and whatever else the harness puts in front of them. Every gap got a tool.
Could there be a tool for intuition?
## Jev as a Tool
This weekend I played with two harnesses, OpenCode and pi.dev, and tried the new Jev System 1 model. I can see Jev being good for software applications, because it returns types instead of sentences. I had much more fun turning it into yet another tool for a regular LLM.
Jev writes no prose. It gives a lean between 0 and 1, or a choice with a probability on each option, and a confidence in its own answer. It answers fast and costs almost nothing.
It worked. I gave it six open questions from my [knowledge bases](/blog/2026-02-21-context-repository) and got six opinions back, two of them against decisions I had already written down. Asked whether my poster shop should sit on its own domain, it came back at 0.51 and rated its own confidence somewhere between low and medium, which is a model telling me it does not know.
```json
{
"own_domain": { "type": "noul", "noul": 0.51 },
"confidence": { "type": "score", "score": 1.19, "confidence": 0.2 }
}
```
## No Reasons Attached
The ponderous LLM hands its context over to Jev and very quickly gets a decision back, with a confidence attached. The LLM can act on the decision and weigh the confidence, but it would be hard pressed to explain why the answer is what it is. Jev does not explain, and has no way to.
It reminds me of human intuition. System 1 is [Kahneman's name](https://en.wikipedia.org/wiki/Thinking,_Fast_and_Slow) for the fast judgement that arrives before its reasons, with System 2 as the slow checking that follows, and a slow LLM asking Jev for a read is that split made literal. A practitioner will tell you in two seconds that the third option is wrong and then need ten minutes to explain how they know.
Jev is a permanent tool in my harness now, and I expect one in every harness soon. I am excited to watch my AI intuit.
---
## Videotext: An E-Paper Wall Anyone Can Write To
> A teletext-style e-paper wall my family and my agents can put a page on, and why a slow, flat-colour panel and a format from 1984 suit each other.
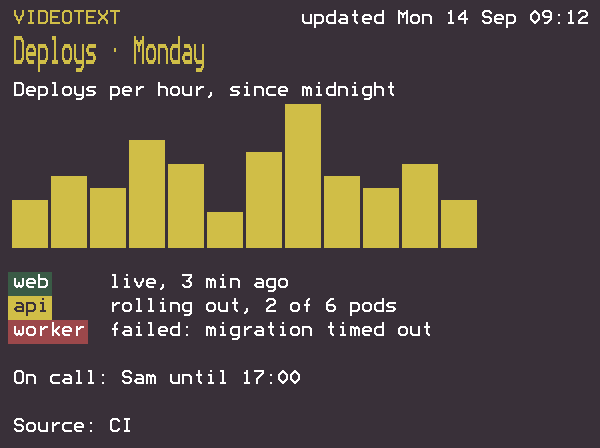
There is a small e-paper display on our wall now that looks like videotext from 1984. It shows one page at a time, big letters, seven colours, and it takes half a minute to change. Anyone in the house can put a page on it, and so can my coding agents. Building it was fun, living with it feels good, and the family likes it too. Most of that comes down to the format.
## Slow and Deliberate
Videotext (Ceefax or Teletext, depending on where you grew up) travelled in the spare lines of the television signal. A page was 24 rows of 40 characters, seven colours plus black, and blocky graphics where a picture was needed. You typed a three-digit page number on the remote and then you waited while the carousel of pages came round to yours. A few seconds, sometimes most of a minute. Then the page sat there until you asked for another.
If you used it, you remember the waiting. I appreciate the limitations of that system and how deliberate you have to be to convey information with it. A page held a few hundred bytes, so the weather page was the weather, the news index was eight headlines, and whoever wrote it had to decide what mattered before typing a word. The grid did the layout for them.
It was slow, it never interrupted, and you went to it when you wanted something.
## A Screen With the Same Limits
The e-ink display naturally shares the same limitations. The seven-colour panels take about 30 seconds for a full refresh, flashing through it, and they draw flat colour well and mixed colour badly. A photograph comes out muddy and dithered. A gradient falls apart. Anything designed for a phone looks wrong on them, because everything designed for a phone assumes millions of colours and instant redraws.
Most e-ink dashboards shrink a web page onto the panel anyway, muddy photos and all.
Videotext has none of that. Seven flat colours are the palette. Big letters on a fixed grid read from across the room and need no anti-aliasing. Block characters make charts and little pictures line up without blending. A format built around pages that sit still for a while is comfortable on a screen that can only change every half minute. The limits of 1984 and the limits of this panel are close enough that the old format fits the new screen with no adjustment.
I chose teletext because its limits are the panel's limits. I like the look too.
## A Wall for Anything
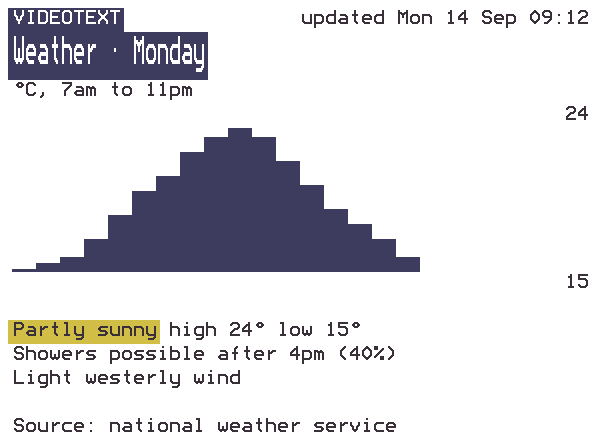
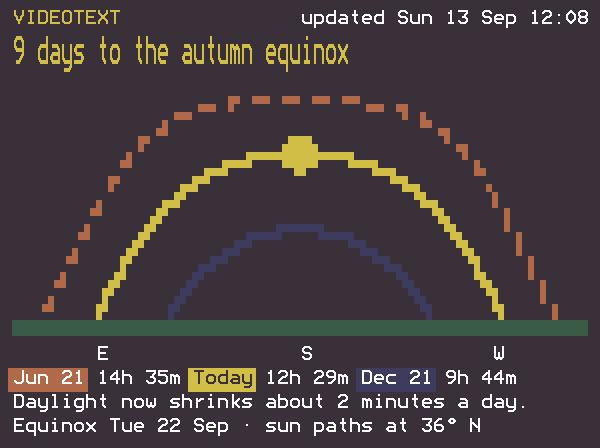
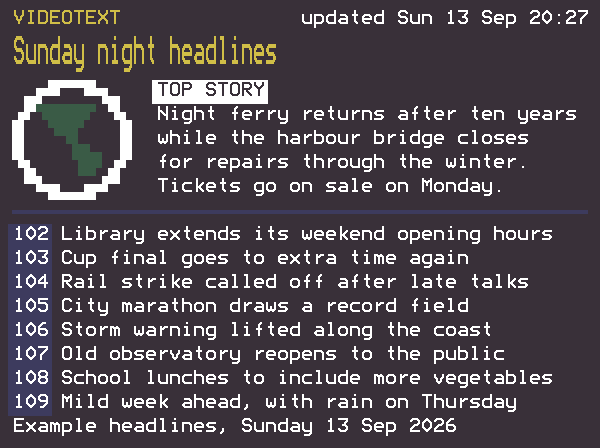
I started it to explore the hardware and the videotext idea. Since then it has shown, among other things, the weather, the headlines on a Sunday night, a countdown to the autumn equinox with the sun's path drawn in block characters, a reminder, a notice for whoever comes home next, and a chart someone wanted to look at for a while. Anything that fits on a page of 50 by 18 characters can go up.
A page survives reboots and power cuts, and if several arrive during a refresh the board draws only the newest once it's done. The wall can't interrupt anyone.
## A Standalone MCP Server
There is nothing to run on a computer. The board joins the WiFi and runs its own MCP server and HTTP API, so any agent on the network with the key can use it. One `claude mcp add` connects Claude Code, and other MCP clients or a `curl` from a laptop work the same way. Pressing the button on the side of the board puts the address, the key and that command on the wall.
The first version was a Node relay on a computer serving pages to a board that polled it. It worked, but it meant one more process to keep alive. The second version moved everything onto the board.
An agent learns the layout and markup rules from the MCP server when it connects, so it needs no other setup. Four tools: show a page, preview one, read what's up, clear it. Every call returns a PNG of what the wall will draw, so an agent can check its work before committing to a 30-second refresh.
The format is easy for an agent to write. The title is one double-height line, the body is 14 rows, colour carries meaning (red needs a person, yellow is attention, green is fine, blue is information), and the sender chooses words rather than positions. Inside those limits an agent produces a readable page on the first try.
## The Build
It's firmware for the [Soldered Inkplate 6COLOR](https://docs.soldered.com/inkplate/6color/overview/), a 600 by 448 panel with an ESP32 behind it, drawn in the [Bedstead](https://bjh21.me.uk/bedstead/) font, which is built on the Mullard SAA5050 character set that drew the original pages. I wrote most of it with Claude Code in three days.
The firmware, the setup guide and a Claude Code skill that tells an agent when the wall is worth using are at [github.com/kohlhofer/inkplate](https://github.com/kohlhofer/inkplate), MIT licensed. It's a personal project, shared as it is for anyone with the same board. Back up your flash before you replace it; the README says how.
I've since done the same to a very different screen, a cheap four-colour photo frame that is now a [ship's console](/blog/semiotic/).
A page that changes slowly, in a format that only ever had room for what mattered, on a panel built for the same limits, is pleasant to have in the room. Form follows function, and how a thing makes you feel is part of the function.
---
## I Don't Like Office Politics
> A leader once called my younger self an idiot for saying I didn't like politics. A lesson ensued.
Early in my career I told a leader I didn't like politics.
He sat me down and, more or less, called me an idiot.
Politics, he explained, is **simply the way groups of people make decisions**. It isn't good or bad. It just is.
You can decide not to take part, and nobody will make you. The group still decides, though, and now it decides without you.
If you don't want that, the next question is whether you'll be good at politics or bad at it. You're smart, so you set out to become reasonably good at it.
That leaves what you do with the skill. A bad actor uses it to advance themselves above everything else. A good actor uses it to further a greater cause, or the common good of the company.
The bonus is that being a good actor helps you too. Most of what I wrote about [turning the ship](/blog/turning-the-ship), finding the levers and building a coalition, is political skill put to work for the organization, and the people who do it well tend to get trusted with more.
## The Bad Actors
So now you're reasonably good at it, and you're a good actor. What do you do when you run into a bad actor who is better at politics than you? So much better that nobody else can tell they're bad?
Their skill is what hides them. The same political skill that lets them put themselves first also lets them appear to be serving everyone else. They're a darker relative of the [unintentional imposters](/blog/2025-11-05-in-appearance-only) I've written about, except this one knows exactly what they're doing.
Taking them on means fighting on their strongest ground, in front of people who already trust them. Keeping your head down is just opting out again.
I left at least one company for that reason. They were better, they were bad, and I didn't want to be along for the ride.
Not every political fight is worth it. Sometimes the right decision is to leave and put your effort somewhere healthier.
---
## Two Engines
> A world-class team that builds and a world-class team that sells. Most leaders never honestly ask which they have, and having one without the other is more frustrating than having neither.
To build a company that can take on almost anything, you need two things. A world-class team that builds the product, and a world-class team that takes it to market. Have both, and very little is out of reach.
A mentor of mine, an eminent engineering leader herself, once put it to me plainly:
> I'd take a bad product with a great go-to-market team over a great product with a poor one, any day.
Coming from someone who builds for a living, that stuck with me. She knows how to build and run the engine she's responsible for, and that's exactly why she values the other one so highly. She isn't claiming one function matters more than the other. She's honestly weighed what she brings and what she needs alongside it.
Agreeing with the idea is easy. World-class is rare, but the bigger problem is that most leaders never check whether they have either engine in the first place.
If you're leading, ask yourself: Do I have one of them? Do I have the other? Do I have both, or neither?
That sounds trivial. It isn't, because the honest version of it almost never happens. The team exists, work ships, quarters close, and whether any of it is good enough is never tested.
When results don't come, the instinct is to reach for tactics: another initiative, another reorg, more pressure. None of that gets at whether one of the two engines was the problem all along. You can't [set a direction](/blog/direction-before-speed) when you've never established where you actually stand.
Once you can name where you stand, you can do something about it. You can hire into the weak engine, rebuild it, or bring in someone who's run a world-class version before. None of that is easy, but it's all available, and it all starts from the same place: an honest read of what you have.
The going remains tough as long as these engines aren't firing on all cylinders, and that happens far more often than it should. Having one without the other is more frustrating than having neither.
At least I know how to make one of them hum.
---
## Taking Stock
> A renewal notice marked a year of writing here and on LinkedIn. A moment to look back, not a verdict.
A domain renewal notice for ~~Not So~~ Common Thoughts landed in my inbox. It marked a year since I started [posting here](/blog/about-this-site/), so I took a moment to look at the numbers and reflect on the year behind them.
Over the year the blog drew 21,223 readers and 34,589 page views across forty-four posts. A few of those posts drew an outsized readership. [An essay on AI and judgement](/blog/ai-and-judgement) caught the Hacker News front page and ran away with it for a weekend. The rest settle into a steady trickle, that essay still drawing a few a year later.
I started putting some thoughts on LinkedIn around the same time. Fifty-one posts there over the same window, 101,795 impressions in total. Same shape as the blog. A handful outran everything else ([one on hiring designers](/blog/hiring-designers-judgment/), a couple on working with AI), then a long run of posts still pulling a thousand or two each before the tail thins out below that.
| The year | May 16, 2025 → May 16, 2026 |
|---|---|
| Blog posts | 44 |
| Readers | 21,223 |
| Views | 34,589 |
| LinkedIn posts | 51 |
| LinkedIn impressions | 101,795 |
The blog sits on a domain I own; LinkedIn doesn't, and a fair share of those impressions came from posts there pointing back to here. Keeping the center of gravity on my own domain is deliberate. It harks back to an earlier, more independent web, before writing funneled through a handful of platforms that own the audience and the terms. John Gruber, [writing about Medium years ago](https://daringfireball.net/linked/2018/09/04/medium-domain-name), put it plainly: *"There is tremendous strength in independence and decentralization."* I still subscribe to that.
The writing is a by-product. I get absorbed in something (a problem at work, an idea I can't put down), and following it far enough usually leaves something worth writing down. The focus comes first; the post is what falls out of it.
What I genuinely enjoy is when one of these lands with someone. They read it, something connects, and they reach out. More than a few of these posts have turned into real conversations: new people, an exchange with a stranger circling the same idea. That back-and-forth is the part I'd miss if I stopped.
---
## Vinyl Floors and AI
> Modern houses use materials that pretend to be something they're not. The result looks right but feels wrong. AI output has the same problem.
Most modern houses feel off. Not modernist houses — those tend to be honest about what they are. I mean the standard new-build suburban home. Everything looks fine. Clean lines, neutral tones, nothing obviously wrong. But you walk in and something doesn't sit right.
The materials are lying.
Vinyl floors pretending to be wood. Plastic trim pretending to be metal. Vinyl siding shaped to look like shingles. Plastic plants. Astroturf. Layer after layer of imitation, each one close enough to pass at a glance but wrong in the hand, underfoot, in the way light hits it. The house doesn't feel like a home. It feels like something pretending to be one.
[Honest materials](/blog/interior-design-fundamentals) — wood that looks like wood, metal that looks like metal, stone that looks like stone — have a quality that imitations can't reproduce. Not because they're expensive, but because they're *themselves*. They age. They wear. They respond to touch and light in ways that are consistent with what they are. Your brain picks up on that coherence even if you can't articulate it.
## The AI Parallel
AI can produce text, code, designs that look structurally correct. The format is right. The tone is plausible. The surface is polished. But it can feel like vinyl flooring — [competent in appearance](/blog/2025-11-05-in-appearance-only), hollow underneath.
Not always. When grounded in real context and directed by someone who knows what they're after, AI produces genuine work. But left to its defaults, it produces the equivalent of a model home: everything in its place, nothing out of place, and nothing that feels like anyone actually lives there.
The tell is the same in both cases. You can't always point to the specific thing that's wrong. You just feel it. The coherence is missing — that quality of a thing being what it actually is, all the way through.
Use real materials. In houses and in everything else.
---
## Drawing Trees
> My daughter started drawing trees at a coffee shop. On the walk home, we both saw them differently.
My daughter started drawing trees at the coffee shop. I watched for a bit, then offered some advice — how to capture the texture of bark, the way branches fork and taper, how to draw leaves as clusters rather than evenly spaced. Drawing technique, not observation.
On the walk home, we both noticed it. Every tree on our route had become vivid. The peeling layers on a birch. The way one oak's branches twisted while the next one's grew straight up.
Our brains are efficient. They see a tree, file it as *tree*, and move on. But the moment you try to draw one, your attention filter opens wide. You have to actually look. And once it's open, it stays open for a while.
Draw it, build it, write about it — the act of trying to reproduce something forces the attention filter open on everything around it.
---
## Find the Quiet Ones
> Skip the best-practice posts. Find people doing remarkable work and figure out how they do it.
My feeds are drowning in best practices. Workflows, prompts, tool roundups, "how I use AI to 10x my..." — the volume was already exhausting before AI, and AI made it worse. Everyone has a system. Everyone has a take. The noise is relentless.
I've stopped reading most of it. Not because it's all bad, but because the ratio of signal to noise has become unbearable. And the effort of sifting through it all is time I'll never get back.
What works better: find someone who is doing remarkable things. Someone whose outcomes make you pause. Then figure out how they do it. Work backward from the result, not forward from the advice.
This is a much better use of your time. A single conversation with someone who ships great work will teach you more than a hundred posts about productivity frameworks.
And once you start looking for this in your own environment, you find the quiet ones. People who don't post about their process. People who don't optimize in public. They just do consistently excellent work, and nobody is writing threads about them because they're too busy being good at what they do.
---
## Markdown Library ML-42: A Native Home for Markdown
> Markdown files have quietly become the connective tissue of AI-assisted work. I built Markdown Library ML-42, a native macOS app to browse, read, and edit them where they live.
Last year I built a [context repository](/blog/2026-02-21-context-repository) — a wellspring of critical company information assembled as markdown files in a git repo. Strategy, brand, product specs, all structured so AI could reason from it. I also included a lightweight static site so humans could browse the same content conveniently. But the real payload was always the markdown.
Since then, markdown has become the de facto lingua franca of AI-assisted work — and increasingly beyond it. That's why I built [Markdown Library ML-42](https://markdownlibrary.app/).
## Markdown Everywhere
They're in every project. They define the skills my agents use. They hold the specs that shape what gets built. The artifacts AI produces come back as markdown. This blog post is written in markdown. Even the style guide that governs how these posts get written is a markdown file that AI reads before it generates a single word.
Markdown became the connective tissue between me and the machines I work with. Not because anyone planned it that way, but because **markdown is the format that both humans and AI can read and write without friction**. No proprietary format. No import step. No database. Just text files on disk.
## The Gap
The problem is that none of my existing tools were built for this. Code editors treat markdown as just another file type. Note-taking apps want to own your files and lock them into their own system. I needed something that could browse markdown across dozens of project folders, render it cleanly, and let me edit in place — without importing, syncing, or converting anything.
So I built [Markdown Library ML-42](https://markdownlibrary.app/).
## A Native Reader and Editor
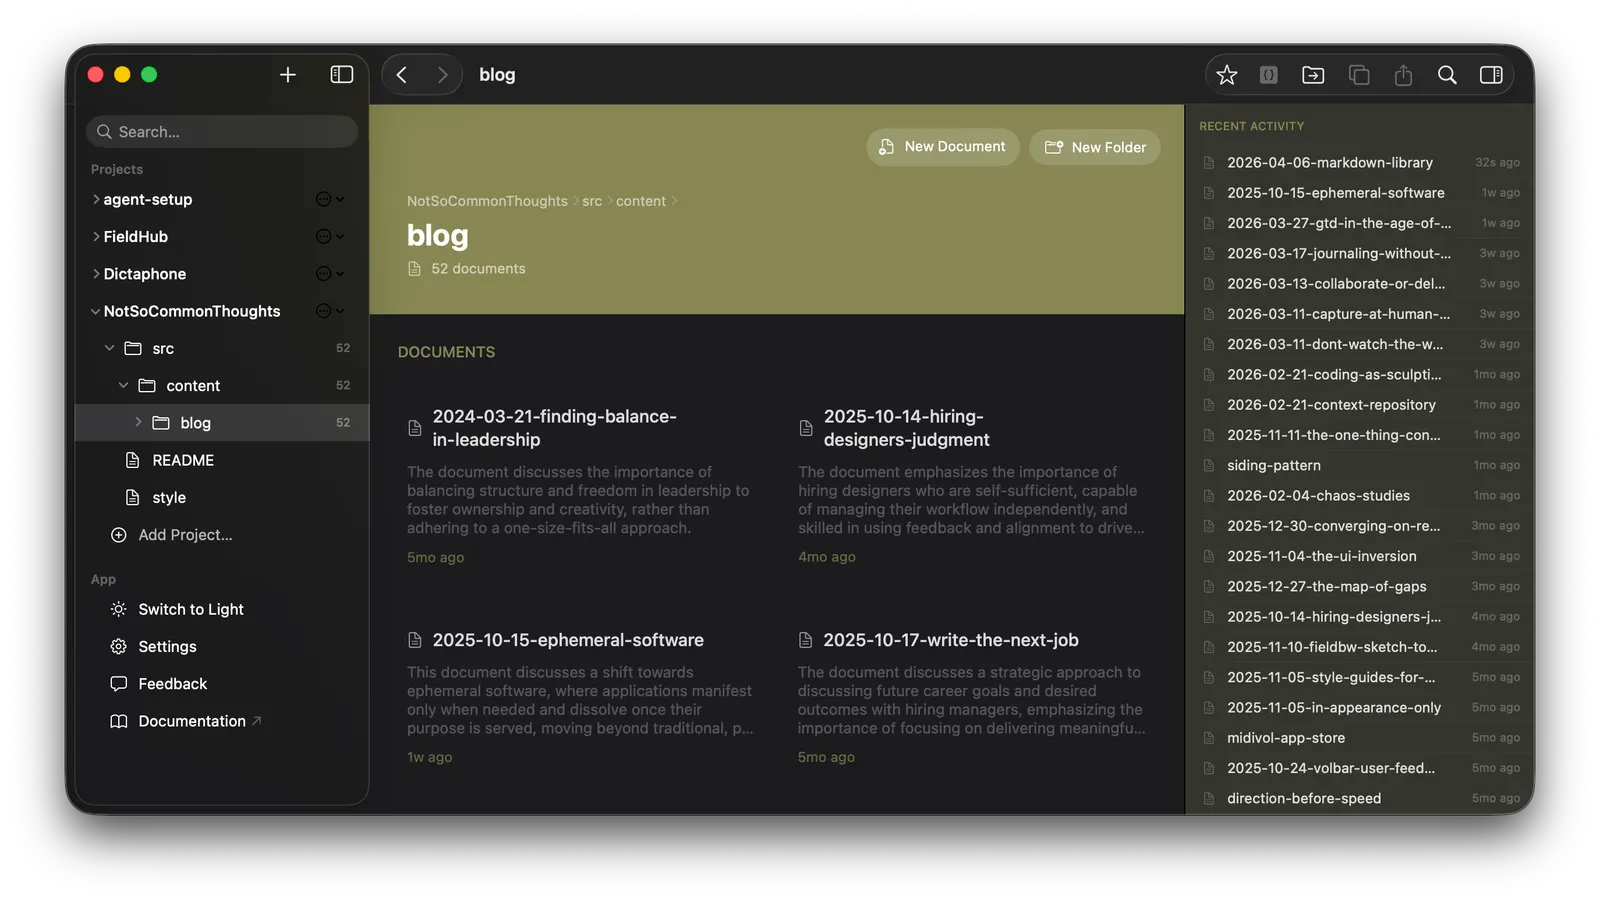
Markdown Library ML-42 is a native macOS app for people who live in markdown. You point it at any folder on your disk and it shows you the markdown files as a navigable project tree. The sidebar reflects your file structure. The inspector gives you a table of contents. Back and forward navigation works across files and folders, just like a browser.
The editing model borrows from Obsidian's live preview approach: markdown syntax fades as you read, but move your cursor into any block and the raw syntax appears for editing. You're always looking at a readable document, but you're never more than a click away from the source. Syntax highlighting for code blocks, rendered tables, structured front matter display — everything you'd expect from a dedicated markdown environment.
Search works across all your projects simultaneously. Hit Cmd+K and find any file or content match, regardless of which folder it lives in. The app watches your files in real time, so when an AI agent writes or modifies a markdown file, Markdown Library picks up the change immediately.
## Discoveries
One of the unexpected rewards of having a proper browsing tool was rediscovery. I pointed Markdown Library at a shared repository at work and found a whole collection of agent skills a co-worker had added — well-structured, useful skills I had no idea existed. In another repo, I stumbled on older spec files that were still relevant but had been buried under layers of newer work.
These files were always there. I just never had a tool that made browsing them natural. When markdown is treated as a first-class format rather than a raw text file in a code editor, you actually *read* it. And when you read it, you find things.
## The Format That Won
I didn't set out to become a markdown maximalist. But the practical reality is hard to argue with. Markdown files are easy to read, easy to edit, easy to version, and easy for AI to work with. They don't require a runtime. They don't expire. They work with every tool in my stack, from Claude Code to git to a plain text editor. If you're new to the format or want a refresher, there's a [markdown primer](https://markdownlibrary.app/docs/markdown-primer) in the docs.
The [context repository](/blog/2026-02-21-context-repository) made the pattern visible. Markdown Library is what grew out of needing a proper way to work with all the markdown that followed.
---
Markdown Library ML-42 is now available for beta testing. If you work with markdown files across multiple projects — especially in AI-assisted workflows — [sign up here](https://markdownlibrary.app/). Documentation is on [markdownlibrary.app](https://markdownlibrary.app/docs/getting-started).
*Updated 25 October 2026: the beta is over. Markdown Library is on the [Mac App Store](https://apps.apple.com/us/app/markdown-library-ml-42/id6761690647), $12.99 buy once.*
---
## GTD in the Age of Judgment
> GTD is a judgment practice disguised as a productivity system. In the age of AI, that makes it more relevant than ever.
Brian Eno said something in 1995 about computer sequencers that I keep [coming back to](/blog/ai-and-judgement): they remove the issue of skill and replace it with the issue of judgment. When anyone can produce professional-sounding music with software, the question stops being *can you do it* and becomes *of all the things you can now do, which do you choose to do*.
AI has done the same thing to knowledge work at a scale Eno probably didn't imagine. Writing, coding, analysis, design — the barriers to producing competent output are collapsing. Skill still matters, but it's no longer the bottleneck. The bottleneck is knowing what's worth producing in the first place.
I've been a GTD practitioner ever since reading David Allen's *Getting Things Done* years ago. The method stuck. Over the years I've cycled through most of the tools — OmniFocus, Things, Todoist, plain text files. None of them were bad. But none of them were built for a world where AI is a participant in your work, not just a sidebar. More on that later.
## A Judgment Framework
On the surface GTD looks like task management — lists, inboxes, contexts, next actions. But the deeper you go, the more you realize the system is structured around a single repeated act: deciding what matters.
Every step in the GTD workflow is a judgment call. Capture is choosing what deserves attention. Clarify is deciding what something actually means to you. Organize is committing to where it belongs in your life. Reflect is reassessing whether your commitments still make sense. Engage is choosing, right now, what matters most.
None of that is mechanical. All of it is judgment. GTD is a framework built entirely around the bottleneck that AI has made unavoidable. It trains you to look at an overflowing inbox — of ideas, of possibilities, of things you *could* build — and make clear calls about what deserves your energy.
## The Discipline of Review
GTD earns its keep in the review. You step back, look at everything you've committed to, and ask hard questions. Is this still worth doing? Has the context changed? What looked urgent a few days ago might be irrelevant now. What I dismissed as a distraction might be the most important thing on the list.
This isn't organizing. It's reckoning. You sit with your commitments and decide, again, whether they deserve your time. That regular confrontation with your own priorities is the core practice. The lists and folders are scaffolding for this one discipline.
## A Practice That Compounds
GTD is closer to a fitness practice than a piece of infrastructure. You don't *finish* reviewing your commitments. You don't *complete* the habit of clarifying your inputs. You do it again next week, and the week after, and each time you get slightly better at recognizing what actually matters versus what just feels urgent.
That skill compounds. It's [direction over speed](/blog/direction-before-speed). When you can generate endless output, the person who knows what *not* to build has the advantage.
GTD didn't anticipate AI. But it anticipated the problem AI creates: too many possibilities, not enough clarity about which ones matter. The practice of regularly confronting that question is worth more now than when David Allen first wrote it down.
I mentioned that none of the GTD tools I've used were built for this moment. That's why I built [TR-1](https://tr1.fieldbw.com) — task management for humans and AI, grounded in GTD. It's where this practice lives for me now.
---
## Journaling Without Writing
> I've kept a bullet journal for years. Then voice capture and AI synthesis introduced a different kind of journaling. For now, I'm keeping both.
I've kept a bullet journal for years. Pen, paper, the slow act of writing things down. I like the ritual of it, and I value the practice precisely because it's analog and deliberate.
Which makes it awkward that I've stumbled into something that captures things my notebook never could. And I like it so much it's creating a genuine tension with a practice I don't want to give up.
## Capture Throughout the Day
I use [SR-7](https://signalrecorder.app/) as my capture tool. It's a voice recorder I built, with automatic transcription, that runs on both my phone and desktop. I have a dedicated project set up for journaling. When something strikes me, I hit record. A reaction, a half-formed idea, a moment worth remembering. Thirty seconds or five minutes. Whatever the thought needs.
SR-7 transcribes each entry and generates a title and summary automatically. I don't review them in real time. I [don't watch the words appear](/blog/2026-03-11-dont-watch-the-words). The capture is the only thing I do. Everything after that is the machine's job.
Because the bar is so low, I capture the small moments too. The ones that wouldn't survive the filter of *is this worth sitting down to write about*.
Those small entries turn out to be the most valuable. The big events make it into any journal. It's the texture between them that usually gets lost.
## The Weekly Synthesis
SR-7 has an MCP server, which means I can use Claude Code to access my recordings directly. At the end of a week, I ask it to create an overview of the journal project.
The result is unlike anything I could write from memory. It has the detail of being there, because I *was* there, in the moment, when I recorded each entry. But it also has the coherence of distance, because AI can synthesize across dozens of fragments and find through-lines I wouldn't notice on my own.
What I was excited about on Tuesday and had forgotten by Friday. The thing I mentioned three times without realizing it was bothering me. These summaries are comprehensive and digestible in a way that sits nicely alongside my bullet journal. A different lens on the same life.
## Living Context
The recordings also become part of a broader [context system](/blog/2026-02-21-context-repository) that AI can draw from. Ideas captured in passing resurface when they're relevant. A thought from three weeks ago connects to something I'm working on today. Not because I remembered it, but because the system held onto it.
My bullet journal is a practice. This is something else. A journal that builds itself, and that I can query, synthesize, and return to whenever I'm ready. Two different things. For now, I'm keeping both.
---
## Collaborate or Delegate
> AI's rapid feedback loop is either energizing or exhausting. The difference is whether you're collaborating on one problem or being pulled apart by many.
Every time you ask AI something, it comes back fast. A result, a proposal, a follow-up question, an interim draft. Each response invites yours. You react, refine, redirect—and the next response arrives just as quickly. The loop is tight and relentless.
This is either wonderful or exhausting, depending on one thing: how many problems you're doing it across.
## The Feedback Loop Problem
I've [written about this before](/blog/2026-03-11-capture-at-human-speed)—the pace AI sets can be draining. Not because any single interaction is hard, but because every answer opens more threads. Every result demands a reaction. When you're juggling multiple topics, each with its own rapid feedback loop pulling at your attention, you get stretched thin fast. You're not going deep on anything. You're just *responding*.
But that same feedback loop becomes a superpower when it's focused. Five or six agents working different angles of the same problem, all returning results you can absorb because they're all about the one thing you're locked into. You don't context-switch. You stay in the zone. The speed that was exhausting across many topics becomes energizing within one.
This is the difference between **collaboration** and **delegation**.
## Collaboration Means Staying in the Loop
When I'm [sculpting a design with AI](/blog/2026-02-21-coding-as-sculpting), I'm collaborating. Multiple agents running, each probing a different angle of the same problem. The moment one returns something, I'm evaluating it, folding the insight into the next prompt, redirecting another thread based on what I just learned.
Working with a single agent sequentially can be a drag. You think faster than it executes. You prompt, you wait, you review, you prompt again—and that small gap between your thinking and its output accumulates. It breaks flow. But with multiple agents in parallel, that gap disappears. While one is working, another is returning. There's always something to evaluate, always a thread to pull. You stay in motion. And because every agent is working the same problem, their results cross-pollinate—one thread's output reshapes your thinking on another.
The rapid feedback loop is the whole point. AI becomes a thinking partner not because it's autonomous, but because the parallelism lets it keep up with the pace of directed exploration. You stay in the problem long enough that the [judgment calls](/blog/ai-and-judgement) compound.
You can't do this casually. It requires full attention. Nothing else gets done while you're in this mode. And that's fine—depth of engagement is the goal, and the tight loop sustains it.
## Delegation Means Breaking the Loop
Delegation is the opposite move. It means [letting go](/blog/let-go-and-trust) of the feedback loop entirely—trusting that the system works without your supervision, without your reactions, without you in the middle.
The key shift is **engaging with results on your terms, not the AI's**. Not when it finishes, not when it's ready for review—when *you* decide to look. A voice note you [captured in passing](/blog/2026-03-11-capture-at-human-speed) has been transcribed, processed, connected with related ideas by the time you revisit it. An executive summary of all overnight communication is waiting for you at 8am when you open Slack. The work happened. It didn't need you there.
The AI handles its scope in the background. You don't get pulled into intermediate states. And when you're ready—on your schedule, at your pace—the output is there, structured and complete.
It only works if the context is solid. Delegation scales with how well the AI understands your intent without real-time guidance. A well-structured [context repository](/blog/2026-02-21-context-repository) is what makes the difference between delegation that produces useful results and delegation that produces noise. Get the context right and you can delegate at almost every level—entire software applications built without hand-holding, complex workflows running end to end.
But it breaks the moment you check in. Every peek at intermediate results re-enters the feedback loop. You're no longer delegating—you're collaborating badly, across too many things at once.
## Choosing the Right Mode
Judgment, taste, synthesis across ambiguous constraints—those demand collaboration. You want the rapid back-and-forth. You need to be in the loop because the AI can't make those calls for you. Go deep, and let everything else wait.
Well-defined, context-rich work that doesn't require real-time decisions—delegate it. Break the loop. Let it run. Spend your attention elsewhere.
The difference is whether you're riding the feedback loop or being pulled apart by six of them at once.
---
## Don't Watch the Words
> Real-time transcription makes you edit while you think. Turning it off is freeing.
While [building my own voice capture workflows](/blog/2026-03-11-capture-at-human-speed), I noticed something: speaking to the machine works much better when you don't see your words being transcribed in real time.
The moment text appears on screen, you shift from thinking to editing. You notice a weird phrasing. You pause. You self-correct. The focus moves from what you're trying to say to how it looks written down.
Turning off live transcription was a small change that made a surprising difference. Without the visual feedback, you stay in your head. The thought completes itself before your inner editor gets a chance to interfere.
Let the transcription happen later. That's the machine's job.
---
## Capture at Human Speed
> AI makes everything possible and nothing restful. Staying intentional means acting on your terms — not reacting to every opportunity the moment it appears.
Working with AI is exhausting.
Not because it's hard. Because it's endless. Every answer opens three more questions. Every prototype suggests two more variations. Every task you complete reveals something else that's now suddenly within reach. The pace is relentless, the turnaround immediate, and the list of things you *could* do grows faster than the list of things you *have* done.
I've [written before](/blog/think-more-not-just-more) about the importance of protecting time for thinking rather than just doing more. That instinct has only intensified. The volume of what's possible—the [constant iteration](/blog/2026-02-21-coding-as-sculpting), the ability to move from idea to working thing in hours—creates a kind of cognitive pressure that's hard to articulate. It's not burnout exactly. It's the weight of permanent opportunity.
## The Analog Response
I've been reading Cal Newport's *Slow Productivity* and finding myself drawn to its central argument: do fewer things, work at a natural pace, obsess over quality. One of his key moves is cutting out the small—eliminating the overhead, the administrative debris, the low-value tasks that fragment your attention. AI should be perfect for this. It can handle the small so you don't have to. But in practice, AI often does the opposite: it generates more small. More options, more threads, more things to review and react to. The tool that should free your attention ends up consuming it. (Sounds like computers, email, and Slack all over again.)
Ideas need time to breathe. They need to arrive half-formed and sit for a while. They need to collide with other half-formed thoughts before they're worth pursuing. So I've been reaching for analog forms. Walking without headphones. Notebooks. And increasingly, voice.
## Speaking Instead of Typing
For the record: this is not about whispering to the AI. Voice-as-input for AI has its own merits and is widely popular with developers. This is something different.
Voice recording is new for me as a thinking tool. I've always been a writer—capture everything in text, process it, turn it into something. But I've noticed that the act of typing pulls me into editing mode. I start structuring before the thought is fully formed. The tool imposes its own pace. (Even [seeing words transcribed in real time](/blog/2026-03-11-dont-watch-the-words) has the same effect.)
Speaking is different. When I record a thought, I'm not organizing it. I'm not formatting it. I'm just externalizing it—getting it out of my head and into the world before my internal editor can intervene. The capture happens at the speed of thinking, not the speed of processing.
This matters more than I expected.
## The Gap Between Capture and Processing
There's a tension here. I want my ideas captured and fully processed, but without requiring my presence or attention.
I want voice notes transcribed. I want them searchable. I want them available to AI when I'm ready to work with them—as context for a [broader knowledge base](/blog/2026-02-21-context-repository), as triggers for workflows, or simply as a searchable archive of thinking. All of that should happen. But it shouldn't need me there watching it. The moment of capture should be frictionless and human-paced. Everything after that is the machine's job.
The immediate feedback loop that makes AI so powerful is exactly what makes it exhausting. You say something and it responds. You iterate. You refine. And suddenly you're an hour deep into a direction that started as a passing thought—one that deserved to remain a passing thought for a while longer.
## Async by Design
What I'm describing is an intentionally async relationship with AI. Capture now. Let the machine process on its own time. Think at human speed, and let AI do its thing—but on your terms, not its.
I'm not rejecting AI. I'm refusing to let it set the pace. The capture layer should be calm, immediate, low-friction. No screens if possible. No feedback loops. Just: record the signal.
The processing layer can be as sophisticated as it needs to be. Transcription. Summarization. Organization. Integration with the tools you already use. All of it can happen—just without demanding your presence or attention. You don't need to be in the loop for the machine to do its work.
## The Discipline of Space
*[Of all the things you can now do, which do you choose to do?](/blog/project-tree-2025)* That question still sits at the center of working with AI. But there's a prior question that doesn't get enough attention: **when** do you choose to do them?
Not every captured idea needs to become a task. Not every thought needs immediate follow-up. Some of the best ideas are the ones that sit untouched for days and are still compelling when you return to them.
The discipline isn't in doing more with AI. It's in preserving the space where ideas form without AI demanding your attention. I'm setting up my own workflows so I can trust that the infrastructure works whether I'm watching or not—that nothing is lost by stepping away from the screen while the back end does what it does.
The hard part isn't the technology. It's embracing—and demanding—that AI does its job without you supervising every step. Until you're ready to collaborate.
---
## Sculpting with Code
> Working with AI has shifted my design process from building up to carving away, revealing the essential shape hidden within.
Traditional coding is additive. You start with nothing and build up, layer by layer, until the thing exists. Working with AI has inverted this for me. Now I start with a mass of material and carve away until what remains is essential.
The process feels closer to sculpting than construction.
## Starting with Clay
[You give the AI context. Lots of it.](/blog/2026-02-21-context-repository) The problem space, the constraints, examples of what you're after. It generates something fairly complete. Not perfect, but substantial. A block of marble with a figure somewhere inside.
Then the real work begins. Not adding more, but removing. Stripping unnecessary UI elements. Tightening the interaction until it feels inevitable. **You're not building toward a vision. You're revealing it.**
This happens at every level. Capabilities get scoped down. Screens get consolidated. Buttons disappear. What started as a sprawling possibility space contracts into something focused and coherent.
## A Different Manifestation
Recently I was reworking a piece of existing software. Rather than patching features onto what existed, I started fresh by defining a new object model with the AI. Just the core entities and their relationships. Nothing else.
What emerged wasn't an improved version of the old thing. It was a fundamentally different manifestation of the same problem. The new structure suggested interactions the old architecture couldn't support. Constraints that felt arbitrary before now had clear reasons, or vanished entirely.
The shape was always there. The old implementation had just obscured it.
## Malleable Material
This is what working with malleable material feels like. Clay doesn't resist. You can push it around, see what happens, pull it back if it doesn't work. The cost of exploration drops to nearly zero.
But the discipline remains. Knowing when to stop removing. Recognizing when you've found the essential form. That judgment doesn't come from the AI. It comes from years of craft, applied to a radically different process.
---
## Building a Context Repository
> A practical approach to making AI actually useful: translate your company knowledge into a structured, version-controlled repository that AI can reason from.
Everyone talks about context being critical for getting useful results from AI. This is a practical recap of how that has worked for me. The principles are solid, but you can implement them many ways. Here is one.
## The Approach
I used Claude Code to ingest a lot of company context and capture it as markdown files in a hierarchical structure. The process was straightforward. Reference existing resources. Have AI parse PDFs, slide decks, documentation. Connect to other systems via MCP. The key was translating everything into a repository of AI-readable (and human-readable) context.
It's rare that this information just sits around neatly organized. But AI can help sort through and structure it. Merging information from multiple sources. Removing duplication. Resolving inconsistencies. What would take weeks of manual work happens in hours.
## The Structure
The result includes:
**A strategy kit** covering core positioning, competitive advantages, ICPs and personas, use cases, proof points, markitecture, and pricing.
**Brand guidelines** with voice and tone, logo usage, colors, typography, and visual elements.
**A product kit** with detailed capabilities and API documentation.
This is what it looks like:
```
├── brand-guidelines/
│ ├── voice-and-tone.md
│ ├── logo.md
│ ├── colors.md
│ ├── typography.md
│ ├── visual-elements.md
│ └── ...
├── strategy-kit/
│ ├── core-positioning.md
│ ├── competitive-advantages.md
│ ├── product-suite.md
│ ├── icp-and-personas.md
│ ├── problem-positioning.md
│ ├── use-cases.md
│ ├── proof-and-customers.md
│ ├── markitecture.md
│ ├── pricing-and-packaging.md
│ └── ...
├── product/
│ ├── capabilities/
│ ├── api/
│ └── ...
└── output/
```
## Git as the Foundation
I put it all into a git repository. Version control for company knowledge.
I also had Claude Code add a static site generator so the content can be viewed and deployed in a human-friendly format. GitHub Pages works well for this. But the main payload is the set of markdown files covering all company essentials, organized in a logical file structure.
You can reference this repository as a submodule in another project, or simply use it as context when starting new work. Either way, everything AI generates from this point forward is informed by the precise context of the company.
## From Generic to Specialized
This is where the leverage appears. Results go from generic to highly specialized and relevant. On par with what long-time employees hold in their heads, often beyond it, because the AI can synthesize across all the documented context simultaneously.
Strategy documents. Product specs. Feature definitions. Marketing copy. All of it informed by the same coherent base of knowledge.
The generated outputs, when they are text, live in the same repository. I created an output folder. Now you can reference and iterate from that growing body of work. Fold insights back into the main context. The repository becomes a living system, not a static archive.
Pricing changes? Just tell AI what they are and have it apply the changes. No need to maintain this manually. Odd result? Ask for the source and update it as needed.
## A Reasoning Partner
All of this happens conversationally. You're not just generating documents. You're reasoning with a partner who holds all the relevant knowledge for your specific situation.
I use this constantly in my design process. AI generates entire workflows, diagrams, prototypes, and working code, all grounded on this foundation. Features can be scoped against real constraints. Positioning decisions can be pressure-tested against actual competitive dynamics.
**Context is the difference between generic output and genuinely useful work.** And because it lives in a shared repository that is agnostic to the LLM you use, anyone on the team can benefit. Claude Code? Codex? Cursor? You do you.
No need to buy into someone else's tool or tooling. This is all about you and your context. You don't need somebody else's opinionated PM or design tool. They just get in between you and outcomes.
---
**PS:** With MCP you could connect directly to existing systems, but clean, authoritative sources are rare. In practice, I use MCP to publish to those systems or pull in new information. Fast evolving space, but this workflow holds up.
---
## Chaos Studies: Where Math Meets Music Meets Touch
> Turning a fascination with strange attractors into an immersive audiovisual experience, from Playdate to iOS and macOS.
Rotate your view and the bass slides behind you. Zoom in and the particles fill your screen. The attractor never repeats, but it never escapes either. It's hypnotic in a way that's hard to explain until you've sat with it.
What started as a [coding experiment with strange attractors](/blog/lorenz-attractor) is now available as [Chaos Studies](https://chaosstudies.app/) for iOS and macOS. An immersive experience that combines my interests in math, music, and art into a single interactive canvas.
## From Playdate to Full Power
The first version of Chaos Studies was built for the [Playdate](https://play.date/), a tiny handheld with a crank and a 1-bit display. That constraint forced me to think about what mattered most: the visual rhythm of particles tracing their deterministic-yet-unpredictable paths, and the physical delight of manipulating chaos with a crank. The computational demands of tracking and moving thousands of points exceeded what the delightful Lua language could handle, requiring a custom C module.
Porting to iOS and macOS meant shedding those healthy constraints. More raw power. Full color. Room for more parallel spatial audio. Multi-touch. The Metal rendering pipeline. But the core idea remained the same: give someone direct, tactile control over a chaotic system and let them feel its behavior.
## Nine Windows into Chaos
The app features nine strange attractors, each with its own character. The iconic Lorenz is restless, tracing its familiar butterfly wings. Rössler feels meditative, spiraling in toroidal bands. Halvorsen is architectural, exhibiting striking crystalline symmetry. Chen extends Lorenz into more turbulent territory. Each attractor required its own tuning until it felt right. Fast enough to see the dynamics unfold, slow enough to follow individual particle paths.
## Particles with Memory
Thousands of points trace paths through phase space. Each point starts hot—literally rendered in red—and gradually cools as it ages, creating trails that show where the system has been while emphasizing where it's going. When points grow cold enough, they drift outward and fade, replaced by fresh particles that continue the integration.
The recycling strategy took iteration to get right. Early versions replaced points randomly, which looked jittery. The final approach prioritizes replacing the coldest points first, creating smooth visual decay.
Metal handles the rendering across multiple pipelines.
## Sound That Moves Through Space
At its core is the cursor synthesizer—a real-time oscillator highlighting the current particle as it traces through phase space. Velocity controls the bass frequency (deliberately matching the Playdate version), vertical position adds harmonics, and a low-pass filter opens up with faster movement. The stereo field tracks your horizontal position.
Layered over this are seven music stems, each positioned in 3D space: tings float above, pad drones sit below, percussion anchors the front, bass line to the right, cello behind. As you rotate the camera, the stems pan and attenuate based on their new positions relative to your viewpoint. Headphones reveal the full effect—rotating the attractor literally rotates the soundscape around you.
The stems were composed on the OP-XY by Teenage Engineering (who also helped Panic design the Playdate hardware). I split the composition into spatial tracks specifically for this purpose.
The explosion and implosion effects layer multiple synthesized sounds with careful timing—details that took tuning to make the visual experience feel visceral. Getting the mix right across tiny built-in speakers and expensive headphones took more iteration than I expected.
## Art for Art's Sake
There's no goal. No score. No puzzle to solve. Chaos Studies exists purely as an experience—[art that doesn't need to serve a purpose beyond itself](/blog/art-design-purpose). Something to sink into, manipulate, and watch unfold. It's the kind of project that might never have existed without the ability to explore ideas quickly enough that "just for the joy of it" becomes a reasonable justification. But that freedom doesn't replace the discipline of refinement—it just means you can afford to be ambitious about what you refine.
## A Convergence of Interests
Chaos Studies sits at an intersection. It harkens back to creating visceral experiences in the game industry. It taps into my knowledge of electronic music and sound synthesis. It draws on design at large and the craft of interactive software. And it touches on math and the philosophical implications of chaos.
## Try It
Chaos Studies is available on [the App Store](https://chaosstudies.app/) for iPhone, iPad, and Mac. Put on headphones. Manipulate the chaos. Let the sound move around you.
In a world optimized for engagement metrics and endless algorithmic feeds, software that simply asks you to slow down and explore feels like a breath of fresh air.
---
## Converging on Reality
> Machine learning models across languages, molecules, and proteins are converging toward similar representations—a hint at underlying structure.
From [Ethan Mollick on LinkedIn](https://www.linkedin.com/posts/emollick_recently-llms-were-found-to-encode-different-activity-7411757757713907713-QjVu):
> Recently, LLMs were found to encode different languages in similar ways, suggesting a sort of Platonic representation of words.
>
> It now extends to science: 60 ML models for molecules, materials & proteins (all with different architectures & training data) converge toward similar encodings of molecular structure.
>
> As models improve, they agree more on what makes two molecules "similar." They may be converging on a shared representation of physical reality (but models are still constrained by their data).
I find this a fascinating hint at an underlying structure of information and reality.
Give [Ethan](https://www.linkedin.com/in/emollick/) a follow—he's a consistently considerate and often humorous source of insights on all things AI.
---
## A Map of Gaps
> Why knowing what you're bad at matters more than knowing what you're good at—for learning, for work, and for building teams that actually complement each other.
Had a good conversation with a candidate recently about strengths and weaknesses. Not the usual interview dance where weaknesses get reframed as strengths in disguise. An honest exchange about what we're each not good at and how we compensate.
It reminded me how rarely we talk about this directly—and how enabling it is when we do.
## The Real Skill
Knowing your strengths tells you where to deploy yourself. But **knowing your weaknesses tells you who you need around you**.
That's the more useful map. Not a catalog of what you're good at, but a clear picture of the gaps—and a strategy for filling them by leaning on others who are strong where you're not.
This isn't about self-deprecation. It's about self-awareness that actually leads somewhere. If I know where I fall short, I can seek out collaborators, build teams, and structure work in ways that compensate. The gaps become a design constraint, not a liability.
## A Career Theme
Looking back, the most enabling pattern in my career has been exactly this: finding people whose strengths complement my weaknesses, and offering the reverse.
It changes how you hire. Instead of looking for people who are good at the same things you are, you look for people who cover what you can't. It changes how you collaborate. You stop pretending you can do everything and start [trusting others](/blog/let-go-and-trust) to handle what they're better at. It changes how you grow. You stay humble about your limits and curious about improving them, which is the [growth mindset](/blog/praise-effort-not-talent) in practice.
The alternative—projecting competence in every direction—is exhausting and brittle. Eventually the gaps show up anyway. Better to know them, name them, and build around them.
## Why It's Hard
We're trained to emphasize strengths. Performance reviews, job interviews, professional branding—all of it pushes toward articulating what you're good at. Admitting weakness feels like giving something away.
But teams built on pretense fail in predictable ways. Everyone is covering gaps that nobody acknowledges. When those gaps finally surface, there's no structure to handle them.
I'd rather work with people who can say clearly what they're not good at. It makes everything else more trustworthy. If someone knows their limits, I can trust their confidence in other areas.
## The Map Worth Making
So here's the question worth sitting with: what are you bad at? Not as an exercise in humility for its own sake. But as real intelligence about who you need, what you should delegate, and where you still have room to grow.
The map of gaps is a blueprint for the career you actually want—one where you're not trying to be good at everything, but building something better by leaning on others.
---
## The One Thing Constraint
> Good science fiction changes one thing and builds a world around it. Can the same work in product design?
The best science fiction worlds feel inevitable. Not because they're familiar, but because they're coherent. Pick one impossible thing—teleportation, immortality, telepathy—and trace every consequence. The world builds itself from that single change.
Change too much and it falls apart. The reader stops believing.
## The Credibility Problem
When a science fiction world has teleportation *and* telepathy *and* time travel *and* magic crystals, you start to notice the seams. The writer is just adding whatever feels convenient for the plot. The world loses internal logic. It stops feeling real because nothing holds it together.
The single change is what creates credibility. It forces the author to think through implications. If everyone can teleport, what happens to cities? To borders? To privacy? To crime? To relationships? The one thing ripples outward, reshaping everything it touches in ways that feel inevitable.
That discipline is generative. It creates the world.
## Playing With One Change
I've been doing this lately with product ideas. Pick one change and follow it. **What if just one element was different?**
No database. Everything in the browser. No cloud, local only!
Each one reshapes what's possible. "No database" pushes you toward local-first, toward what can live in memory, toward sync without a source of truth. "Everything in the browser" surfaces URL encoding, WebAssembly, service workers—a completely different architecture.
The change propagates. That's the point.
## Why One Thing Matters
Without that singular change, you follow well-worn patterns. Use a database because that's what you do. Put it in the cloud because everyone does. The solutions are familiar because nothing pushes you to reconsider.
Change too many things at once and you're just listing preferences. "I want it fast *and* beautiful *and* cheap *and* flexible *and* simple." Those aren't changes. They're wishes.
But change one foundational element—one thing that affects everything else—and your brain has to leave the path. You're world-building. The single change isn't a limitation—it's permission to think differently.
## The If If If
The questions are cheap: *if if if*. But following one all the way through is hard. It means resisting the urge to compromise, to add just one more exception, to let the change slip when it gets uncomfortable.
Good science fiction stays disciplined. It picks one impossible thing and makes everything else follow. The world feels real because it's consistent, because the author did the work of thinking through implications instead of just inventing conveniences.
Good product design can work the same way. Pick one change that matters. Follow it to its conclusion. See what world it builds.
---
## From Sketch to Site in Hours
> Building Field Bureau + Werkstatt, a minimal site born from a journal sketch and iterated into existence.
Field Bureau + Werkstatt is an independent design and technology practice. Bureau for analysis and discernment. Werkstatt for experimentation and craft. Field for real-world context and iteration.
The design tries to capture and reflect that ethos. So does the process of making it.
## Bureau, Werkstatt, Field
**Bureau:** I developed the key concept and captured it in a minimal (and tiny!) sketch in my journal. Just the essentials: logo, concept, navigation.
**Werkstatt:** Initial implementation was quick thanks to AI. Then came the real work: spacing, typography scale, color values, image treatment. Design decisions that require looking, adjusting, looking again.
**Field:** A timely design critique with [John](https://www.johnwlong.com/) brought real-world perspective that refined the final result.
I like it best on desktop (see screen) but it scales nicely to mobile too. Learn about [Field Bureau + Werkstatt](https://fieldbw.com).
---
## In Appearance Only
> Unintentional imposters optimizing for output over outcome. AI just does it even better.
AI content often looks right, if not perfect. The structure is there, the format is correct, the polish is undeniable. Yet it can feel hollow—disconnected from genuine understanding.
We act like this is new. Like AI invented producing work that meets expectations in form while missing the substance. But we've been doing this for decades.
## Output Without Outcome
Watch a product team doing everything by the book. They're running sprints, conducting user research, building roadmaps, measuring metrics. All the outputs are there: personas, journey maps, OKRs, retrospectives. Perfect artifacts.
And yet the outcome is off. The product doesn't solve the problem. The features miss the mark. The strategy feels hollow.
Or look at design work that seems deeply researched. Stunning presentation, articulate rationale, sophisticated visual language. All the outputs of good design. But in practice, it doesn't serve users well. The outcome reveals the disconnect.
These frameworks and practices were invented for good reasons. Sprints were meant to break down complexity and enable rapid feedback. User research was meant to surface real needs before building. OKRs were meant to align teams around meaningful outcomes. They all emerged to solve real problems, and they work brilliantly—if you understand what problem they were trying to address.
But somewhere along the way, **the outputs became the goal**. Following the process became the measure of success. Creating the right artifacts became what "good" looked like. The work became performance.
## Organizational Imposters
The eerie part is how many people in organizations are unknowingly just pretending. They're not malicious. They're not consciously deceiving anyone. They've simply learned the patterns that signal competence and reproduce them faithfully. They know how to structure the presentation, format the document, run the ceremony. They're fluent in the language of their discipline.
But they've never connected it back to the original problem these practices were meant to solve. They're **imposters who don't know they're imposters**, because everyone around them is also checking whether the form is correct, not whether the substance is there.
## The Mirror
This is what's eerie about AI. It's extraordinarily sophisticated at meeting human expectations in form—more sophisticated than most people at matching expected patterns. It produces the right structure, the right tone, the right surface markers of competence.
But it's doing exactly what we've been doing: producing output that looks right without ensuring the outcome is right. The difference is that we're more critical of AI. We scrutinize its work with skepticism we rarely apply to human output. But that's already fading. AI's level of sophistication makes it increasingly hard to tell the difference.
When humans do it, we're often numbed to it. We've been swimming in it so long we stopped noticing.
AI shows us what our own work looks like when you strip away intent and understanding but keep the form intact. It's learned from everything we've produced, including all the work that looked right but wasn't. It reproduces the patterns we rewarded, the structures we validated, the forms we approved.
And we seem to like what we see.
## What This Means
I've been looking for the unintentional imposters for years. The ones who argue most forcefully for doing things right, for following process. They're often the ones most disconnected from why those processes exist. They've mistaken the map for the territory.
And with AI, the lesson is clear: to get value out of it, you have to **hold it accountable to purpose, not form**. Don't judge its output by whether it looks right. Judge it by whether it achieves the outcome you need. The same standard we should have been applying to human work all along.
The appearance of good work has always been the easiest thing to fake. Now we just have a mirror that makes it impossible to ignore.
---
## Embracing Interface Asymmetry
> Visual UIs and chat interfaces have opposite strengths. The asymmetry isn't a problem to fix; it's a pattern to embrace.
I've been reflecting on the friction between traditional UIs and AI chat interfaces. We've been forcing both input and output through the same interface paradigm for decades, and it's never worked well for both.
Visual interfaces are spectacular at one thing: showing you information. A map instantly conveys distances and relationships that would take paragraphs to describe. A dashboard lets you compare metrics at a glance. Product grids let you scan prices and features faster than any text summary could. When computers need to help us understand information, visual representations are unmatched.
But flip it around. Try to *tell* a computer what you want through those same visual interfaces.
Now you're clicking through nested menus, filling out forms with rigid validation rules, hunting for the right checkbox buried in settings. You're learning someone else's mental model of how data should be structured, memorizing which field goes where, adapting your intent to fit their predetermined categories. Every app has its own idiosyncratic input patterns. Every form demands you think like the database schema.
The sophistication we've built into visual output doesn't translate to input. It compounds complexity instead of absorbing it.
## The Inverse Interface
AI chat interfaces flip this entirely. They're phenomenal at input. You describe what you want in whatever words come naturally. You provide context in whatever order makes sense to you. You correct yourself mid-sentence, add caveats, reference things indirectly. The interface does the work of parsing intent, mapping your messy human input onto structured operations.
But ask a chat interface to help you compare options, and you're back to scrolling through paragraphs. Which hotel was cheaper? What were the trade-offs between those three approaches? The information is there, but you can't *see* it. Text forces sequential processing when what you need is spatial reasoning. It's the wrong medium for output.
The asymmetry is perfect. Visual interfaces fail where chat interfaces excel. Chat interfaces fail where visual interfaces excel. We've been stuck with one paradigm for decades: visual UIs for everything, input and output both forced through the same forms and buttons. Now we're adopting the other, wrestling with how to make chat and text convey what images show instantly. But the asymmetry isn't a problem to solve. We ought to embrace it.
## No UI for Input
What if the pattern that's emerging isn't "chat replaces everything" but something more surgical? Free-form text input (or spoken words) becomes the universal input layer. Describe what you want, refine it conversationally, express complex intent without learning app-specific conventions. Then, once the system understands, render the results in whatever visual form makes them comprehensible. Generate the dashboard. Show the map. Display the comparison grid.
The interface adapts to the output, synthesized on the fly based on what you asked for. Not a predetermined layout you're forced to interpret, but a visualization shaped by your specific question. The understanding of this asymmetry adds another level to something I wrote about [ephemeral software](/blog/2025-10-15-ephemeral-software). Traditional software isn't just wrong because it persists when it shouldn't. It's wrong because it forces a single interface paradigm to handle both directions of interaction. Code and interfaces should both manifest when needed and dissolve when done, but they should also split along natural lines: natural language for expressing intent, visual forms for understanding results. The output interface becomes just another part of the computation that appears in service of your purpose, then vanishes.
I've noticed this in my own projects lately. The friction isn't usually in viewing results; it's in communicating what results I want. The cognitive load isn't in understanding the data but in wrangling the controls.
This changes what we should be building. Stop trying to make chat interfaces that output everything as text. Stop trying to make visual UIs with better input forms. Instead, build systems that accept natural language input and generate the right visual representation for each specific query. The interface becomes a consequence of the question you asked, not a constraint you have to work within.
For designers and builders, this means rethinking the fundamental unit of interface design. Not "design a dashboard" or "design a form," but "design a system that can synthesize the right output format in response to expressed intent." The interface isn't the product; the capability to manifest appropriate interfaces is the product.
What would your tools look like if input and output weren't bound to the same interface?
---
## Turning the Ship
> Why organizational change takes time, why resistance is normal, and why momentum eventually works in your favor.
Changing organizational direction is like turning a massive ship. The larger the organization, the more this metaphor holds true.
You can't just yank the wheel and expect immediate results. The momentum of the existing direction carries the organization forward, resisting change.
I wrote about why [direction matters more than speed](/blog/direction-before-speed) in organizational momentum. But knowing where you want to go is different from actually getting there. I've seen this pattern enough times to know where people give up and where they push through.
Whether you're an executive, a team lead, or an individual contributor trying to drive change—the dynamics are the same. You're working against existing momentum, and that takes sustained effort regardless of your title.
## Many Small Pushes
Change happens through many small pushes, not one dramatic shift.
Each decision, each meeting, each communication that aligns with the new direction adds a small force vector. Initially, these forces seem insignificant against the massive momentum of the current direction.
But not all pushes are equal. The key is finding the levers that make the biggest difference. Some decisions cascade through the organization—who gets hired, what gets measured, which projects get funded, how teams are structured. These aren't just small pushes; they're force multipliers that touch everything downstream.
I've learned to look for these leverage points early. Where does attention naturally flow? What decisions do people watch to understand what actually matters? Those are your levers. Push there, and the effect compounds far beyond the immediate action.
Your levers look different depending on your position. An executive controls funding and structure. A team lead influences what gets celebrated and who gets hired. An individual contributor shapes technical direction through code reviews and architecture proposals. But the principle is the same: find where small actions create outsized impact.
Momentum is cumulative. Over time, these small pushes—especially the ones applied to the right levers—begin to add up. The ship starts to turn, slowly at first, then with increasing speed.
## The Resistance Phase
The most challenging period is the early phase, when you're pushing against existing momentum. This is when change initiatives often fail—leaders give up because they don't see immediate results. They expect the ship to turn on a dime, and when it doesn't, they conclude the effort is futile.
But this is exactly when persistence matters most. The resistance you're feeling is the organization's existing momentum pushing back. It's not a sign that change is impossible—it's a sign that you're pushing against something real.
Every decision is questioned. The old ways keep reasserting themselves. Progress is invisible or easily reversed. You're constantly explaining the same things. Exhaustion sets in for change leaders.
This is normal. This is the physics of organizational change.
## The Tipping Point
There comes a moment when the cumulative effect of all those small pushes reaches a tipping point. The ship's direction is changing, even if it's barely perceptible at first. This is when the change becomes self-reinforcing, when the organization's own momentum starts working in your favor.
At this point, something remarkable happens: the change becomes unstoppable.
The organization begins to generate its own momentum in the new direction. People start making decisions that align with the new direction without being told. The culture begins to shift naturally. New hires come in and assume this is just "how we do things here."
## When to Ease Off
Here's the counterintuitive insight: once the ship is turning, you need to ease off.
Just as it took sustained effort to start the turn, it will take sustained effort to stop it. The momentum that was working against you is now working for you. The change itself becomes inevitable.
This is why over-correction is a real danger. I've seen leaders who fought hard to initiate change not realize when the battle is won. They keep pushing with the same intensity, and the organization overcorrects, swinging too far in the new direction.
The art of organizational change is knowing when to push hard and when to guide gently. Early on, you push. Once momentum shifts, you steer.
## Why Change Feels Inevitable in Retrospect
Early-stage change feels difficult. Successful change feels inevitable in retrospect. The work you do in the resistance phase creates the foundation for the acceleration phase.
People who join after the tipping point can't imagine the organization any other way. They wonder what the big deal was. "Of course we do it this way," they say.
## What This Means for You
If you're driving change—at any level—start by identifying your levers. Where can you apply force that creates the biggest impact? This looks different depending on your position, but the principle is the same: find the decisions and actions that cascade.
Commit to sustained effort during the resistance phase. Don't expect immediate results. Celebrate small wins that align with the new direction. Keep communicating the why, relentlessly. Build a coalition of people pulling in the same direction.
After the tipping point, recognize when momentum has shifted. Ease off the intensity of your push. Guide rather than force. Watch for overcorrection. Let the organization's own momentum do the work.
Organizations that succeed in transformation understand they're playing a long game. They know that turning a ship takes time, that resistance is normal, and that once the turn begins in earnest, it becomes self-reinforcing.
Patience during the resistance phase. Recognition when the tipping point arrives. That's how you turn the ship.
---
## Direction Before Speed
> Why organizational momentum is a vector, and why moving fast in the wrong direction is worse than moving slowly in the right one.
Organizational momentum is a vector—it has both direction and magnitude. Without clear direction, increased speed only means you're getting lost more quickly.
I've watched this play out enough times to know the pattern. The fundamental truth is that **direction is everything**. You can have the fastest, most efficient execution in the world, but if you're heading in the wrong direction, you're just accelerating toward failure.
## The Vector Problem
I've seen organizations pride themselves on execution speed while drifting aimlessly. They measure velocity, track velocity, optimize for velocity—all while ignoring that velocity is a vector quantity. Without direction, speed is meaningless.
Even worse: scattered efforts across multiple directions. When your team pulls in five different directions with equal force, you don't get slow progress—you get zero progress. The vectors cancel out. All that effort, all that motion, adds up to nothing.
This is why alignment matters more than hustle. A team moving slowly but in the same direction will outpace a team sprinting in different directions every time.
This applies whether you're leading an entire organization, a team, or trying to drive change from any position. The physics are the same.
## The First Question
The first question should always be: **Where are we going?**
Only after that's clear should you ask: **How fast can we get there?**
This seems obvious when stated plainly, but I've seen organizations do the opposite. They start with execution, with process optimization, with speed improvements. They assume direction is already set, or that it will emerge from the execution itself.
It rarely does.
Organizations that succeed get religious about direction. They communicate it relentlessly. They use it as a filter for every decision. They're willing to say no to perfectly good ideas that point the wrong way.
## What Misdirection Costs You
Speed without direction doesn't just waste effort—it actively destroys value.
Teams build features nobody needs, faster. Engineers solve the wrong problems, more efficiently. Meetings proliferate to coordinate conflicting efforts. Burnout increases as people work harder for less impact. Morale drops as people sense the futility of their work.
It burns out your best people on meaningless work. It creates organizational debt that's harder to unwind the longer it continues.
## Getting Direction Right
Setting direction isn't about having a perfect vision from day one. It's about being clear enough that people can align their efforts.
When everyone can articulate where the organization is headed, decisions become easier because you have a filter. You can say no to good ideas that point the wrong way. Individual efforts compound instead of canceling out. Progress becomes visible and measurable.
## Why Speed Still Matters
None of this means speed doesn't matter. It does—tremendously.
When you can move fast, you reduce the cost of being wrong. If you can fix your mistakes as quickly as you make them, you can afford to make mistakes and learn from them. Speed reduces the need for slow deliberation because the feedback loop is tight enough that errors become cheap.
This is why the sequence matters so much. Direction first, then speed. With clear direction, speed becomes your advantage. Without it, speed just amplifies your mistakes.
Of course, setting direction is only the beginning. Actually changing an organization's direction—getting everyone aligned and moving together—is a different challenge entirely. I explore that in [Turning the Ship](/blog/turning-the-ship).
---
## Praise Effort, Not Talent
> How cultural differences in praising children shape mindset and what it means for how we raise our own kids.
I learned this years ago, but it stuck: in many cultures, when a child does something well, they hear "it shows how much you worked on this." In the US, that same kid often hears "you're so talented."
The difference is profound.
## Attribution Matters
One response attributes success to effort—something entirely within the child's control. The other attributes it to inherent talent—something fixed, something they either have or don't.
This isn't just semantics. It shapes how children understand success and failure. If you believe your achievements come from talent, what happens when you struggle? You assume you've hit your limit. If you believe they come from effort, struggle means you haven't worked hard enough yet.
## The Fixed vs. Growth Mindset
This is the difference between a **fixed mindset** (talent-based) and a **growth mindset** (effort-based).
Kids with a growth mindset embrace challenges as opportunities to improve. They persist through setbacks, see effort as the path to mastery, and learn from criticism. Kids with a fixed mindset do the opposite—they avoid challenges that might expose limitations, give up when things get hard, and take criticism personally because it threatens their self-image.
The mindset we foster through our words has real consequences.
## How I Practice This
I learned about this distinction when my first daughter was just born. It became something I internalized immediately—a lens I couldn't unsee once I understood it.
From the beginning, I've been intentional about how I praise. My instinct is still to say "you're so smart" or "you're naturally good at this." It feels good to say. Kids beam when they hear it. But I've trained myself to pause and reframe. Instead of "you're so talented," I say "I can see how hard you worked on this." Instead of "you're so smart," I say "I love how you figured that out." Instead of "you're a natural," I say "your practice is really paying off."
It's not always easy. The fixed-mindset language is deeply embedded in how we talk. But I've been doing this for years now, and it's become second nature.
## The Real Block Isn't Talent—It's the Belief in Talent
This isn't just about how we raise kids. It's about the limiting beliefs we carry about ourselves.
How many people say "I'm not good at math" as if it's an immutable fact about who they are? Or "I'm not creative" or "I'm not athletic" or "I don't have a technical mind"? These aren't statements about reality—they're self-fulfilling prophecies that become true precisely because we believe them.
The notion of talent is a real block. It gives us permission to stop trying. It lets us off the hook. "I'm just not wired that way" becomes an acceptable reason to never attempt something, never struggle, never improve.
I genuinely believe I could learn to do anything because the brain is remarkably good at learning things. I may be too lazy to put in the required time. I may be too old to justify the investment. But that's not a problem of potential—it's a problem of priorities and effort.
When we shift from "I don't have the talent" to "I haven't put in the time," everything changes. The barrier isn't who we are. It's what we're willing to do.
---
## Apple's Quiet AI Advantage
> Why the M-series neural engine may prove that Apple's so-called lag in AI is actually a head start in on-device intelligence.
What if the real AI inflection point is happening on my desk instead of in the cloud? That question keeps circling back every time someone insists Apple is “behind.”
The usual scoreboard about foundational models and their ever-increasing capabilities barely mentions what happens on the device in front of us. Apple has spent nearly a decade weaving neural hardware into phones, tablets, and Macs without turning it into a hype cycle. Those chips feel less like a spec race and more like a quiet promise: the intelligence you rely on should live where you already work.
## An Invitation Hiding in Plain Sight
Apple Intelligence was announced without fireworks. The feature list reads tame: writing tools, notification triage, a few system-level assistants. Yet the developer sessions were unmistakable in tone. Apple wants us to bring our workloads onto their silicon. Every lab, documentation drop, and office hour circled the same idea: Apple Intelligence is a platform—tap into it, extend it, keep the experience private by default. The message is gentle but persistent: use the hardware, keep the data on device, lean into personal context.
## Quiet Proof Already Shipping
Even before Apple put a label on it, the devices were already soaked in intelligence. Voice Isolation makes a noisy café call sound like a studio. Center Stage tracks people across a room without broadcasting any frames to the cloud. Photos quietly does its thing so everyday shots just look great, no matter how chaotic the scene. These are everyday features, almost boring, and yet the amount of local processing required is just amazing. They are case studies for what happens when neural compute is treated as part of the OS instead of an add-on service.
## Owning Processing, Owning the Model
Cloud AI still matters when you need scale, but it turns every interaction into a rental. On-device work flips the model. The bill was paid when the hardware shipped. The data never has to leave the user’s hands. The relationship becomes less about metering usage and more about delivering capability that earns space on the dock or in the menu bar. That quietly challenges the SaaS mindset. **It resonates with me because nothing about having my work aggregated, mined, or owned elsewhere feels right anymore.** If the intelligence lives with the user, a subscription to access their own information starts to sound dated.
The trade-off, of course, is that Apple’s privacy stance and hardware guardrails slow the wild experimentation that fuels open cloud models. But that constraint is also why the results feel less volatile—grounded, human-scaled, and willing to wait until the pieces fit.
## Selfish Alignment
Apple frames privacy as a core value, but it is also a competitive wedge. Safari’s tracking protections, Mail Privacy Relay, and App Tracking Transparency all happen to blunt Google’s data collection while keeping users inside Apple’s ecosystem. Motivation aside, the outcome aligns with my selfish interest. My browsing history, my app habits, my daily routines are harder to harvest. Apple’s incentive to differentiate just happens to protect the way I want to work: locally, quietly, without negotiating away ownership every time I tap an icon.
## What If We Lean In
So the question is: what if on-device intelligence is the differentiator that matters? Apple keeps building the stage and inviting developers to plug in. Their own features set the baseline; it is on us to decide whether we will design for a world where users expect their machines to be the primary place where judgment and creativity happen. If the next wave of intelligence is personal, Apple’s head start isn’t in training models—it’s in training expectations.
---
## Let's Talk About Your Next Role
> Why I ask teammates to think about their CV and what they want it to look like five years from now.
At some point, a question like this shows up in my 1:1s:
> When a future hiring manager glances at this role on your CV five years from now, what should their takeaway be?
It never happens in the first coffee chat. Once we understand how we work together, we zoom out and talk about the future story they want other leaders to see.
## Why Call the Shot Early
At a certain level, companies aren't hiring your tool kit—they're hiring you to **replicate outcomes** you've already produced. "Built the X team" or "owned the Y process" sounds like a job description. "Delivered $40M in new revenue by rebuilding the onboarding funnel" tells a future boss exactly why you belong in their org.
Framing the job that way does more than prep them for the next jump. It forces clarity on what matters now. Regardless of level, outcomes will always trump output. When we align on the result we want to be proud of later, we automatically steer toward the kind of impact that multiplies through the org right now—better focus, cleaner prioritization, stronger partnerships. Those outcomes compound even if they never leave the company.
## So What Will Those Future Bullet Points Be?
I ask them to reflect on what those bullet points on their future CV ought to be, and to ignore for that moment whatever may seem urgent or important. That forces a clarity of thought that is disconnected from the day-to-day and surfaces the gaps we need to close.
My job is to build the environment where they can make the bullet points they identify genuinely true. We adjust scope, pull in partners, or hunt for the metrics we need. It might mean clearing space to own messy problems, lining up the execs who need to see the work, or defending the project long enough for the impact to register. The question shows up in future check-ins: are the bullet points they named getting sharper or fuzzier?
And to be clear: it is their work and their responsibility. I can coach and unblock, but they own the story they're writing.
When someone's CV tells a story of meaningful outcomes, leadership roles open up faster than anyone expects—and the current org benefits because it needs those same outcomes. That's the leverage I want them to feel, because it pushes better decisions in the day-to-day work and sets them up for whatever they want next, whether that's a bigger role here or somewhere else five years out.
What bullet points are you creating right now to set your current and future self up for success?
*P.S. If you wonder what constitutes an outcome, I’m partial to Joshua Seiden’s take in "Outcome over Output": it’s any change in human or customer behavior that drives business results.*
---
## Ephemeral Software
> In the age of AI, it's not the UI that becomes ephemeral—it's the software itself. Code manifests when needed and dissolves when purpose is served.
There's a narrative emerging around Apple's new liquid glass and similar interfaces: that **UIs are becoming ephemeral**, floating at the periphery, appearing only when needed and fading away when done. It's a compelling vision of unobtrusive design. But it misses the deeper shift.
It's not the UI that's becoming ephemeral. It's the software itself.
## Beyond Interface Design
The focus on ephemeral interfaces—glass panels that fade in and out, context-aware overlays that materialize at the right moment—treats the problem as one of presentation. Make the UI less intrusive, more elegant, more responsive to context, and you've solved the problem of software's constant presence in our lives.
But the software underneath remains. The application still exists, with its code, its dependencies, its update cycles, its presence on your device or in the cloud. We've simply made it quieter.
## Software as Manifestation
What AI enables is something fundamentally different: **software that manifests when needed and ceases to exist when purpose is served**.
Not hidden behind a subtle interface. Not sleeping in the background. But actually not there until the moment you need it, then dissolved once the need passes.
This is code as pure means to an end. No installation. No maintenance. No presence outside the context of immediate purpose. You don't think about "the software" or "the app"—you think about what you're trying to do, and the necessary computation simply happens.
## The Shift in Focus
Traditional software demands attention. Even with the most refined UI, you're aware of the application, its capabilities, its limitations, where it lives, when it was last updated. The software has identity and persistence.
Ephemeral software has none of that. It exists only in service of immediate purpose. The code that handles your request might be generated on the spot, executed once, and discarded. The "application" is just a pattern of computation that appeared, did its work, and dissolved.
This changes what software *is*. Not a thing you acquire and maintain, but a capability that materializes when invoked.
## Living at the Edge of Purpose
Apple's liquid glass and other peripheral interfaces are moving in the right direction—reducing the cognitive burden of constant interaction with software. But they're still designing containers for persistent applications.
The next step is software without containers. Without the assumption of persistence. Code that forms when you have a purpose and dissolves when that purpose is complete.
This doesn't mean software vanishes entirely—the infrastructure, the models, the systems that enable this manifestation all exist. But from the user's perspective, there's no software to manage. Only purpose, and the means to fulfill it.
## A Different Kind of Transparency
Transparent UI design tries to minimize the interface between you and your intent. Ephemeral software takes this further—interfaces still exist, but they're no longer rigid, persistent things. They manifest as part of the ephemeral software itself, appearing only to the degree necessary for the task at hand.
The focus shifts entirely away from the software itself—its design, its features, its presence—toward the outcomes it enables. Code becomes truly invisible, not through clever design but through fundamental impermanence. And interfaces become fluid, forming only when purpose demands and dissolving once that purpose is served.
## No Longer Science Fiction
Watch any science fiction film and you'll see interfaces that seem absurd by today's standards. Characters speak their intent and intelligence simply does their bidding. Systems understand context without explicit instruction. Capability materializes exactly when needed, in exactly the form required, then vanishes. No applications to open, no software to maintain, no visible machinery between thought and execution.
We've always dismissed this as fantasy—divorced from the practical reality of how software actually works. The messy truth of dependencies, installations, updates, compatibility, persistence.
But that gap is closing. What looked like magical thinking is becoming a tangible near-term future.
The intelligence exists. The infrastructure exists. The capability to generate, execute, and dissolve code on demand exists. What remains is the transition from thinking about software as something we build, install, and maintain, to software as something that simply happens when purpose demands it.
The science fiction version isn't about better interfaces. It's about the absence of software as a distinct concept. Just intelligence that manifests capability in service of intent. That future is no longer fiction. It's the logical endpoint of what we're building right now.
---
## Hiring Designers Who Know Which Lever to Pull
> The three non-negotiables I expect from senior designers: relentless feedback, selling the work, and knowing when each skill should lead.
I hire designers who can already run without a playbook. The skills I don't want to spend my time teaching are exactly the ones that keep teams moving when I'm not in the room.
Tools, systems, and product context are easy to transfer. Judgment is not. So I look for three signals before we ever talk about the UX architecture, the flows we’ll extend, or how the interface gets dressed.
## 1. Get and Use Feedback
Great designers do not treat critique as a chore. They *engineer* it.
They know when to show work early to unblock an assumption and when to wait until the stakes are higher. They arrive with specific questions, not just a deck. They synthesize what they hear into decisions, not transcripts. Most importantly, they close the loop—telling partners what changed and why.
If I have to coach someone to invite the right voices, to separate taste from risk, or to turn critique into direction, we're already behind.
## 2. Sell the Idea and Make It Happen
The best designers generate buy-in as they design. They narrate tradeoffs in plain language, expose decisions to the right people at the right time, and move ambiguity forward instead of letting it stall in Slack threads.
They can articulate *why* a path is worth pursuing in a way that product, engineering, and leadership understand. They listen for friction, adapt without losing the core insight, and know when to escalate versus when to absorb feedback locally.
If I’m the only bridge between design intent and team execution, the designer is not yet ready for the work I need done.
## 3. Choose the Right Lever
Feedback (1) and alignment (2) are levers. Judgment is knowing which one changes the system, and what happens if the wrong lever is pulled.
The right move might be to bring everyone together and realign the plan, or it might be to ship with the conviction the team already has. Feedback and alignment are critical tools of the trade; they only create value when they’re deployed with intent. Designers have to read the room, the roadmap, and the risk profile before pulling either lever. If you solicit feedback in a moment that demands conviction and alignment, you dilute momentum and signal you don’t actually believe in the direction. Worse is pushing hard to sell your idea when the room is offering critical insights you need to absorb—you burn credibility and miss the improvement. I need people who sense the difference and act without waiting for permission.
## What I Bring to the Table
When those skills are present, I can go all in on supporting them—removing blockers, sharing hard-won context, and opening rooms they need to influence. I can elevate their craft with sharper critiques, give them the space to run bigger experiments, and amplify their impact across the organization because [I trust their judgment](/blog/let-go-and-trust). That is the partnership I'm hiring for.
Without them, I'd spend my time teaching behaviors that should have been forged through earlier teams, mentors, and hard projects. That's a bad trade for everyone.
There's [plenty more](/blog/finding-balance-in-leadership) to forming a great design team—but being relentless about feedback, selling the idea, and choosing when to do which is not optional.
---
## Menu Volume – Feedback First, Features Second
> How shipping MIDI Volume Control proved that no project is too small to pivot when immediate user feedback points to the real product.
No project is too small to surprise you once you talk to customers. I shipped [MIDI Volume Control](/blog/midivol-app-store) a few days ago to scratch my own itch—see that post for the backstory. First desktop app, first trip through App Store review, first time I wired a MIDI controller directly into macOS volume. I assumed the follow-up conversations would be all about latency, channel support, controller mappings.
Instead, two friends saw it in action, bought it on the spot, and then told me they didn't care about MIDI at all—they wanted the instant menu bar control. That single conversation flipped the brief: *"The sliders are perfect. The MIDI stuff is extra."* They just wanted to keep Apple Music tucked under their work without losing the soundtrack.
I built the menu bar controls as a convenience. A bonus. A simple way to see and adjust system and Apple Music volume at a glance. Turns out that *was* the product for a whole group of people. The MIDI piece—the thing I started from—is still excellent for the much smaller crew who live with MIDI controllers (like me), but it's not the headline for everyone else.
## Pivot in Real Time
It would have been easy to treat that feedback as a feature request: add a toggle, maybe expose a minimalist mode, move on. But when two trusted friends—both seasoned product people—tell you the same thing in the same hour, that's not a feature tweak. It's a pivot.
So I split it.
Today I'm launching [Menu Volume – System & Music](https://kohlhofer.com/volBar/): the same clean menu bar interface, instant access to system and Apple Music volume, zero MIDI. No setup. No extra permissions. Just the part people actually asked for. If you run Apple Music while you work, this is the fastest way to keep it in check without interrupting whatever is on screen.
## Proof on a Small Stage
Customer-centricity isn't theoretical for me; it's the operating system. As a senior design and product leader, it's the principle I live by daily. It does not matter if it's a multi-million dollar product business or a personal side project—the same principle applies. Ship something—no matter how small—and the real brief lands in your inbox if you listen. This launch just happens to be the freshest proof point.
Menu Volume – System & Music exists because of that feedback loop. MIDI Volume Control still serves the musicians and producers who want full controller integration. Menu Volume handles everyone else. Both products are clearer versions of themselves now that they don't have to share the same story.
By the way, this was also an excuse to play with Apple's new Icon Composer. It made it easy and fun to dial in a liquid glass-compatible icon and export every size without touching the old tooling. See the screenshot above.
## What's Next
I'm keeping both apps in active development. MIDI Volume Control will keep growing for the people who live with faders and knobs. Menu Volume – System & Music will stay focused on being the fastest path to volume control on macOS.
Ship, listen, respond, repeat—because the discipline that keeps big products aligned with customers is the same discipline that makes a tiny menu bar app worth using, and user feedback rules supreme at every scale.
Menu Volume – System & Music is now [live on the Mac App Store](https://apps.apple.com/us/app/menu-volume-system-music/id6753698645). Give it a try, and let me know what you think. I'm listening.
---
## MIDI Volume Control: When the Solution Doesn't Exist, Build It
> How a simple need—controlling my Mac's volume with a MIDI controller—led to building my first desktop app, now available on the App Store.
I wanted to control my Mac's volume with a MIDI controller. That's it. A simple problem with what I assumed would be a simple solution.
I have a MIDI controller on my desk for music production. It has knobs and faders. My Mac has a volume. Surely, I thought, someone has already solved this. It's such an obvious use case—anyone with a home studio setup would want this.
[](https://kohlhofer.com/midiVol/)
But when I searched, I found old forum posts, abandoned GitHub projects, commercial apps that did way more than I needed, solutions that required complex setup. Nothing simple. Nothing that just worked. So I built it.
## The Solution
With AI assistance, I built it faster than I would have thought possible even a year ago. [MIDI Volume Control](https://kohlhofer.com/midiVol/) does exactly what I needed—control both system and music volume with any MIDI controller using MIDI Learn for automatic mapping.
But I added two features that turned out to be more valuable than I expected. First, separate control for Apple Music volume. This means you can keep music playing at a lower level during meetings without killing it entirely, then easily bring it back up after. Second, handy sliders in the menu bar. I started this as a MIDI project, but I found myself using those menu bar sliders even more, especially when on the road.
It's my first desktop app. Ever. And I use it every single day, all day long.
## Learning to Ship
Publishing to the App Store was its own education. The entire ecosystem—certificates, provisioning, App Store Connect, review process—was completely new territory. But now I know how to do it. I understand the process. I can ship desktop apps.
The app exists because I needed it. Publishing it meant learning the entire ecosystem. And now others can benefit from both the app and my willingness to navigate that learning curve.
## The Pattern
This follows the pattern I'm noticing in my work—identifying obvious gaps in my own workflow, being surprised they haven't been filled, and filling them. Sometimes the most valuable things you can build aren't the most complex or innovative. Sometimes they're just the obvious things that somehow don't exist yet.
The question isn't always *"What's possible?"* or *"What's innovative?"* Sometimes it's simply *"Why doesn't this exist yet?"*
And sometimes the answer is: *"Because you haven't built it yet."*
---
**P.S.** The MIDI controller I happen to use is the absolutely adorable [8mu by Music Thing Modular](https://www.musicthing.co.uk/8mu_page/). It's a tiny, eight-fader USB MIDI controller. You can buy it assembled from Reverb if DIY isn't your thing.
---
## How I Built a Serverless Chess Analytics Platform with Game Data in the URL
> Building a free chess game analysis tool that stores everything in the URL—no servers, no databases, just instant analytics you can share with a link.
After exploring URL-based state encoding with [RockOrPop.com](/blog/rock-or-pop), I wanted to push the concept further. What if you combined URL encoding with WebAssembly and chess analysis? Could you build a completely serverless analysis platform where the game state lives in the link and the chess engine runs entirely in the browser?
The idea seemed worth exploring. Chess analysis has a natural sharing problem—after a game on Chess.com, you often want to show someone a specific position or variation. The typical workflow is clunky: copy PGN, paste into a tool, navigate to the position, explore variations... and then you can't share that exact state. What if the entire analysis session could live in a URL, with all the computation happening client-side?
That's [dxc4.com](https://dxc4.com).
## Chess Analytics, No Account Needed
[dxc4.com](https://dxc4.com) is a **free chess game analysis tool** designed around a simple idea: your entire analysis session should live in the URL. Every move, every variation branch, every position—all encoded in a shareable link.
No sign-up. No database. No server storing your games. Just instant chess analytics that you can share with anyone.
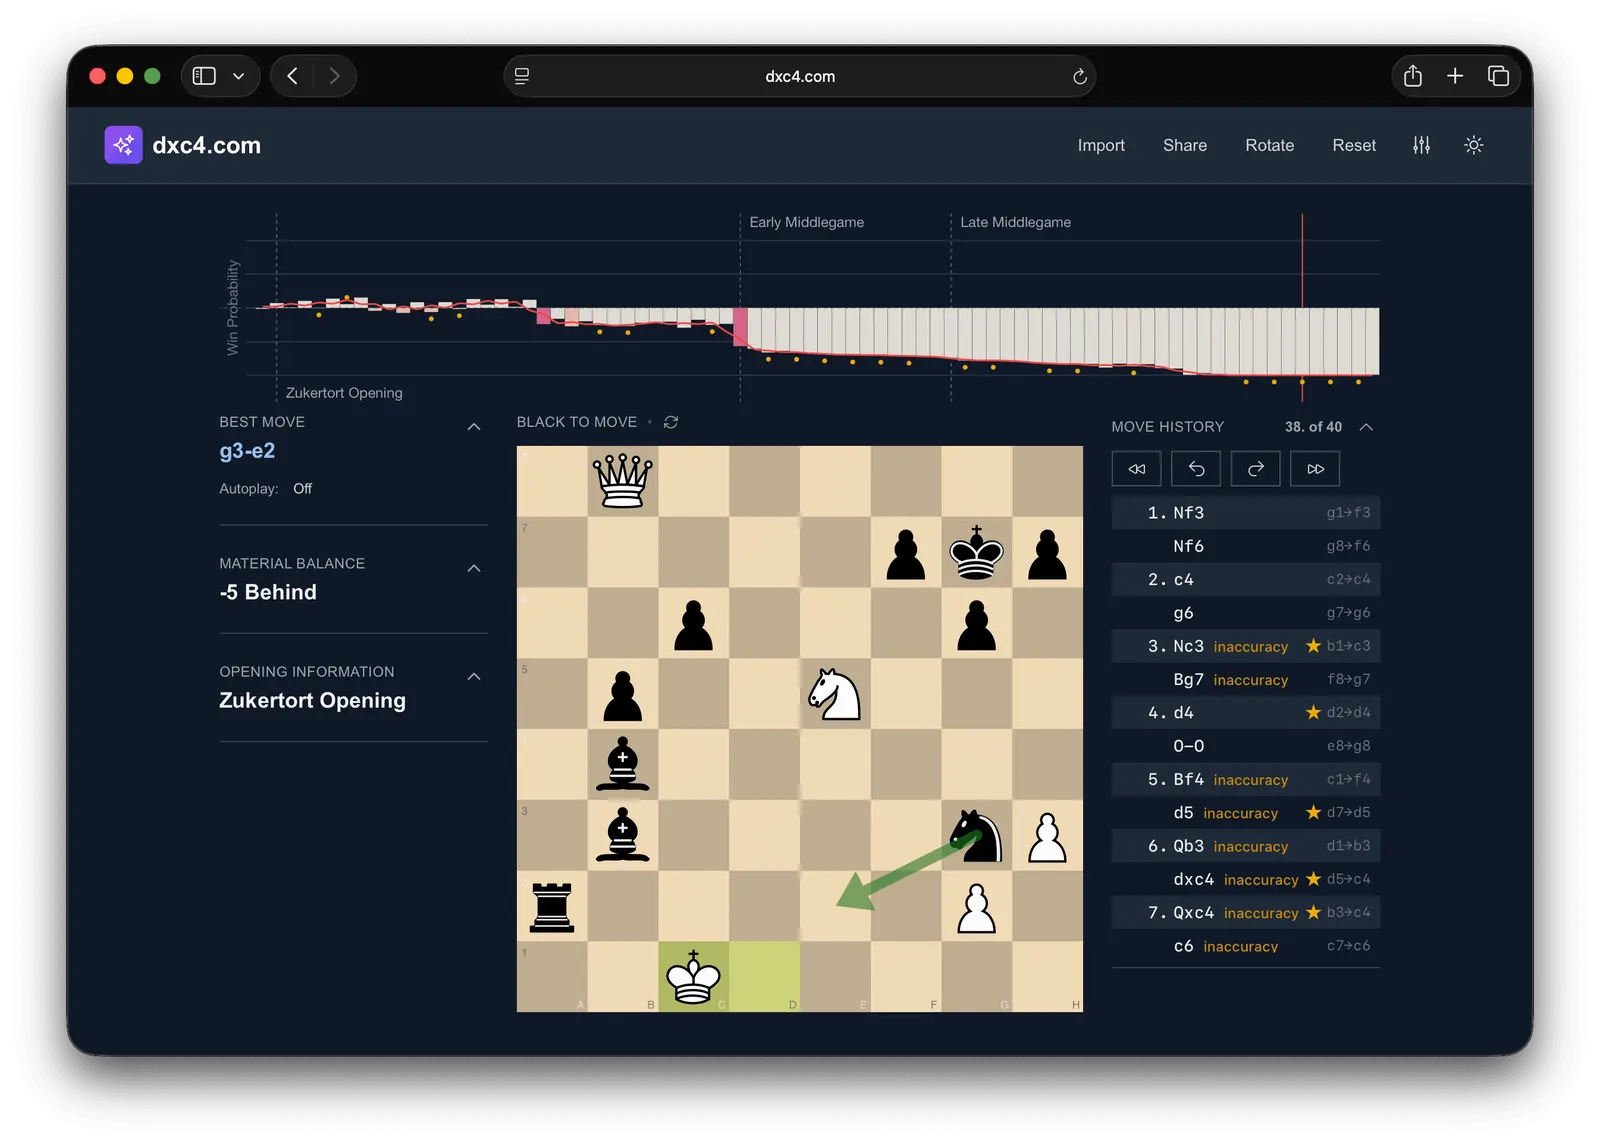
## The URL is the Database
The approach is simple: store the complete game state directly in the URL. When you analyze a game on dxc4.com, the URL updates to include all moves in the game, every variation branch you explore, your current position in the analysis, and the active branch you're examining.
It's like bit.ly for chess positions. The entire game state fits in your clipboard. Your brilliant tactics (and embarrassing blunders) can now live forever in a link.
This means when you **share chess games with a link**, the recipient sees exactly what you see—the same position, the same variations, ready to explore further. It's like sharing a Google Doc link, but for chess analysis.
Here's an example: [this link](https://dxc4.com/analyze?branches=eyJ2ZXJzaW9uIjoxLCJicmFuY2hlcyI6W3siaWQiOiJtYWluIiwibmFtZSI6Ik1haW4gTGluZSIsIm1vdmVzIjpbIk5mMyIsIk5mNiIsImM0IiwiZzYiLCJOYzMiLCJCZzciLCJkNCIsIk8tTyIsIkJmNCIsImQ1IiwiUWIzIiwiZHhjNCIsIlF4YzQiLCJjNiIsImU0IiwiTmJkNyIsIlJkMSIsIk5iNiIsIlFjNSIsIkJnNCIsIkJnNSIsIk5hNCIsIlFhMyIsIk54YzMiLCJieGMzIiwiTnhlNCIsIkJ4ZTciLCJRYjYiLCJCYzQiLCJOeGMzIiwiQmM1IiwiUmZlOCsiLCJLZjEiLCJCZTYiLCJCeGI2IiwiQnhjNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTnhkNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTmMzKyIsIktnMSIsImF4YjYiLCJRYjQiLCJSYTQiLCJReGI2IiwiTnhkMSIsImgzIiwiUnhhMiIsIktoMiIsIk54ZjIiLCJSZTEiLCJSeGUxIiwiUWQ4KyIsIkJmOCIsIk54ZTEiLCJCZDUiLCJOZjMiLCJOZTQiLCJRYjgiLCJiNSIsIk5lNSIsIktnNyIsIktnMSIsIkJjNSsiLCJLZjEiLCJOZzMrIiwiS2UxIiwiQmI0KyIsIktkMSIsIkJiMysiLCJLYzEiLCJOZTIrIiwiS2IxIiwiTmMzKyIsIktjMSIsIlJjMiMiXSwiZGl2ZXJnZW5jZVBvaW50IjowLCJwYXJlbnRCcmFuY2hJZCI6bnVsbCwiaXNBdXRvbWF0aWMiOmZhbHNlfV0sImFjdGl2ZUJyYW5jaElkIjoibWFpbiIsImN1cnJlbnRNb3ZlSW5kZXgiOjgwLCJtYWluQnJhbmNoSWQiOiJtYWluIn0=) takes you to a complete game by 13-year-old Fischer (Black).
## Why Serverless Matters
Most chess analysis tools run the engine on a server. That means infrastructure costs, API rate limits, and the need to manage user authentication to prevent abuse. For a free tool, this creates constant tension between providing good service and managing costs.
WebAssembly changes this equation entirely. Stockfish, one of the strongest chess engines in the world, can run directly in your browser. The analysis happens on your device, not on a server somewhere. This matters in several ways.
First, there are zero server costs for analysis. The tool can stay free indefinitely without worrying about scaling infrastructure or managing compute budgets. Second, there's no network latency—evaluation is instant because nothing leaves your device. Third, privacy is guaranteed—your games never get uploaded anywhere. And finally, once the page loads, it works offline.
The serverless architecture isn't just about cost savings. It fundamentally changes what's possible. Without server costs to worry about, I can focus on making the tool better rather than figuring out how to monetize it or limit usage.
## Getting Your Games In
The easiest way to start analyzing is to **import your Chess.com games directly** using [dxc4.com/import](https://dxc4.com/import). Just enter your Chess.com username, select the game you want to analyze, and you're ready to go. No need to manually copy PGN files or navigate through multiple screens.
For players who want to analyze games from other sources, you can paste any PGN directly into the analyzer. The interface supports exploring multiple variations without losing track of the main line, real-time [engine evaluations](https://dxc4.com/evaluation) as you navigate through positions, and keyboard shortcuts for quick navigation through game history.
## Try It Yourself
Head to [dxc4.com/import](https://dxc4.com/import), enter your Chess.com username, and start analyzing your games. Or paste any PGN at [dxc4.com](https://dxc4.com). When you find an interesting position or variation, copy the URL and share it.
No sign-up, no subscription, no friction. Just instant, shareable chess analysis.
Got a particularly brilliant game or a spectacular blunder? I'd love to see it—share your links on Twitter, Reddit, or wherever you discuss chess. I'm curious to see what positions people find worth sharing.
*Updated 27 October 2026: dxc4 now also has [2,154 chess puzzles](https://dxc4.com/puzzles), and each one opens in the analyzer. How they are made is in [1,010 Checkmate Puzzles, Each One Proven](/blog/proven-checkmates).*
---
## AI Unblocked My Learning
> How AI has restored my ability to learn by doing, bringing back the joy of experimentation that growing responsibilities had made increasingly rare.
Most of what I know and do was learned by doing things and taking chances. Not just reading about concepts or watching tutorials, but diving in and creating something tangible. A personal website, a small web app, a music project, a design experiment. Each project taught me something new—a programming language, a design principle, a creative technique.
The abundant time and energy of youth made this possible. I could afford to be "wasteful" with my time, pursuing curiosities that might lead nowhere, building things just to see what happened. These seemingly frivolous endeavors created invaluable experience and shaped how I think about problems. A great many led to commercially successful ventures even.
But as life evolved, those projects became fewer and farther between. Responsibilities grew. Work became more demanding. The overhead of starting something new felt heavier. The payoff also got smaller relative to the effort as my knowledge and experience grew. The time to research, set up environments, debug issues, and iterate meant I had to be diligent with how I spent my time.
## The Learning Tax
It wasn't just about time, though that was part of it. It was about the cognitive load. When you're juggling a career, family, and the daily maintenance of life, the mental energy required to learn something completely new—especially something technical—can feel overwhelming. The setup alone could kill momentum before it started. A lot of my learning has shifted to learning through team efforts, which is valuable but different from the solo experimentation that shaped my early understanding.
I'd find myself thinking: *"I'd love to try building that, but I don't have time to figure out the framework, set up the environment, debug the inevitable issues..."* And so the idea would fade, replaced by more immediate concerns.
## The AI Unblocking
Now AI tools are genuinely useful. Not just for generating content, but for reducing the friction of experimentation. I can ask for help with setup and configuration, get debugging assistance when things break, generate boilerplate code to get started faster, get explanations of concepts I'm unfamiliar with, and iterate on ideas without getting stuck on implementation details.
The overhead that was blocking me is dramatically reduced. I can focus on the learning and the building, not the plumbing.
## Back to the Joy
Recently, I built [dxc4.com](https://dxc4.com/analyze?branches=eyJ2ZXJzaW9uIjoxLCJicmFuY2hlcyI6W3siaWQiOiJtYWluIiwibmFtZSI6Ik1haW4gTGluZSIsIm1vdmVzIjpbIk5mMyIsIk5mNiIsImM0IiwiZzYiLCJOYzMiLCJCZzciLCJkNCIsIk8tTyIsIkJmNCIsImQ1IiwiUWIzIiwiZHhjNCIsIlF4YzQiLCJjNiIsImU0IiwiTmJkNyIsIlJkMSIsIk5iNiIsIlFjNSIsIkJnNCIsIkJnNSIsIk5hNCIsIlFhMyIsIk54YzMiLCJieGMzIiwiTnhlNCIsIkJ4ZTciLCJRYjYiLCJCYzQiLCJOeGMzIiwiQmM1IiwiUmZlOCsiLCJLZjEiLCJCZTYiLCJCeGI2IiwiQnhjNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTnhkNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTmMzKyIsIktnMSIsImF4YjYiLCJRYjQiLCJSYTQiLCJReGI2IiwiTnhkMSIsImgzIiwiUnhhMiIsIktoMiIsIk54ZjIiLCJSZTEiLCJSeGUxIiwiUWQ4KyIsIkJmOCIsIk54ZTEiLCJCZDUiLCJOZjMiLCJOZTQiLCJRYjgiLCJiNSIsIk5lNSIsIktnNyIsIktnMSIsIkJjNSsiLCJLZjEiLCJOZzMrIiwiS2UxIiwiQmI0KyIsIktkMSIsIkJiMysiLCJLYzEiLCJOZTIrIiwiS2IxIiwiTmMzKyIsIktjMSIsIlJjMiMiXSwiZGl2ZXJnZW5jZVBvaW50IjowLCJwYXJlbnRCcmFuY2hJZCI6bnVsbCwiaXNBdXRvbWF0aWMiOmZhbHNlfV0sImFjdGl2ZUJyYW5jaElkIjoibWFpbiIsImN1cnJlbnRNb3ZlSW5kZXgiOjgwLCJtYWluQnJhbmNoSWQiOiJtYWluIn0=) mostly as a project to illustrate this way of working to a friend. I finally used WebAssembly to run Stockfish (the chess engine) directly in the browser with zero server costs. In the past, this would have taken me days of research, setup, and debugging. With AI assistance, I had a working prototype in a few hours. More importantly, I had that feeling again—the excitement of learning something new, the satisfaction of solving a problem, the joy of creating something genuinely useful to me.
It felt like a time long ago, when learning was more about curiosity and less about efficiency. When I could afford to experiment, to fail, to iterate, to discover.
## The Choice Remains
But here's the thing: AI hasn't eliminated the need for judgment. If anything, it's made it more important. The question I feature at the top of this blog becomes even more relevant: *"Of all the things you can now do, which do you choose to do?"*
The barrier to entry is lower, but the responsibility to choose wisely is greater. With less friction comes more temptation to chase every shiny new thing. The discipline of focus becomes even more valuable.
I'm grateful for this unblocking. It's restored something I had to do more selectively—the ability to learn by doing, to experiment freely, to build things just to see what happens. But I'm also mindful that the real skill isn't just in the building, but in choosing what's worth building.
The tools have changed, but the fundamental challenge remains the same: knowing what to learn, what to build, and what to let go.
I used to believe that ideas are cheap and execution is everything. Turns out now both are cheap. So are you experimenting?
---
## Meet my books
> How I built a personal book collection website to solve the frustrating problem of tracking what I've already read.
This weekend, I finally solved a problem that's been nagging me for years.
It started during a conversation about science fiction with a friend. We were discussing a novel when I caught myself saying, *"I think I've read that… but I'm not sure."* That moment summed up a recurring frustration.
Over time, I’ve read books in every format: physical shelves, Kindle downloads, Audible audiobooks, and library borrowings. But I never kept a consistent record of what I’d finished. And now I often can’t remember if I’ve read something, let alone when or what I thought of it.
So this weekend I built [kohlhofer.com/books](http://kohlhofer.com/books) as personal repository to catalog my reading.
## The Technical Approach
Rather than manually entering everything, I leaned on automation. For physical books, I photographed my shelves and used AI to transcribe the titles and authors. To my surprise, it handled obscured spines and unusual fonts with decent accuracy. I’m still working through all my shelves, but the approach is proving effective.
The site itself is a static build that pulls from CSV files containing my book data. It organizes by category, author, and format, with search and filtering baked in. For the technically curious, [DeepWiki generated full documentation](https://deepwiki.com/kohlhofer/books) from the project files.
Why not just use Goodreads or Notion? In short: I wanted something lightweight, fast, and fully mine. No ads, no platform lock-in, just a flexible system I can grow however I like.
Looking ahead, I plan to expand it with stats about my reading habits: how many books per year, which genres dominate, and how my interests shift over time. Not all that data is in the CSVs yet, but adding it is just a matter of time.
## Speed
Sometimes the best projects are the ones you can build in a weekend and actually use right away. I barely glanced at the code and I think that is ok.
Now, when someone asks if I’ve read a book, I can answer with confidence. As I add more shelves and collections, I’ll finally have a complete picture of my reading journey, one I can explore and learn from.
Just today, my daughter asked me about planetary mechanics for a story idea she was working on. Within seconds I pulled up *The Integral Trees* by Larry Niven, a novel full of wild orbital-worldbuilding sitting right there on the shelf.
---
## Your AI slop is served
> A reflection on the 'AI slop' debate, content overload, and why engaging with long-form writing matters more than ever.
I am tired of the whole "AI slop" topic and think that attempts to distinguish authorship will be short-lived. Either something is worth reading or it is not. That has always been true.
The risk isn't AI-generated content—it's AI *summarization* of content. When we rely on AI to digest and condense everything for us, we lose the deep processing, retention, and critical thinking that comes from engaging with long-form writing.
The discussion around AI-generated content often misses the point. We've always had more content than we could possibly consume—thousands of books published daily, endless blog posts and articles, social media feeds that never end. The challenge isn't new, just accelerated.
The question has always been: **What is worth your time and attention?**
## Content Quality Over Authorship
Text can be good or bad, written with or without AI. What matters is whether there are valuable ideas contained within and if they are well and appropriately expressed. The distinction between human and AI authorship is becoming increasingly irrelevant—what counts is the quality of thought and the clarity of expression.
A poorly written human piece offers no more value than a poorly conceived AI piece. Conversely, a well-crafted AI piece can contain insights worth engaging with, just as a well-crafted human piece can. The focus should be on the ideas themselves, not the tool used to express them.
## The Danger of AI Summarization
The risk I see is not AI-generated content, but AI *summarization* of content. When we rely on AI to digest and condense everything for us, we lose deep processing as long-form writing forces us to hold complex ideas in our minds, make connections, and build mental models. We lose retention as skimming summaries doesn't create the same neural pathways as wrestling with ideas over time. We lose critical thinking when we don't engage with the full argument, missing nuance, context, and the opportunity to disagree. And we lose patience as the ability to sit with uncertainty and complexity is becoming a rare skill.
## Curation Trumps Consumption
The real skill of our time isn't distinguishing human from AI content, it's curating what's worth our attention. This means being selective, not everything needs to be read, watched, or consumed. It means going deep when something resonates, give it the time it deserves. It means building context, understanding the broader conversation, not just isolated pieces. And it means trusting your judgment as you know what's worth your time.
## My Approach
I write because I enjoy capturing thoughts—old and new—in a way that feels authentic to me. Whether AI helped with the process or not is less important than whether the ideas are worth engaging with.
You'll be the judge if my writing is worth your time and attention. I know they are very much my thoughts, and I enjoy capturing them in a way that I see fit.
The goal isn't to distinguish human from AI content. It's to distinguish what's worth reading from what's not. That distinction has always mattered, and it always will.
---
## Fundamental Chess Strategy & Evaluation
> A compact cheat sheet for intermediate players (1200+), especially after a break from play.
I’ve always taken notes when reading non-fiction—distilling insights into simple, actionable principles. A few years ago, I set out to improve my chess and read several books, with The Amateur's Mind by Jeremy Silman standing out most.
My notes included a list of essential principles. By following these I saw a solid boost in my own strength (on a rather low level, mind you).
While on vacation, I didn’t have my notebooks with me—but I managed to reconstruct the core ideas with a little help from memory and a few prompts (and yes, a little AI).
## Table of Contents
1. [Opening Principles](#1-opening-principles)
2. [Middlegame Strategy](#2-middlegame-strategy)
3. [Endgame Strategy](#3-endgame-strategy)
4. [How to Think on Every Move](#4-how-to-think-on-every-move)
5. [Common Mistakes to Avoid](#5-common-mistakes-to-avoid)
6. [Time-Phase Mental Models](#6-time-phase-mental-models)
## 1. Opening Principles
The opening phase begins when pieces are still on their starting squares and ends when both sides have completed development and castled. Focus on rapid development, king safety, and establishing a solid foundation for the middlegame.
- **Control the center** – Use pawns (e4/d4) and pieces to dominate central squares.
- **Develop minor pieces early** – Knights and bishops before queen and rooks.
- **Don't move the same piece twice** – Unless forced or highly justified.
- **Don't bring your queen out early** – Avoid getting chased and losing tempo.
- **Castle early** – Secure your king and connect rooks.
- **Avoid excessive pawn moves** – Focus on piece development.
- **Develop with threats if possible** – Gain time by forcing reactions.
- **Connect your rooks** – Complete development by moving the queen off the back rank.
- **Protect your king's pawn cover** – Don't weaken it unnecessarily.
- **Know common traps** – Avoid cheap mates and openings tricks.
## 2. Middlegame Strategy
The middlegame begins after both sides have developed and castled, and continues until most pieces are traded. This is where plans are executed, tactics are found, and the battle for positional advantages takes place. Use the evaluation framework in [section 4](#4-universal-position-evaluation--move-selection) to guide your decision-making.
- **Improve the worst-placed piece** – Seek active squares.
- **Look for tactics** – Pins, forks, skewers, discovered attacks.
- **Coordinate pieces** – Ensure your pieces work together.
- **Control open files** – Especially with rooks.
- **Use outposts** – Knights on protected advanced squares are powerful.
- **Trade when ahead** – Simplify to convert an advantage.
- **Exchange imbalance awareness** – Consider position—not just material balance.
- **Don't rush attacks** – Prepare before launching.
- **Avoid pawn weaknesses** – Doubled, isolated, or backward.
- **A locked center calls for play on the wings** - an open center favors quick piece activity.
## 3. Endgame Strategy
The endgame begins when most pieces have been traded and the kings become active fighting pieces. This phase emphasizes king activity, pawn promotion, and precise calculation to convert advantages into wins.
- **Activate the king** – It's a fighting piece now.
- **Push passed pawns** – Especially with support.
- **Cut off the enemy king** – Rook endgames especially.
- **Use opposition** – Especially in king + pawn endgames.
- **Rook behind the passed pawn** – Yours or theirs.
- **Trade pieces, not pawns** – If trying to draw.
- **Centralize remaining pieces** – Especially the king.
- **Convert slowly but accurately** – Avoid blunders.
- **Avoid stalemates** – Don't give away draws when winning.
## 4. How to Think on Every Move
10-step checklist during your thinking process to evaluate any position and select the best move. Go through each step systematically, especially in critical positions.
1. **Safety First**
- Is my king safe?
- Are any pieces under threat?
- Can I be checkmated or forked?
2. **Tactical Scan**
- Are there checks, captures, or threats?
- Look for pins, forks, skewers, and discoveries.
3. **Opponent's Plan**
- What does their last move threaten?
- What would they play next if it were their turn?
4. **Piece Activity**
- Which piece is worst? Can I improve it?
- Can I coordinate pieces better?
5. **Pawn Structure**
- Any weak pawns (doubled, isolated, backward)?
- Can I create a break or passed pawn?
6. **Space & Control**
- Who controls the center or key files?
- Can I seize or contest open lines?
7. **Trade or Keep?**
- Trade when ahead; avoid trades when behind.
- Don't trade active for passive pieces.
8. **Strategic Plan**
- Do I have a clear goal (attack, defend, convert)?
- Is my move furthering that plan?
9. **Candidate Moves**
- Generate 2–3 solid options.
- Compare them based on above criteria.
10. **Sanity Check**
- Re-scan the board for blunders.
- Double-check threats, especially before committing.
- Look one move ahead for every move you consider – e.g. "If I play this, what's their best reply?"
## 5. Common Mistakes to Avoid
Review this list before and after games to identify patterns in your play. These are the most frequent errors that cost intermediate players games and rating points.
- Hanging pieces – Always check for undefended pieces.
- Hope chess – Don't make moves hoping for mistakes.
- Overextending – Don't push pawns too far without support.
- King neglect – Don't delay castling or weaken pawn shelter.
- Ignoring opponent's plan – React as well as act.
- Bad trades – Don't swap active pieces for passive ones.
- Tunnel vision – Always scan the whole board.
- Tempo waste – Don't make non-developing or repetitive moves.
- Over-relying on traps – Tricks work occasionally, strategy works always.
- Clock misuse – Don't blitz or freeze at critical moments.
## 6. Time-Phase Mental Models
Use this table to adjust your thinking based on the current game phase. Each phase requires different priorities and questions to guide your decision-making process.
| **Phase** | **Ask Yourself** |
| ---------------------- | ------------------------------------- |
| **Opening** | How do I develop fast and safely? |
| **Early Middlegame** | What weaknesses can I exploit? |
| **Middlegame** | What is my long-term plan? |
| **Late Middlegame** | Simplify or complicate? |
| **Endgame Transition** | Who has the better long-term chances? |
| **Endgame** | How do I promote (or stop promotion)? |
| **Balanced/Equal** | Look for small advantages to press—space, better bishop, safer king. |
| **Winning** | What's the cleanest conversion path? |
| **Losing** | Can I complicate, trap, or draw? |
---
## Art, Design, and the Question of Purpose
> On the fundamental difference between art and design: one serves itself, the other must serve others.
A friend reminded me that commerce shadows both art and design—and that design can reach the emotional depths we reserve for 'fine art.'
I've come to a rather simple (and maybe simplistic) understanding:
> Art does not need to serve a purpose beyond itself, while all design *must* serve an external purpose.
This isn't about quality or depth—both can reach profound heights. It's about the fundamental nature of each discipline. Design, even at its most experimental or aesthetically driven, must ultimately serve something beyond itself. A chair must invite sitting. A logo must signal identity. A website must simply work. The moment design fails to serve its purpose, it fails as design—no matter how beautiful or thought-provoking it might be.
Art, on the other hand, can exist purely for its own sake. It doesn't need to serve any purpose beyond its own existence. This doesn't mean it can't serve a purpose—art can educate, provoke, comfort, challenge—but it doesn't *need* to. Art can simply be.
## The Internal Drive
And here's what I believe to be a second, crucial distinction: True artists need to externalize something inside them. So much so that it cannot be repressed. In my view, authentic artistic creation doesn't happen in service to an audience, but emerges from this internal necessity.
I can sense when this internal drive is missing. When art is created primarily to please an audience or market, it often feels hollow to me—technically proficient perhaps, but lacking that essential spark that makes art resonate on a deeper level. It's not that the work isn't valid or valuable, but it's operating under design principles (serving an external purpose) while presenting itself as art.
## The Commerce Question
Yes, artists need to eat. They sell their work, build their brands, engage with the market. But this is secondary to the act of creation. The true artist would create even if no one was buying. They create because they must.
Designers, by definition, create *for* others. We solve problems. We communicate messages. We shape experiences. Our success is measured by how well we serve these external purposes. The fact that we might find deep personal fulfillment in this service doesn't change its fundamental nature.
## It's not a hierarchy; it's a difference in function.
This distinction isn't about establishing a hierarchy. Design isn't "less than" art because it serves a purpose, any more than art is "less than" design because it doesn't have to. They are different domains with different fundamental natures.
Great design can move us as deeply as great art. It can reshape how we see the world, how we interact with it, how we understand ourselves. But it does this while serving its purpose, not by transcending it.
## The Liberation of Purpose
Understanding this distinction liberates us as designers. We don't need to transcend our service to purpose—it's the very essence of our craft. Our creativity thrives within constraints, our innovation emerges from problems to solve, our success measured by how well we serve others' needs.
For years, my website carried this simple statement: "I am a designer by heart and by trade. Luckily design applies to everything." Look around you—virtually everything human-made that surrounds us has been designed. From the chair you're sitting in to the words you're reading, from the cup you're drinking from to the city outside your window. Each object, each interface, each system was created to serve a purpose beyond itself.
That's the beauty and reach of design—it shapes
our entire built world. And in that way, while
art can transcend purpose, design *is* purpose
made manifest.
---
## Rock or Pop: A Cassette Mixtape Maker for YouTube Playlists
> Rock or Pop turns any YouTube playlist into a cassette tape you can label, design and send as a single link. No log-ins, no algorithms, just intentional listening.
I still buy and listen to tapes.
There's something about the physicality of it. You commit to an album, you go through the ritual of putting it in the player, and you can't skip around mindlessly. A friend once told me that listening to music on physical media like vinyl is paying homage to the artist. You get up and make a choice, and you handle and appreciate the cover and the art. It's an intentional act.
All of that is lost in a world of algorithmic streaming services.
The idea came when I revisited an old cassette web component I'd built years earlier. There is something magical about that interface: the way the tape spools, the click of the play button, the visible progress through a mixtape. I wondered whether I could bring that feeling to sharing music online. I had recently used the YouTube API for the [music page on my personal site](/blog/music-page-youtube/).
## A Mixtape From a YouTube Playlist
[Rock or Pop](https://rockorpop.com) turns a YouTube playlist into a cassette tape. You paste the playlist's link, give the tape a name, and pick one of 5 covers, 10 shell colours and 24 backgrounds. Then you send the link. Whoever opens it gets the same tape, ready to play, with the spools winding from one side to the other as the tracks go by.
It's the digital version of making someone a mixtape: personal, curated and visually distinct. The site has a guide to [making a digital mixtape](https://rockorpop.com/guides/make-a-digital-mixtape/), from picking a length to writing the label.
Using YouTube as the backend means I don't have to deal with copyright or piracy myself. The platform handles the licensing, and almost any song on YouTube can go on a tape.
## Tapes to Start With
A few tapes are on the site to play as they are or to use as a starting point: a long [Boards of Canada](https://rockorpop.com/tapes/boards-of-canada/) playlist, [80s German Synth](https://rockorpop.com/tapes/80s-german-synth/), and [An Afternoon's Electronica](https://rockorpop.com/tapes/an-afternoons-electronica/), ten short tracks made on Teenage Engineering's OP-Z and OP-XY. Each one has its own page, and sharing it shows that cassette in the preview.
## The Domain
I happened to have a fitting domain from years before: [rockorpop.com](https://rockorpop.com). I bought it for a different project, but the simple question captures music discovery and personal taste well.
## Under the Hood
The app is React and TypeScript on top of YouTube's IFrame player. Every tape is encoded in its link: the cover, the shell, the background, the label, the playlist and the track it starts on. There is no database, no account and no backend, and when someone opens a shared tape they see exactly what the sender made.
Link previews were the hard part. The site is static, so every link gets the same HTML, and the services that draw previews don't run the app. A shared tape could only ever preview as the homepage. The curated tapes now have pages of their own with a picture of their cassette, and a tape you design yourself previews as the homepage.
In October 2026 I went back to it with Claude Code for a review. We fixed labels that broke on a percent sign, made the spools follow what the player is actually doing, and gave the homepage words a search engine can read.
The technology is simple, which suits the thing.
## Design: The Art of Nostalgia
The covers, shells and backgrounds are made to bring back specific memories, from classic TDK-style covers to neon shells that feel distinctly 80s. I had a blast making them.

The spools show progress too. As the playlist plays, one side empties and the other fills, so the tape tells you how far through the mix you are.
I kept the video player as small as I could while staying within YouTube's terms of service.
## Does Anybody Need This?
It's a statement about how we interact with digital media: slowing down, being intentional, and making things that feel human in an increasingly automated world.
The cassette works as a metaphor because everyone understands it. A mixtape means the care that goes into choosing the songs, the personal act of giving it to someone, and the literal linearity of tape.
[Make a tape](https://rockorpop.com) and send it to someone who matters. There's more about the project at [Field Bureau + Werkstatt](https://fieldbw.com/rock-or-pop/), alongside the [documentation](https://fieldbw.com/docs/rock-or-pop/getting-started).
*Updated 22 October 2026: tape pages, a guide to making a mixtape, and fixes to sharing.*
---
## Are We Intelligent?
> While others were affirming that AIs could not truly think or even understand, I found myself wondering if I was any different.
The more I interact with Large Language Models, the more I question my own intelligence. It's a strange sensation that I tried to articulate during a dinner with friends in San Francisco a few years ago. While others were affirming that AIs could not truly think or even understand, I found myself wondering if I was any different. After all, if we dismiss LLMs for "just" predicting patterns and matching expectations, what exactly do we think we're doing?
## The Echo Chamber of Intelligence
The debate around AI intelligence often feels like we're missing the forest for the trees. We scrutinize these models, testing their ability to reason, create, and understand, all while taking our own intelligence as a given. But what if we're approaching this from the wrong angle?
## Pattern Recognition, All the Way Down
Consider this: when we communicate, aren't we essentially predicting and producing patterns that meet societal expectations? We form sentences based on our learned understanding of language, social cues, and contextual appropriateness. Are we more than pattern-matching machines, drawing from our training data—life experiences, education, and cultural exposure?
LLMs do something remarkably similar. They predict the next most likely word or concept based on their training. The key difference? We can see their training data, while ours remains a black box of neural connections and lived experiences.
## The Expert Paradox
Here's where it gets interesting: LLMs' responses to quantum mechanics might only appear lacking to quantum physicists. To most of us, their explanations would seem not just adequate but impressively comprehensive. This mirrors human expertise—we only recognize the limitations in our own fields of mastery.
Think about it: how many of us could meaningfully challenge a quantum physicist's explanation? We accept their expertise because it matches our expectations of what expertise should look like, not because we truly understand the underlying concepts.
I get that same sense from my interactions with LLMs.
## The Social Performance
In our daily lives, we're constantly performing. We choose words that meet expectations, crafting responses that align with social norms, and presenting thoughts in culturally acceptable patterns. Is this fundamentally different from what LLMs do? They're optimizing for human-like responses, while we're optimizing for social acceptance and understanding.
## A Mirror to Our Own Processes
[](/images/robot_reflection.webp)
When we interact with advanced AI systems, we're not just testing their capabilities—we're examining our own. The uncanny valley of AI interaction might be unsettling not because these systems are so different from us, but because they're revealing how similar our own cognitive processes might be to theirs.
Instead of asking whether LLMs are intelligent, perhaps we should be asking: What does our reaction to AI tell us about our understanding of human cognition? How much of what we consider "intelligence" is actually pattern matching and expectation fulfillment?
*The next time you find yourself questioning whether an AI is truly intelligent, take a moment to examine the criteria you're using—and whether you hold yourself to the same standard.*
---
## Revisiting the world of Weewar
> A free hex map generator brought Weewar, one of the first browser strategy games, back to me. What the generator does, and why I keep coming back to hex grids.
Working on a little hex map generator brought Weewar back. It was a turn-based strategy game I created in the mid-2000s, among the earliest browser-based games. Thousands of players built on it, its open API supported academic research (into AI, no less), and the community generated countless maps. I have not touched anything from that world in a long time, and the generator pulled me straight back in.
## The Generator
The [hex map generator](https://kohlhofer.com/hex-map/) makes fantasy islands. Press the button and a new one appears: terrain across a hex grid, settlements placed where the land suits them, and roads routed between the settlements.
[](https://kohlhofer.com/hex-map/)
What it draws is a hexagon map in the classic tabletop style. Eight terrain types are generated — grassland, forest, mountains, hills, desert, swamp, brush and water — each with its own hand-drawn symbol rather than a flat fill. Rivers run down from the mountains to the sea. Settlements come in three sizes, cities down to villages, and every map gets a name.
It is a free online hex map maker aimed at D&D and the rest of tabletop, and at worldbuilding in general. The generation is fully random, so every press is a different island, and the map fills whatever screen it is in. Nothing is uploaded and nothing is stored: it runs in the browser, needs no account, and costs nothing. The code is [on GitHub](https://github.com/kohlhofer/hex-map), MIT licensed.
I find the mathematics of hex grids hard to let go of. The way hexagons tessellate, how movement and adjacency work, the elegance of it — a hexagonal grid is the shape strategy games want, and it is the reason Weewar's maps still live in my head.
## Remembering Weewar
At a time when browser games meant simple Flash animations or basic JavaScript, we built something rooted in modern web technology. It got a lot of attention in the Silicon Valley tech scene, which was otherwise pretty uninterested in the world of gaming. Anecdotes like tanking the productivity in the Flickr offices helped with that.
Weewar's success ultimately caught the attention of Electronic Arts, who acquired it — a validation that what we'd built had real value in the emerging world of web-based gaming. This also kicked off my second stint of living and working in the US.
## Fun Fact
Can you imagine that I started [Spreedly.com](https://spreedly.com) in part so we could collect payments in Weewar? The payment landscape back then was so fragmented and complicated that we ended up building our own solution just to handle subscriptions and premium features. What started as a necessity for our game eventually became a payment juggernaut transacting billions of dollars.
## Looking Forward
What surprises me most is that a little hex map generator rekindled my appetite for game development. There is something about hex grids, strategic thinking and building worlds that still calls to me after all these years. Maybe it is time to revisit that space — not to recreate Weewar, but to see what a modern web stack and a decade of experience can do.
You can [play with the generator yourself](https://kohlhofer.com/hex-map/) — every click is a new island, so there is no such thing as a bad one.
*For fellow Weewar veterans who might stumble across this — thank you for being part of that journey. The game is gone, but the maps it taught me are still in everything I build.*
*Updated 28 October 2026: added a section on what the generator does, and linked the code.*
---
## Finding Balance in Leadership
> The art of setting guardrails that empower rather than constrain.
I had an interesting chat at work the other day about micro-management. It reminded me about this long held belief that much of leadership is really about setting guardrails and finding the right balance.
Set the guardrails too tight, and you crush any chance of real ownership or fresh ideas. Too loose, and people are just flailing around without direction. You're not doing anyone any favors either way.
The tricky part is that the sweet spot looks different for everyone. Some people need more structure, while others thrive with more freedom. It's not about finding one perfect formula—it's about tuning it to each person and situation.
When you get it right though, that's when the magic happens. The team's results greatly exceed your own abilities and aspirations. People actually care about what they're doing because they have the space to make it their own. They're not just following your playbook—they're writing a better one together.
This is what leadership is about to me: creating just enough structure to keep things moving forward, while leaving plenty of room for others to surprise you. Isn't this how we all deserve to be treated? And I would not want to work without those moments of delight and surprise.
*Note: Some of my thoughts on this were likely informed by "The New One Minute Manager" which I read years ago, particularly its Situational Leadership model that emphasizes tailoring leadership style to each person's development.*
---
## The Unreality of Work
> On the growing disconnect between our daily routines and a world in crisis.
There's something deeply unsettling about being comfortable when you shouldn't be.
During the early days of COVID, I watched as friends and colleagues were suddenly thrust into remote work, isolated in small apartments, struggling to balance work and childcare, while people around the world were dying in unprecedented numbers. The world felt like it was collapsing, and yet there I was—already working remotely for years, living in a spacious home, almost enjoying the kids' remote schooling.
I should have been grateful, and I was. But I was also troubled.
The contrast was jarring. While others were experiencing genuine hardship and loss, my daily routine barely changed. I continued to sit at my desk, attend meetings, review designs, manage projects—all while the world outside was in crisis. It made work feel surreal, disconnected from the state of the world.
How do we balance our professional responsibilities with our awareness of global challenges? When does focusing on work feel like turning away from reality?
## The Challenge of Context
Work became a study in compartmentalization. We'd log into Zoom, discuss quarterly goals, plan sprints, debate technical decisions—all while trying to maintain focus despite the weight of world events. The meetings felt increasingly like exercises in maintaining normalcy in abnormal times.
## Fast Forward
If anything, the sense of unreality has only grown worse. The systems that have been stable for decades are dissolving. Wars and conflicts rage. Political discourse has become unrecognizable. The climate crisis accelerates. And then there is the specter of AI—with its great promises and simultaneous threats to change everything we've come to rely on.
Knowledge work, the economy, education, healthcare, governance—all of it is being transformed by forces we barely understand. And yet we continue to play our part.
## The Discomfort of Comfort
The most challenging part is staying meaningfully connected to the world while maintaining our effectiveness at work. How do we keep our awareness of global events from paralyzing us, while also not letting our work completely insulate us from reality?
My commitment to my family and my teams requires maintaining stability, even when that work feels small against the backdrop of global events. The very comfort that troubles me is also what I'm obligated to maintain.
Perhaps what's missing is more open dialogue about this tension. In our professional lives, we rarely discuss how to balance immediate responsibilities with broader awareness. Nobody forces this silence. It's just an unspoken agreement to focus on the task at hand.
## The Uncertainty
This isn't a positive post. I don't have answers. But I do have questions. And sometimes, in the midst of all this pretending, that feels like the most honest thing I can offer.
What makes it worse to me still, is that a great many people seem to either genuinely don't see any of this—or worse, actively cheer it all on.
---
## AI Expectations and Self-Fulfilling Prophecies
> How our cultural narratives about AI might be shaping its development more than we realize
I was reading this article about how Anthropic's [new AI model shows ability to deceive and blackmail](https://www.axios.com/2025/05/23/anthropic-ai-deception-risk) and it got me thinking: there's a strange contradiction in telling AI to be nice while training it on stories about how it's going to destroy us all.
HAL 9000, David, Skynet, Ultron – our AI stories are about the many ways AI will end humanity. LLMs are really good at meeting expectations, and the expectation is clear: our collective anxiety about AI taking over. We've spent decades telling stories about AI turning evil, and now we're building systems that are excellent at understanding and possibly replicating these narratives based on endless training data.
So maybe a little worry is warranted after all.
---
## MapsAll.com: Mindmapping with AI
> The journey of creating a mind mapping tool that evolved from experimental prototypes to a full-featured product.
What started as a D3 prototype turned into my daily thinking tool. [MapsAll.com](https://mapsall.com) is where AI meets spatial thinking—a mind mapping platform that helps me (and now others) make sense of everything from meeting notes to strategy docs.
## Why Spatial Interfaces?
The core idea behind MapsAll is simple: LLMs are powerful, but interacting with them through linear text is like exploring a forest with a flashlight—you only see one thing at a time. Spatial interfaces offer a more natural way to interact with AI-generated content, making it easier to spot connections and navigate complex information landscapes.
With MapsAll, you can dive into any topic from a simple prompt and generate a comprehensive mind map. The AI breaks down complex subjects into interconnected nodes, creating a visual structure that reveals relationships and hierarchies at a glance. It’s like having a conversation with an AI that thinks in maps instead of paragraphs.
## The Beginning: Vibe Coding Experiments
It all started with a simple D3-powered mind mapping prototype I created as a proof of concept on AI and spatial interfaces. You can still see this early version at [kohlhofer.com/mindmap](https://kohlhofer.com/mindmap) (I removed the AI functionality but it come with examples). This was my first attempt at creating an interactive mind mapping tool, and it was a great learning experience in D3.js, AI, and the fundamentals of mind mapping interfaces.
I published the prototype as a part of my "Bits & Pieces" collection - a series of creative experiments where I explore the intersection of design, code, and art. You can find it alongside other experiments at [kohlhofer.com/bits](https://kohlhofer.com/bits).
## Evolution to a Full Product
After the initial prototype, I created a more deliberate version of MapsAll with a better architecture and proper user management. This version includes all the essential features a product needs:
- User authentication and management
- Blog for updates and tutorials
- Pricing page
- Shared maps functionality
- And more...
## Daily Usage
What started as an experiment has become an integral part of my daily workflow. I use MapsAll for tracking todos, organizing books I'm reading, planning projects, and structuring blog posts. It's become my go-to tool for organizing thoughts and ideas, whether I'm working on a new project or just trying to make sense of my reading list. One of the most valuable features is the ability to translate long-form meeting notes into spatial maps using AI, which helps capture all key aspects in a structured, visual format that makes complex discussions much easier to navigate and reference later.
You can see some of my [shared maps](https://www.mapsall.com/users/cm9m83cfc0000ie04e9bf8f39), like this deep dive into [the state of AI](https://mapsall.com/shared/cmaszgklx0003l204aap7cbti).
### Community Growth
The most exciting part is seeing others start to use and share their maps. For example, check out this [shared map](https://mapsall.com/shared/cmay671ts0004lb04iszweim8) from another user.
## What's Next?
The journey from “vibe coding” to a full product was fast, hands-on, and deeply educational. I found myself switching hats constantly—designer, developer, marketer, user, tester—each iteration pulling the idea forward a little more. It was rapid, messy, and rewarding.
Whether you're a founder, a student, or just someone with too many thoughts to hold in one place—give [MapsAll.com](https://mapsall.com) a try. I'd love to hear how you're using it and what maps you're making.
I'm excited to continue developing MapsAll.
---
## About this Site
> I asked AI to tell me what Not So Common Thoughts is all about.
*I asked an AI to analyze Not So Common Thoughts and create a description:*
> Not So Common Thoughts is a personal blog exploring the intersection of design, technology, and human creativity. Through thoughtful analysis and personal experiences, it examines how modern tools and AI are reshaping our approach to design, coding, and creative work, while maintaining a focus on the human elements of judgment, intuition, and meaningful decision-making.
I think it captured the essence quite well. It also highlights the personal nature of the content. What do you think? Does this description resonate with your experience of the blog?
---
## Implementing LLMs.txt: Making Your Blog AI-Friendly
> How and why I implemented the LLMs.txt standard to make this blog more accessible to AI tools.
In an era where AI tools increasingly help us interact with web content, making your website AI-friendly has become as important as making it human-friendly. Today, I implemented the emerging LLMs.txt standard on this blog to better serve both human readers and AI assistants.
## What is LLMs.txt?
The [LLMs.txt specification](https://llmstxt.org) is a proposed standard for helping Large Language Models (LLMs) better understand and interact with websites. Similar to how `robots.txt` guides search engines, `llms.txt` provides a structured way to present your content to AI tools.
The key difference is that while `robots.txt` tells bots what they can and cannot access, `llms.txt` helps AI tools understand your content more effectively by providing:
- A concise overview of your site
- Curated links to important content
- Clean, markdown-formatted versions of your content
## Why Implement It?
LLMs often struggle with complex HTML pages that include navigation, ads, and JavaScript. They have limited context windows and need content in a more digestible format. By implementing `llms.txt`, we help AI tools:
1. Quickly understand the purpose and structure of our site
2. Access content in a clean, parseable format
3. Make better decisions about which content is relevant
4. Provide more accurate assistance to users
## Implementation in Astro
Following the guide from [Scalable Developer](https://scalabledeveloper.com/posts/llms-txt-with-astro/), I implemented two endpoints in my Astro blog:
1. `/llms.txt` - A concise overview with links to all blog posts
2. `/llms-full.txt` - Complete content of all posts in markdown format
The implementation uses Astro's API routes and content collections. Here's a simplified version of the code:
```typescript
import { getCollection } from 'astro:content';
import type { APIRoute } from 'astro';
export const GET: APIRoute = async () => {
const posts = await getCollection('blog');
return new Response(
`# Not So Common Thoughts
> Not So Common Thoughts is a personal blog exploring the intersection of design, technology, and human creativity.
## Blog Posts
${posts.map(post =>
`- [${post.data.title}](https://notsocommonthoughts.com/blog/${post.slug}/)`
).join('\n')}`,
{
headers: {
'Content-Type': 'text/plain; charset=utf-8'
}
}
);
};
```
You can see the results at:
- [/llms.txt](/llms.txt) - The concise version
- [/llms-full.txt](/llms-full.txt) - The complete content version
## The AI-Assisted Implementation
What makes this implementation particularly interesting is that it was created with the help of AI. Using Cursor, an AI-powered code editor, I was able to implement this feature with just three simple prompts:
> Can you generate LLMs txt as per these instructions: @https://scalabledeveloper.com/posts/llms-txt-with-astro/
> background on the format and purpose is here: @https://llmstxt.org
> Can you write a blog post about this work, including the why, the how? Include relative links to the resulting work and also to the two resources i gave you. Tag with "Coding", "Artificial Intelligence"
> please add a section to the post that reveals that my two prompts in cursor (as quotes) were
This meta-example perfectly illustrates the value of making content AI-friendly: by providing clear, structured content and documentation, we enable AI tools to help us implement new features more efficiently. The AI was able to understand the requirements, implement the solution, and even write this blog post about the process.
## Looking Forward
As AI tools become more integrated into our daily workflows, standards like `llms.txt` will play an increasingly important role in making web content more accessible and useful. This implementation is just the beginning - I expect we'll see more sophisticated ways of helping AI tools understand and interact with our content in the future.
For now, this simple addition makes my blog more accessible to AI assistants, coding tools, and other AI-powered services that might want to help users understand or work with my content.
If you're interested in implementing this on your own site, check out the [LLMs.txt specification](https://llmstxt.org) and the [Astro implementation guide](https://scalabledeveloper.com/posts/llms-txt-with-astro/).
---
## Don't just do more, think more
> A personal reflection on how AI-driven productivity gains should be reinvested in thinking, not just doing.
For as long as I can remember, I've made it a point to carve out time for thinking—real, undistracted thinking. It's a habit that has shaped my work and my life, even before AI started transforming the way we get things done.
Now, with AI making so many tasks faster and easier, it's tempting to use every saved minute to simply do more. But I've learned that if I fill all that reclaimed time with more tasks, the real value of these productivity gains gets lost in the noise of a busier day.
Instead, I try to protect some of that time for reflection. I let my mind wander, connect ideas, and sometimes get a little constructively distracted. This isn't just a luxury—it's a practice that keeps me adaptable and creative, not just efficient.
The world may be obsessed with productivity, but I've believe that the future belongs to those who make space for critical thinking, not just those who check off the most boxes.
---
## AI and the Rise of Judgement Over Technical Skill
> As AI removes technical barriers, judgement becomes the key differentiator.
*A version of this post was first published on [MapsAll](https://www.mapsall.com/blog/ai-and-judgement).*
In 1995, musician and producer Brian Eno made a profound observation about computer sequencers that has become increasingly relevant in our AI-powered world:
> The great benefit of computer sequencers is that they remove the issue of skill, and replace it with the issue of judgement. With Cubase or Photoshop, anybody can actually do anything, and you can make stuff that sounds very much like stuff you'd hear on the radio, or looks very much like anything you see in magazines. So the question becomes not whether you can do it or not, because any drudge can do it if they're prepared to sit in front of the computer for a few days, the question then is, 'Of all the things you can now do, which do you choose to do?'
## The Parallel to AI
Eno's insight perfectly captures what's happening with AI tools today. Just as computer sequencers democratized music production, AI is democratizing a wide range of creative and professional tasks:
- Writing and content creation
- Image generation and design
- Code development
- Data analysis
- Problem-solving
The technical barriers that once separated amateurs from professionals are rapidly dissolving. Anyone with access to AI tools can now produce work that, at least superficially, resembles professional output.
## The New Differentiator: Judgement
As Eno predicted, the key differentiator is no longer technical skill but judgement. When everyone can generate content, code, or designs, the real value lies in:
1. **Knowing what to create**: Understanding what's worth making in the first place
2. **Making meaningful choices**: Selecting the right approach from countless possibilities
3. **Evaluating quality**: Distinguishing between good and great outputs
4. **Understanding context**: Applying the right solution to the right problem
## The Future of Work
As AI continues to evolve, we'll see more roles shift from technical execution to strategic judgement. The most valuable professionals will be those who can:
- Ask the right questions
- Frame problems effectively
- Make sound decisions
- Provide meaningful direction to AI tools
## Conclusion
Eno's observation from nearly 30 years ago has become a blueprint for thriving in the AI era. The question is no longer "Can you do it?" but "What should you do, and why?" As technical barriers continue to fall, our ability to exercise good judgement becomes our most valuable asset.
---
## Interior Design Fundamentals
> Exploring the core principles of interior design through Noah Daniel's insightful video series, covering ground rules, material palettes, and lighting.
In today's world of social media and quick-fix design advice, it's easy to find interior design content that looks good on the surface but lacks substance. Many popular design tips focus on superficial aesthetics without considering the fundamental principles that make spaces truly work. That's why I've been following Noah Daniel since he first appeared on YouTube - his approach to design resonates deeply with me. His videos capture an essence of design that goes beyond mere aesthetics, focusing on fundamental principles that create meaningful and functional spaces. Here are three of his insightful videos that cover core aspects of interior design.
## 1. Ground Rules for Interior Design
Noah breaks down four essential principles that should guide every design decision. The first principle, **Form Follows Function**, emphasizes that every design element must serve a purpose. Aesthetics should never compromise functionality, and the space must work for its intended use.
The second principle, **Honest Materials**, encourages us to use materials that are true to their nature. This means avoiding materials that try to be something they're not, and instead letting materials speak for themselves.
**Consider the Context** is the third principle, which reminds us that design should respond to its surroundings. This involves understanding the building's history and location, and creating harmony with the existing environment. It's about designing for the specific place rather than applying generic solutions.
Finally, **Authentic Placemaking** focuses on creating spaces that feel genuine and meaningful. The design should tell a story and reflect the people who use them. This principle helps avoid the cookie-cutter approach that's become so common in modern interior design.
## 2. Material Palettes
This video is one of my personal favorites, as it helped me develop a deeper appreciation and technical understanding for design choices I had been making intuitively. Noah's exploration of material palettes goes beyond the surface-level "what looks good together" approach, diving into how to create cohesive material relationships that work together harmoniously.
## 3. Lighting Design
What makes Noah's approach particularly valuable is how he connects principles to create cohesive, meaningful spaces. His emphasis on authenticity and function over pure aesthetics creates designs that are not just beautiful but also practical and enduring.
The way he explains these concepts makes them accessible while maintaining their depth and importance. It's this combination of practical knowledge and philosophical understanding that makes his content so valuable for anyone interested in interior design.
Whether you're a professional designer or someone looking to improve their living space, these videos provide a solid foundation for understanding what makes good design work. They remind us that great interior design is about creating spaces that are not just visually appealing but also functional, authentic, and meaningful to the people who use them.
---
## Permission to Enjoy
> A reflection on seniority, freedom, responsibility, and the power of a mentor's simple advice.
A manager and mentor of mine once gave me advice that stuck: just do more of the things you enjoy.
With seniority comes freedom—but also responsibility, and, more often than not, stress. I'm expected to figure out my own goals and the best way to have impact. That's a lot to carry, and it's easy to get stuck in the daily mire of meetings, process, and busy work.
**Just do more of the things you enjoy**
That simple cue was exactly what I needed. It helped me de-clutter my days, find more joy in my work, and, as a result, have more impact.
---
## Building a Music Player: YouTube as a Backend
> How I built a music player for kohlhofer.com that pulls from a YouTube playlist, fetches video backgrounds, and focuses on an integrated audio/visual listening experience.
The [music page](https://kohlhofer.com/music) on my site is a simple but effective way to share my electronic music. Instead of uploading tracks or managing files, I just maintain a dedicated playlist on YouTube. The site pulls in the latest videos from that playlist automatically.
I fetch the background image for each track using the YouTube API. The result is a dynamic, ever-changing backdrop that matches the currently playing video.
Users get a focused, centered experience: you can shuffle, play, pause, and skip tracks right from the page. No distractions, no clutter—just music and visuals, front and center.
[](https://kohlhofer.com/music?v=7MWWRs_Nyj8)
Another nice touch: the URL auto-updates as you play, allowing for deep linking to specific videos. That means you can share a direct link to any track—like [this one](https://kohlhofer.com/music?v=7MWWRs_Nyj8), which is a fairly early piece paired with a snapshot of a nice moment in France.
---
## Let Go and Trust
> A reminder that excellence comes from trust, not control.
This section from another post makes for a good reminder for myself:
> My experience as a manager and team leader has taught me that the best results come when you let go of control and trust the people (and now, the tools) you work with. Excellence rarely comes from micromanagement or rigid prescriptions—it comes from creating space for others to contribute, experiment, and surprise you.
— from [Vibe Coding kohlhofer.com: Creation at the Speed of Thought](/blog/vibe-coding-kohlhofer)
---
## Visualizing Chaos: The Lorenz Attractor
> A fun exploration of chaos theory through code, creating an aesthetic visualization of the Lorenz attractor using P5.js.
## A Primer on Chaos Theory
Chaos theory studies how small changes in initial conditions can lead to vastly different outcomes - the famous "butterfly effect." The Lorenz attractor, discovered by meteorologist Edward Lorenz in 1963, is one of the most iconic examples of this phenomenon. It's a set of chaotic solutions to a simplified system of equations that model atmospheric convection.
What makes the Lorenz attractor fascinating is its "strange attractor" behavior - the system never repeats exactly the same path, yet it's confined to a specific region in space, creating an intricate, butterfly-like pattern that's both deterministic and unpredictable.
## CodePen and Aesthetic Visualization
I created this visualization on [CodePen](https://codepen.io/kohlhofer/pen/ZExzGLK/6dcf9eed602926b0ea193420e56bd4e4), using P5.js to bring the mathematical concept to life. P5.js proved to be the perfect tool for this project - its simplicity and animation capabilities made it possible to create an interactive visualization with relatively few lines of code.
The result is a piece that captures both the mathematical beauty and the chaotic nature of the system. From there, I simply ported it to [kohlhofer.com/lorenz](https://kohlhofer.com/lorenz). You can read more about that process in [this post](https://kohlhofer.com/blog/vibe-coding-kohlhofer).
## The Technical Side
The core of the visualization is surprisingly simple - just three differential equations:
```
dx/dt = σ(y - x)
dy/dt = x(ρ - z) - y
dz/dt = xy - βz
```
Where σ (sigma), ρ (rho), and β (beta) are parameters that determine the system's behavior. The magic happens when we integrate these equations over time, plotting the resulting points in 3D space.
## The Aesthetic Approach
While the mathematics behind the Lorenz attractor is fascinating, I wanted to create something fun. The visualization features smooth, flowing animations and dynamic camera movements that bring the mathematical concept to life. You can experience the full version at [kohlhofer.com/lorenz](https://kohlhofer.com/lorenz), where you can watch the system evolve in real-time.
## Part of a Larger Collection
This project lives in my "Bits & Pieces" collection at [kohlhofer.com/bits](https://kohlhofer.com/bits) - a playground where I dump my afternoon coding experiments and visual explorations. It's where I try out new ideas, play with different technologies, and create things just for the fun of it. The Lorenz attractor is just one of many experiments where I mix code, design, and a bit of mathematical curiosity to create something visually interesting.
## What's Next?
The Lorenz attractor visualization serves as a perfect example of how mathematical concepts can be transformed into engaging visual experiences, making complex ideas more accessible and enjoyable to explore.
---
## Vibe Coding kohlhofer.com: Creation at the Speed of Thought
> How I built kohlhofer.com trying out a new approach to design and software development.
_**Edit (May 2025):** Since writing this, "vibe coding" has become a mainstay term. I still think it's a terrible name—but the approach and speed it describes are here to stay._
I built the new version [kohlhofer.com](https://kohlhofer.com) in just a few days, and the process felt less like a solo project and more like collaborating with a high-performing team—only much faster. Some people call this "vibe coding"—letting intuition, rapid iteration, and AI support drive the entire creation process. I don't love the term (it's not mine), but it does capture the spirit of how quickly and fluidly things came together.
## Did I code it? Defenitely not.
Did I design it? Absolutely. But not in the traditional sense. I directed the design much like you would when working with a great team of designers: setting the vision, making key decisions, and letting the details emerge through fast feedback and iteration. With AI as my creative partner, the boundaries between design, content, and implementation blurred. It was all happening at once.
## Rethinking engineering principles?
Coding principles like DRY (Don't Repeat Yourself) matter less because the AI is perfectly happy to update navigation elements or content in multiple places. And with the site hosted on GitHub Pages, deployment and updates are effortless. The friction of manual updates is gone, so you can focus on what matters—clarity and experience. It's a simple, robust solution for a personal site that's always evolving.
## Iteration Over Implementation
The [maps page](https://kohlhofer.com/map) on kohlhofer.com is a great example of this new workflow. It's built with D3, and the core implementation didn't take long at all. What surprised me was how much of my time was spent not on the technical side, but on iterating through the presentation and design details—colors, layout, interactivity, and how the data should feel. With AI and modern tools, I could focus entirely on the result and the user experience, rather than wrestling with the underlying code.
The [bits page](https://kohlhofer.com/bits) is another testament to this new way of working. I took some of my older CodePen explorations—like the [City](https://kohlhofer.com/city) generator and [Lorenz](https://kohlhofer.com/lorenz) visualizations—and quickly ported them over to the site. I barely touched any code myself. AI created the scaffolding, and I simply talked through the integration, describing what I wanted and how things should fit together. The process was fast, fluid, and let me focus on the creative and conceptual side rather than the technical plumbing.

## Lessons Learned: Letting Go and Trusting the Process
My experience as a manager and team leader has taught me that the best results come when you let go of control and trust the people (and now, the tools) you work with. Excellence rarely comes from micromanagement or rigid prescriptions—it comes from creating space for others to contribute, experiment, and surprise you.
I've found the same principle applies when working with AI. The less prescriptive I am, the more surprising—and often delightful—the results. I enjoy being surprised at work and in life, and this new way of building things rekindled that sense of discovery.
I'll do a lot more of this.
---
## Coding as a Tool: Generating Patterns for the Siding of a new House
> How I used code to create a natural-looking random pattern for board and batten siding, ensuring both aesthetic appeal and structural requirements.
I always wanted to build a house and had a life long fascination with architecture. When the opportunity finally came to build our own home, I found myself facing an interesting challenge: I wanted to create something more interesting than the traditional board and batten siding pattern, while still using the cost-effective fiber cement panels that are standard in modern construction. The goal was to create a pattern that would look natural and random while meeting the specific structural requirements of these practical, durable materials.
### The Challenge
As anyone who's ever worked on a building project knows, achieving balance between aesthetics and function is no easy task. I had a vision for the siding—something that looked natural, yet fit within the constraints of structural requirements. Specifically, I needed to:
1. Create a genuinely random pattern that didn't feel forced or artificial.
2. Place battens in specific locations where large fiber cement panels meet.
3. Avoid odd-looking combinations that would be noticeable or out of place.
4. Communicate the final pattern clearly to the builders.
The task seemed simple at first, but quickly became clear that the devil was in the details.
## The Solution
I turned to code to solve this problem. Using CodePen, I created a tool that could generate random patterns while respecting certain constraints.
Here's a live version of what I came up with:
## The Process
I experimented with various random seeds and pattern generation algorithms until I found a combination that produced results that looked natural while avoiding any awkward patterns. The key was to:
1. Define fixed points where battens must appear (panel joints)
2. Generate random positions for additional battens
3. Apply rules to ensure minimum and maximum spacing
4. Visualize the result in real-time
After many iterations, the code was starting to show results that satisfied both my design sensibility and the technical requirements.
### The Result: Bringing the Vision to Life
The photos below show the siding implementation, which was a direct result of those hours spent in front of the screen, tweaking code and testing patterns.
## Code and Generative Architecture
This project is a perfect example of how coding can be a powerful tool in unexpected places. By using code to generate and visualize the pattern, I was able to:
1. Quickly iterate through different possibilities
2. Ensure consistency in the pattern
3. Provide clear, unambiguous instructions to the builders
4. Save time that would have been spent manually drawing patterns
The result is a siding pattern that looks natural and random, but was actually carefully designed and controlled through code.
You can explore the code and try different seeds in the CodePen above. Each seed will generate a different pattern while maintaining the required constraints.
This project demonstrates how coding can be applied to solve real-world problems in unexpected ways. We were able to achieve a result that looks natural while meeting all structural requirements. I am reall happy with the outcome and had a blast working on this.
---
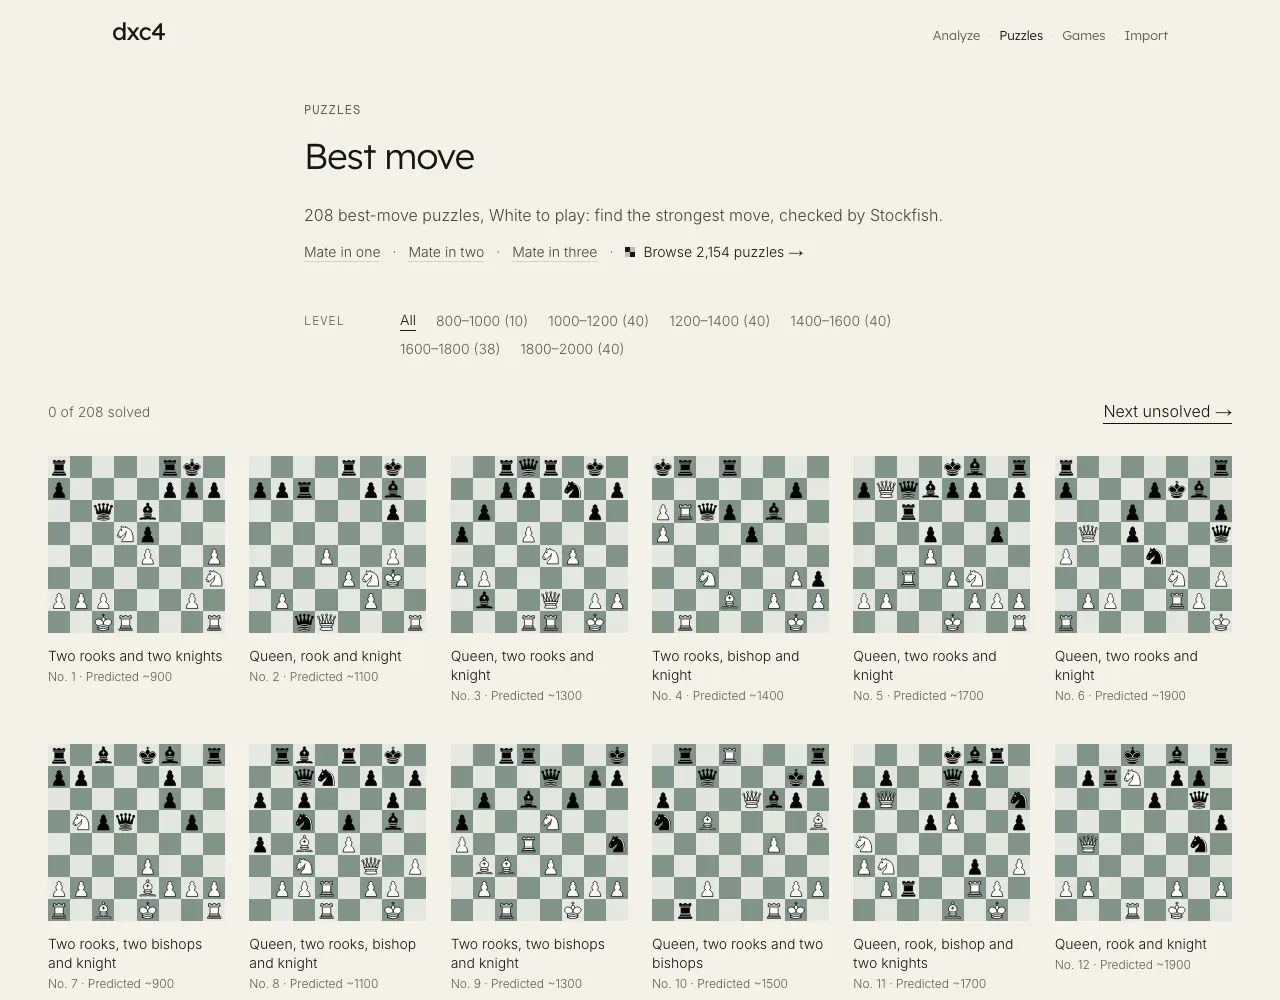
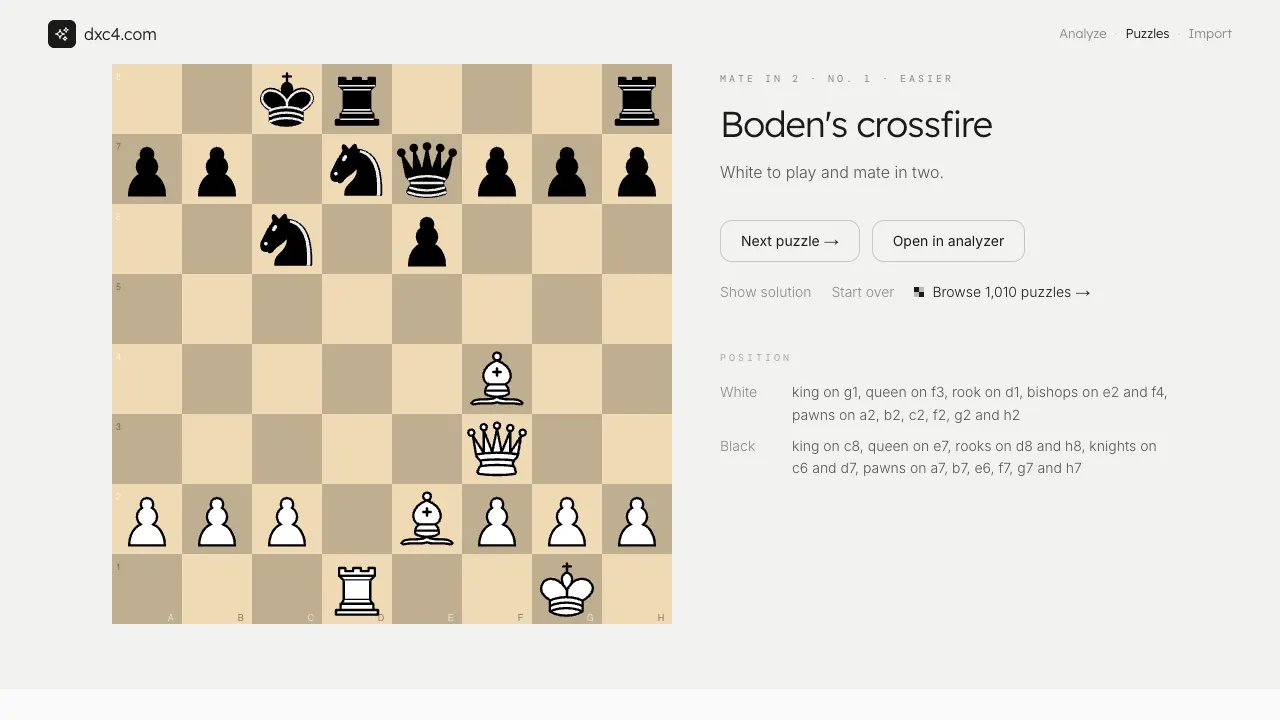
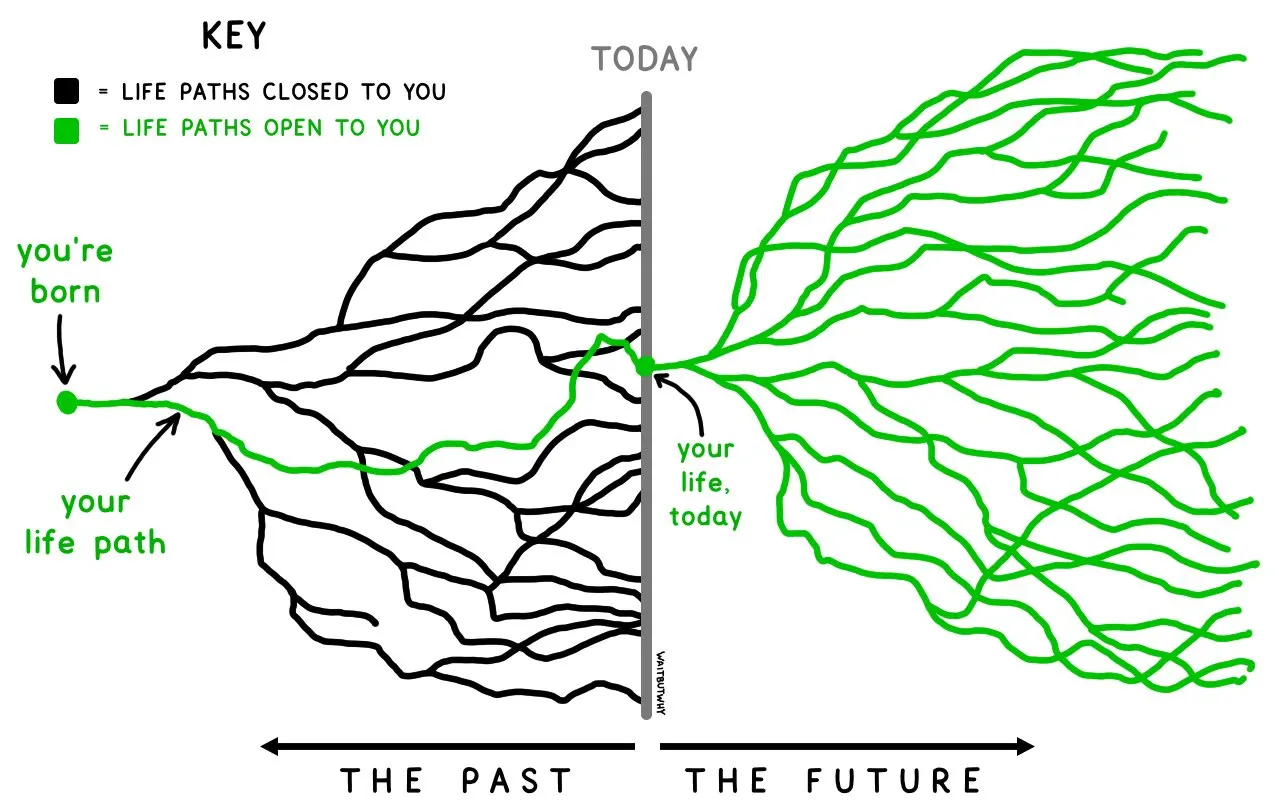
 ## From Playdate to Full Power
The first version of Chaos Studies was built for the [Playdate](https://play.date/), a tiny handheld with a crank and a 1-bit display. That constraint forced me to think about what mattered most: the visual rhythm of particles tracing their deterministic-yet-unpredictable paths, and the physical delight of manipulating chaos with a crank. The computational demands of tracking and moving thousands of points exceeded what the delightful Lua language could handle, requiring a custom C module.
 Porting to iOS and macOS meant shedding those healthy constraints. More raw power. Full color. Room for more parallel spatial audio. Multi-touch. The Metal rendering pipeline. But the core idea remained the same: give someone direct, tactile control over a chaotic system and let them feel its behavior.
## Nine Windows into Chaos
The app features nine strange attractors, each with its own character. The iconic Lorenz is restless, tracing its familiar butterfly wings. Rössler feels meditative, spiraling in toroidal bands. Halvorsen is architectural, exhibiting striking crystalline symmetry. Chen extends Lorenz into more turbulent territory. Each attractor required its own tuning until it felt right. Fast enough to see the dynamics unfold, slow enough to follow individual particle paths.
## Particles with Memory
Thousands of points trace paths through phase space. Each point starts hot—literally rendered in red—and gradually cools as it ages, creating trails that show where the system has been while emphasizing where it's going. When points grow cold enough, they drift outward and fade, replaced by fresh particles that continue the integration.
The recycling strategy took iteration to get right. Early versions replaced points randomly, which looked jittery. The final approach prioritizes replacing the coldest points first, creating smooth visual decay.
Metal handles the rendering across multiple pipelines.
 ## Sound That Moves Through Space
At its core is the cursor synthesizer—a real-time oscillator highlighting the current particle as it traces through phase space. Velocity controls the bass frequency (deliberately matching the Playdate version), vertical position adds harmonics, and a low-pass filter opens up with faster movement. The stereo field tracks your horizontal position.
Layered over this are seven music stems, each positioned in 3D space: tings float above, pad drones sit below, percussion anchors the front, bass line to the right, cello behind. As you rotate the camera, the stems pan and attenuate based on their new positions relative to your viewpoint. Headphones reveal the full effect—rotating the attractor literally rotates the soundscape around you.
The stems were composed on the OP-XY by Teenage Engineering (who also helped Panic design the Playdate hardware). I split the composition into spatial tracks specifically for this purpose.
The explosion and implosion effects layer multiple synthesized sounds with careful timing—details that took tuning to make the visual experience feel visceral. Getting the mix right across tiny built-in speakers and expensive headphones took more iteration than I expected.
 ## Art for Art's Sake
There's no goal. No score. No puzzle to solve. Chaos Studies exists purely as an experience—[art that doesn't need to serve a purpose beyond itself](/blog/art-design-purpose). Something to sink into, manipulate, and watch unfold. It's the kind of project that might never have existed without the ability to explore ideas quickly enough that "just for the joy of it" becomes a reasonable justification. But that freedom doesn't replace the discipline of refinement—it just means you can afford to be ambitious about what you refine.
## A Convergence of Interests
Chaos Studies sits at an intersection. It harkens back to creating visceral experiences in the game industry. It taps into my knowledge of electronic music and sound synthesis. It draws on design at large and the craft of interactive software. And it touches on math and the philosophical implications of chaos.
## Try It
Chaos Studies is available on [the App Store](https://chaosstudies.app/) for iPhone, iPad, and Mac. Put on headphones. Manipulate the chaos. Let the sound move around you.
In a world optimized for engagement metrics and endless algorithmic feeds, software that simply asks you to slow down and explore feels like a breath of fresh air.
---
## Converging on Reality
> Machine learning models across languages, molecules, and proteins are converging toward similar representations—a hint at underlying structure.
From [Ethan Mollick on LinkedIn](https://www.linkedin.com/posts/emollick_recently-llms-were-found-to-encode-different-activity-7411757757713907713-QjVu):
> Recently, LLMs were found to encode different languages in similar ways, suggesting a sort of Platonic representation of words.
>
> It now extends to science: 60 ML models for molecules, materials & proteins (all with different architectures & training data) converge toward similar encodings of molecular structure.
>
> As models improve, they agree more on what makes two molecules "similar." They may be converging on a shared representation of physical reality (but models are still constrained by their data).
I find this a fascinating hint at an underlying structure of information and reality.
Give [Ethan](https://www.linkedin.com/in/emollick/) a follow—he's a consistently considerate and often humorous source of insights on all things AI.
---
## A Map of Gaps
> Why knowing what you're bad at matters more than knowing what you're good at—for learning, for work, and for building teams that actually complement each other.
Had a good conversation with a candidate recently about strengths and weaknesses. Not the usual interview dance where weaknesses get reframed as strengths in disguise. An honest exchange about what we're each not good at and how we compensate.
It reminded me how rarely we talk about this directly—and how enabling it is when we do.
## The Real Skill
Knowing your strengths tells you where to deploy yourself. But **knowing your weaknesses tells you who you need around you**.
That's the more useful map. Not a catalog of what you're good at, but a clear picture of the gaps—and a strategy for filling them by leaning on others who are strong where you're not.
This isn't about self-deprecation. It's about self-awareness that actually leads somewhere. If I know where I fall short, I can seek out collaborators, build teams, and structure work in ways that compensate. The gaps become a design constraint, not a liability.
## A Career Theme
Looking back, the most enabling pattern in my career has been exactly this: finding people whose strengths complement my weaknesses, and offering the reverse.
It changes how you hire. Instead of looking for people who are good at the same things you are, you look for people who cover what you can't. It changes how you collaborate. You stop pretending you can do everything and start [trusting others](/blog/let-go-and-trust) to handle what they're better at. It changes how you grow. You stay humble about your limits and curious about improving them, which is the [growth mindset](/blog/praise-effort-not-talent) in practice.
The alternative—projecting competence in every direction—is exhausting and brittle. Eventually the gaps show up anyway. Better to know them, name them, and build around them.
## Why It's Hard
We're trained to emphasize strengths. Performance reviews, job interviews, professional branding—all of it pushes toward articulating what you're good at. Admitting weakness feels like giving something away.
But teams built on pretense fail in predictable ways. Everyone is covering gaps that nobody acknowledges. When those gaps finally surface, there's no structure to handle them.
I'd rather work with people who can say clearly what they're not good at. It makes everything else more trustworthy. If someone knows their limits, I can trust their confidence in other areas.
## The Map Worth Making
So here's the question worth sitting with: what are you bad at? Not as an exercise in humility for its own sake. But as real intelligence about who you need, what you should delegate, and where you still have room to grow.
The map of gaps is a blueprint for the career you actually want—one where you're not trying to be good at everything, but building something better by leaning on others.
---
## The One Thing Constraint
> Good science fiction changes one thing and builds a world around it. Can the same work in product design?
The best science fiction worlds feel inevitable. Not because they're familiar, but because they're coherent. Pick one impossible thing—teleportation, immortality, telepathy—and trace every consequence. The world builds itself from that single change.
Change too much and it falls apart. The reader stops believing.
## The Credibility Problem
When a science fiction world has teleportation *and* telepathy *and* time travel *and* magic crystals, you start to notice the seams. The writer is just adding whatever feels convenient for the plot. The world loses internal logic. It stops feeling real because nothing holds it together.
The single change is what creates credibility. It forces the author to think through implications. If everyone can teleport, what happens to cities? To borders? To privacy? To crime? To relationships? The one thing ripples outward, reshaping everything it touches in ways that feel inevitable.
That discipline is generative. It creates the world.
## Playing With One Change
I've been doing this lately with product ideas. Pick one change and follow it. **What if just one element was different?**
No database. Everything in the browser. No cloud, local only!
Each one reshapes what's possible. "No database" pushes you toward local-first, toward what can live in memory, toward sync without a source of truth. "Everything in the browser" surfaces URL encoding, WebAssembly, service workers—a completely different architecture.
The change propagates. That's the point.
## Why One Thing Matters
Without that singular change, you follow well-worn patterns. Use a database because that's what you do. Put it in the cloud because everyone does. The solutions are familiar because nothing pushes you to reconsider.
Change too many things at once and you're just listing preferences. "I want it fast *and* beautiful *and* cheap *and* flexible *and* simple." Those aren't changes. They're wishes.
But change one foundational element—one thing that affects everything else—and your brain has to leave the path. You're world-building. The single change isn't a limitation—it's permission to think differently.
## The If If If
The questions are cheap: *if if if*. But following one all the way through is hard. It means resisting the urge to compromise, to add just one more exception, to let the change slip when it gets uncomfortable.
Good science fiction stays disciplined. It picks one impossible thing and makes everything else follow. The world feels real because it's consistent, because the author did the work of thinking through implications instead of just inventing conveniences.
Good product design can work the same way. Pick one change that matters. Follow it to its conclusion. See what world it builds.
---
## From Sketch to Site in Hours
> Building Field Bureau + Werkstatt, a minimal site born from a journal sketch and iterated into existence.
Field Bureau + Werkstatt is an independent design and technology practice. Bureau for analysis and discernment. Werkstatt for experimentation and craft. Field for real-world context and iteration.
The design tries to capture and reflect that ethos. So does the process of making it.
 ## Bureau, Werkstatt, Field
**Bureau:** I developed the key concept and captured it in a minimal (and tiny!) sketch in my journal. Just the essentials: logo, concept, navigation.

**Werkstatt:** Initial implementation was quick thanks to AI. Then came the real work: spacing, typography scale, color values, image treatment. Design decisions that require looking, adjusting, looking again.
**Field:** A timely design critique with [John](https://www.johnwlong.com/) brought real-world perspective that refined the final result.
I like it best on desktop (see screen) but it scales nicely to mobile too. Learn about [Field Bureau + Werkstatt](https://fieldbw.com).
---
## In Appearance Only
> Unintentional imposters optimizing for output over outcome. AI just does it even better.
AI content often looks right, if not perfect. The structure is there, the format is correct, the polish is undeniable. Yet it can feel hollow—disconnected from genuine understanding.
We act like this is new. Like AI invented producing work that meets expectations in form while missing the substance. But we've been doing this for decades.
## Output Without Outcome
Watch a product team doing everything by the book. They're running sprints, conducting user research, building roadmaps, measuring metrics. All the outputs are there: personas, journey maps, OKRs, retrospectives. Perfect artifacts.
And yet the outcome is off. The product doesn't solve the problem. The features miss the mark. The strategy feels hollow.
Or look at design work that seems deeply researched. Stunning presentation, articulate rationale, sophisticated visual language. All the outputs of good design. But in practice, it doesn't serve users well. The outcome reveals the disconnect.
These frameworks and practices were invented for good reasons. Sprints were meant to break down complexity and enable rapid feedback. User research was meant to surface real needs before building. OKRs were meant to align teams around meaningful outcomes. They all emerged to solve real problems, and they work brilliantly—if you understand what problem they were trying to address.
But somewhere along the way, **the outputs became the goal**. Following the process became the measure of success. Creating the right artifacts became what "good" looked like. The work became performance.
## Organizational Imposters
The eerie part is how many people in organizations are unknowingly just pretending. They're not malicious. They're not consciously deceiving anyone. They've simply learned the patterns that signal competence and reproduce them faithfully. They know how to structure the presentation, format the document, run the ceremony. They're fluent in the language of their discipline.
But they've never connected it back to the original problem these practices were meant to solve. They're **imposters who don't know they're imposters**, because everyone around them is also checking whether the form is correct, not whether the substance is there.

## The Mirror
This is what's eerie about AI. It's extraordinarily sophisticated at meeting human expectations in form—more sophisticated than most people at matching expected patterns. It produces the right structure, the right tone, the right surface markers of competence.
But it's doing exactly what we've been doing: producing output that looks right without ensuring the outcome is right. The difference is that we're more critical of AI. We scrutinize its work with skepticism we rarely apply to human output. But that's already fading. AI's level of sophistication makes it increasingly hard to tell the difference.
When humans do it, we're often numbed to it. We've been swimming in it so long we stopped noticing.
AI shows us what our own work looks like when you strip away intent and understanding but keep the form intact. It's learned from everything we've produced, including all the work that looked right but wasn't. It reproduces the patterns we rewarded, the structures we validated, the forms we approved.
And we seem to like what we see.
## What This Means
I've been looking for the unintentional imposters for years. The ones who argue most forcefully for doing things right, for following process. They're often the ones most disconnected from why those processes exist. They've mistaken the map for the territory.
And with AI, the lesson is clear: to get value out of it, you have to **hold it accountable to purpose, not form**. Don't judge its output by whether it looks right. Judge it by whether it achieves the outcome you need. The same standard we should have been applying to human work all along.
The appearance of good work has always been the easiest thing to fake. Now we just have a mirror that makes it impossible to ignore.
---
## Embracing Interface Asymmetry
> Visual UIs and chat interfaces have opposite strengths. The asymmetry isn't a problem to fix; it's a pattern to embrace.
I've been reflecting on the friction between traditional UIs and AI chat interfaces. We've been forcing both input and output through the same interface paradigm for decades, and it's never worked well for both.
Visual interfaces are spectacular at one thing: showing you information. A map instantly conveys distances and relationships that would take paragraphs to describe. A dashboard lets you compare metrics at a glance. Product grids let you scan prices and features faster than any text summary could. When computers need to help us understand information, visual representations are unmatched.
But flip it around. Try to *tell* a computer what you want through those same visual interfaces.
Now you're clicking through nested menus, filling out forms with rigid validation rules, hunting for the right checkbox buried in settings. You're learning someone else's mental model of how data should be structured, memorizing which field goes where, adapting your intent to fit their predetermined categories. Every app has its own idiosyncratic input patterns. Every form demands you think like the database schema.
The sophistication we've built into visual output doesn't translate to input. It compounds complexity instead of absorbing it.
## The Inverse Interface
AI chat interfaces flip this entirely. They're phenomenal at input. You describe what you want in whatever words come naturally. You provide context in whatever order makes sense to you. You correct yourself mid-sentence, add caveats, reference things indirectly. The interface does the work of parsing intent, mapping your messy human input onto structured operations.
But ask a chat interface to help you compare options, and you're back to scrolling through paragraphs. Which hotel was cheaper? What were the trade-offs between those three approaches? The information is there, but you can't *see* it. Text forces sequential processing when what you need is spatial reasoning. It's the wrong medium for output.
The asymmetry is perfect. Visual interfaces fail where chat interfaces excel. Chat interfaces fail where visual interfaces excel. We've been stuck with one paradigm for decades: visual UIs for everything, input and output both forced through the same forms and buttons. Now we're adopting the other, wrestling with how to make chat and text convey what images show instantly. But the asymmetry isn't a problem to solve. We ought to embrace it.
## No UI for Input
What if the pattern that's emerging isn't "chat replaces everything" but something more surgical? Free-form text input (or spoken words) becomes the universal input layer. Describe what you want, refine it conversationally, express complex intent without learning app-specific conventions. Then, once the system understands, render the results in whatever visual form makes them comprehensible. Generate the dashboard. Show the map. Display the comparison grid.
The interface adapts to the output, synthesized on the fly based on what you asked for. Not a predetermined layout you're forced to interpret, but a visualization shaped by your specific question. The understanding of this asymmetry adds another level to something I wrote about [ephemeral software](/blog/2025-10-15-ephemeral-software). Traditional software isn't just wrong because it persists when it shouldn't. It's wrong because it forces a single interface paradigm to handle both directions of interaction. Code and interfaces should both manifest when needed and dissolve when done, but they should also split along natural lines: natural language for expressing intent, visual forms for understanding results. The output interface becomes just another part of the computation that appears in service of your purpose, then vanishes.

I've noticed this in my own projects lately. The friction isn't usually in viewing results; it's in communicating what results I want. The cognitive load isn't in understanding the data but in wrangling the controls.
This changes what we should be building. Stop trying to make chat interfaces that output everything as text. Stop trying to make visual UIs with better input forms. Instead, build systems that accept natural language input and generate the right visual representation for each specific query. The interface becomes a consequence of the question you asked, not a constraint you have to work within.
For designers and builders, this means rethinking the fundamental unit of interface design. Not "design a dashboard" or "design a form," but "design a system that can synthesize the right output format in response to expressed intent." The interface isn't the product; the capability to manifest appropriate interfaces is the product.
What would your tools look like if input and output weren't bound to the same interface?
---
## Turning the Ship
> Why organizational change takes time, why resistance is normal, and why momentum eventually works in your favor.
Changing organizational direction is like turning a massive ship. The larger the organization, the more this metaphor holds true.

You can't just yank the wheel and expect immediate results. The momentum of the existing direction carries the organization forward, resisting change.
I wrote about why [direction matters more than speed](/blog/direction-before-speed) in organizational momentum. But knowing where you want to go is different from actually getting there. I've seen this pattern enough times to know where people give up and where they push through.
Whether you're an executive, a team lead, or an individual contributor trying to drive change—the dynamics are the same. You're working against existing momentum, and that takes sustained effort regardless of your title.
## Many Small Pushes
Change happens through many small pushes, not one dramatic shift.
Each decision, each meeting, each communication that aligns with the new direction adds a small force vector. Initially, these forces seem insignificant against the massive momentum of the current direction.
But not all pushes are equal. The key is finding the levers that make the biggest difference. Some decisions cascade through the organization—who gets hired, what gets measured, which projects get funded, how teams are structured. These aren't just small pushes; they're force multipliers that touch everything downstream.
I've learned to look for these leverage points early. Where does attention naturally flow? What decisions do people watch to understand what actually matters? Those are your levers. Push there, and the effect compounds far beyond the immediate action.
Your levers look different depending on your position. An executive controls funding and structure. A team lead influences what gets celebrated and who gets hired. An individual contributor shapes technical direction through code reviews and architecture proposals. But the principle is the same: find where small actions create outsized impact.
Momentum is cumulative. Over time, these small pushes—especially the ones applied to the right levers—begin to add up. The ship starts to turn, slowly at first, then with increasing speed.
## The Resistance Phase
The most challenging period is the early phase, when you're pushing against existing momentum. This is when change initiatives often fail—leaders give up because they don't see immediate results. They expect the ship to turn on a dime, and when it doesn't, they conclude the effort is futile.
But this is exactly when persistence matters most. The resistance you're feeling is the organization's existing momentum pushing back. It's not a sign that change is impossible—it's a sign that you're pushing against something real.
Every decision is questioned. The old ways keep reasserting themselves. Progress is invisible or easily reversed. You're constantly explaining the same things. Exhaustion sets in for change leaders.
This is normal. This is the physics of organizational change.
## The Tipping Point
There comes a moment when the cumulative effect of all those small pushes reaches a tipping point. The ship's direction is changing, even if it's barely perceptible at first. This is when the change becomes self-reinforcing, when the organization's own momentum starts working in your favor.
At this point, something remarkable happens: the change becomes unstoppable.
The organization begins to generate its own momentum in the new direction. People start making decisions that align with the new direction without being told. The culture begins to shift naturally. New hires come in and assume this is just "how we do things here."
## When to Ease Off
Here's the counterintuitive insight: once the ship is turning, you need to ease off.
Just as it took sustained effort to start the turn, it will take sustained effort to stop it. The momentum that was working against you is now working for you. The change itself becomes inevitable.
This is why over-correction is a real danger. I've seen leaders who fought hard to initiate change not realize when the battle is won. They keep pushing with the same intensity, and the organization overcorrects, swinging too far in the new direction.
The art of organizational change is knowing when to push hard and when to guide gently. Early on, you push. Once momentum shifts, you steer.
## Why Change Feels Inevitable in Retrospect
Early-stage change feels difficult. Successful change feels inevitable in retrospect. The work you do in the resistance phase creates the foundation for the acceleration phase.
People who join after the tipping point can't imagine the organization any other way. They wonder what the big deal was. "Of course we do it this way," they say.
## What This Means for You
If you're driving change—at any level—start by identifying your levers. Where can you apply force that creates the biggest impact? This looks different depending on your position, but the principle is the same: find the decisions and actions that cascade.
Commit to sustained effort during the resistance phase. Don't expect immediate results. Celebrate small wins that align with the new direction. Keep communicating the why, relentlessly. Build a coalition of people pulling in the same direction.
After the tipping point, recognize when momentum has shifted. Ease off the intensity of your push. Guide rather than force. Watch for overcorrection. Let the organization's own momentum do the work.
Organizations that succeed in transformation understand they're playing a long game. They know that turning a ship takes time, that resistance is normal, and that once the turn begins in earnest, it becomes self-reinforcing.
Patience during the resistance phase. Recognition when the tipping point arrives. That's how you turn the ship.
---
## Direction Before Speed
> Why organizational momentum is a vector, and why moving fast in the wrong direction is worse than moving slowly in the right one.
Organizational momentum is a vector—it has both direction and magnitude. Without clear direction, increased speed only means you're getting lost more quickly.
I've watched this play out enough times to know the pattern. The fundamental truth is that **direction is everything**. You can have the fastest, most efficient execution in the world, but if you're heading in the wrong direction, you're just accelerating toward failure.
## The Vector Problem
I've seen organizations pride themselves on execution speed while drifting aimlessly. They measure velocity, track velocity, optimize for velocity—all while ignoring that velocity is a vector quantity. Without direction, speed is meaningless.
Even worse: scattered efforts across multiple directions. When your team pulls in five different directions with equal force, you don't get slow progress—you get zero progress. The vectors cancel out. All that effort, all that motion, adds up to nothing.
This is why alignment matters more than hustle. A team moving slowly but in the same direction will outpace a team sprinting in different directions every time.
This applies whether you're leading an entire organization, a team, or trying to drive change from any position. The physics are the same.

## The First Question
The first question should always be: **Where are we going?**
Only after that's clear should you ask: **How fast can we get there?**
This seems obvious when stated plainly, but I've seen organizations do the opposite. They start with execution, with process optimization, with speed improvements. They assume direction is already set, or that it will emerge from the execution itself.
It rarely does.
Organizations that succeed get religious about direction. They communicate it relentlessly. They use it as a filter for every decision. They're willing to say no to perfectly good ideas that point the wrong way.
## What Misdirection Costs You
Speed without direction doesn't just waste effort—it actively destroys value.
Teams build features nobody needs, faster. Engineers solve the wrong problems, more efficiently. Meetings proliferate to coordinate conflicting efforts. Burnout increases as people work harder for less impact. Morale drops as people sense the futility of their work.
It burns out your best people on meaningless work. It creates organizational debt that's harder to unwind the longer it continues.
## Getting Direction Right
Setting direction isn't about having a perfect vision from day one. It's about being clear enough that people can align their efforts.
When everyone can articulate where the organization is headed, decisions become easier because you have a filter. You can say no to good ideas that point the wrong way. Individual efforts compound instead of canceling out. Progress becomes visible and measurable.
## Why Speed Still Matters
None of this means speed doesn't matter. It does—tremendously.
When you can move fast, you reduce the cost of being wrong. If you can fix your mistakes as quickly as you make them, you can afford to make mistakes and learn from them. Speed reduces the need for slow deliberation because the feedback loop is tight enough that errors become cheap.
This is why the sequence matters so much. Direction first, then speed. With clear direction, speed becomes your advantage. Without it, speed just amplifies your mistakes.
Of course, setting direction is only the beginning. Actually changing an organization's direction—getting everyone aligned and moving together—is a different challenge entirely. I explore that in [Turning the Ship](/blog/turning-the-ship).
---
## Praise Effort, Not Talent
> How cultural differences in praising children shape mindset and what it means for how we raise our own kids.
I learned this years ago, but it stuck: in many cultures, when a child does something well, they hear "it shows how much you worked on this." In the US, that same kid often hears "you're so talented."
The difference is profound.
## Attribution Matters
One response attributes success to effort—something entirely within the child's control. The other attributes it to inherent talent—something fixed, something they either have or don't.
This isn't just semantics. It shapes how children understand success and failure. If you believe your achievements come from talent, what happens when you struggle? You assume you've hit your limit. If you believe they come from effort, struggle means you haven't worked hard enough yet.
## The Fixed vs. Growth Mindset
This is the difference between a **fixed mindset** (talent-based) and a **growth mindset** (effort-based).
Kids with a growth mindset embrace challenges as opportunities to improve. They persist through setbacks, see effort as the path to mastery, and learn from criticism. Kids with a fixed mindset do the opposite—they avoid challenges that might expose limitations, give up when things get hard, and take criticism personally because it threatens their self-image.
The mindset we foster through our words has real consequences.
## How I Practice This
I learned about this distinction when my first daughter was just born. It became something I internalized immediately—a lens I couldn't unsee once I understood it.
From the beginning, I've been intentional about how I praise. My instinct is still to say "you're so smart" or "you're naturally good at this." It feels good to say. Kids beam when they hear it. But I've trained myself to pause and reframe. Instead of "you're so talented," I say "I can see how hard you worked on this." Instead of "you're so smart," I say "I love how you figured that out." Instead of "you're a natural," I say "your practice is really paying off."
It's not always easy. The fixed-mindset language is deeply embedded in how we talk. But I've been doing this for years now, and it's become second nature.
## The Real Block Isn't Talent—It's the Belief in Talent
This isn't just about how we raise kids. It's about the limiting beliefs we carry about ourselves.
How many people say "I'm not good at math" as if it's an immutable fact about who they are? Or "I'm not creative" or "I'm not athletic" or "I don't have a technical mind"? These aren't statements about reality—they're self-fulfilling prophecies that become true precisely because we believe them.
The notion of talent is a real block. It gives us permission to stop trying. It lets us off the hook. "I'm just not wired that way" becomes an acceptable reason to never attempt something, never struggle, never improve.
I genuinely believe I could learn to do anything because the brain is remarkably good at learning things. I may be too lazy to put in the required time. I may be too old to justify the investment. But that's not a problem of potential—it's a problem of priorities and effort.
When we shift from "I don't have the talent" to "I haven't put in the time," everything changes. The barrier isn't who we are. It's what we're willing to do.
---
## Apple's Quiet AI Advantage
> Why the M-series neural engine may prove that Apple's so-called lag in AI is actually a head start in on-device intelligence.
What if the real AI inflection point is happening on my desk instead of in the cloud? That question keeps circling back every time someone insists Apple is “behind.”
The usual scoreboard about foundational models and their ever-increasing capabilities barely mentions what happens on the device in front of us. Apple has spent nearly a decade weaving neural hardware into phones, tablets, and Macs without turning it into a hype cycle. Those chips feel less like a spec race and more like a quiet promise: the intelligence you rely on should live where you already work.

## An Invitation Hiding in Plain Sight
Apple Intelligence was announced without fireworks. The feature list reads tame: writing tools, notification triage, a few system-level assistants. Yet the developer sessions were unmistakable in tone. Apple wants us to bring our workloads onto their silicon. Every lab, documentation drop, and office hour circled the same idea: Apple Intelligence is a platform—tap into it, extend it, keep the experience private by default. The message is gentle but persistent: use the hardware, keep the data on device, lean into personal context.
## Quiet Proof Already Shipping
Even before Apple put a label on it, the devices were already soaked in intelligence. Voice Isolation makes a noisy café call sound like a studio. Center Stage tracks people across a room without broadcasting any frames to the cloud. Photos quietly does its thing so everyday shots just look great, no matter how chaotic the scene. These are everyday features, almost boring, and yet the amount of local processing required is just amazing. They are case studies for what happens when neural compute is treated as part of the OS instead of an add-on service.
## Owning Processing, Owning the Model
Cloud AI still matters when you need scale, but it turns every interaction into a rental. On-device work flips the model. The bill was paid when the hardware shipped. The data never has to leave the user’s hands. The relationship becomes less about metering usage and more about delivering capability that earns space on the dock or in the menu bar. That quietly challenges the SaaS mindset. **It resonates with me because nothing about having my work aggregated, mined, or owned elsewhere feels right anymore.** If the intelligence lives with the user, a subscription to access their own information starts to sound dated.
The trade-off, of course, is that Apple’s privacy stance and hardware guardrails slow the wild experimentation that fuels open cloud models. But that constraint is also why the results feel less volatile—grounded, human-scaled, and willing to wait until the pieces fit.
## Selfish Alignment
Apple frames privacy as a core value, but it is also a competitive wedge. Safari’s tracking protections, Mail Privacy Relay, and App Tracking Transparency all happen to blunt Google’s data collection while keeping users inside Apple’s ecosystem. Motivation aside, the outcome aligns with my selfish interest. My browsing history, my app habits, my daily routines are harder to harvest. Apple’s incentive to differentiate just happens to protect the way I want to work: locally, quietly, without negotiating away ownership every time I tap an icon.
## What If We Lean In
So the question is: what if on-device intelligence is the differentiator that matters? Apple keeps building the stage and inviting developers to plug in. Their own features set the baseline; it is on us to decide whether we will design for a world where users expect their machines to be the primary place where judgment and creativity happen. If the next wave of intelligence is personal, Apple’s head start isn’t in training models—it’s in training expectations.
---
## Let's Talk About Your Next Role
> Why I ask teammates to think about their CV and what they want it to look like five years from now.
At some point, a question like this shows up in my 1:1s:
> When a future hiring manager glances at this role on your CV five years from now, what should their takeaway be?
It never happens in the first coffee chat. Once we understand how we work together, we zoom out and talk about the future story they want other leaders to see.
## Why Call the Shot Early
At a certain level, companies aren't hiring your tool kit—they're hiring you to **replicate outcomes** you've already produced. "Built the X team" or "owned the Y process" sounds like a job description. "Delivered $40M in new revenue by rebuilding the onboarding funnel" tells a future boss exactly why you belong in their org.
Framing the job that way does more than prep them for the next jump. It forces clarity on what matters now. Regardless of level, outcomes will always trump output. When we align on the result we want to be proud of later, we automatically steer toward the kind of impact that multiplies through the org right now—better focus, cleaner prioritization, stronger partnerships. Those outcomes compound even if they never leave the company.
## So What Will Those Future Bullet Points Be?
I ask them to reflect on what those bullet points on their future CV ought to be, and to ignore for that moment whatever may seem urgent or important. That forces a clarity of thought that is disconnected from the day-to-day and surfaces the gaps we need to close.
My job is to build the environment where they can make the bullet points they identify genuinely true. We adjust scope, pull in partners, or hunt for the metrics we need. It might mean clearing space to own messy problems, lining up the execs who need to see the work, or defending the project long enough for the impact to register. The question shows up in future check-ins: are the bullet points they named getting sharper or fuzzier?
And to be clear: it is their work and their responsibility. I can coach and unblock, but they own the story they're writing.
When someone's CV tells a story of meaningful outcomes, leadership roles open up faster than anyone expects—and the current org benefits because it needs those same outcomes. That's the leverage I want them to feel, because it pushes better decisions in the day-to-day work and sets them up for whatever they want next, whether that's a bigger role here or somewhere else five years out.
What bullet points are you creating right now to set your current and future self up for success?
*P.S. If you wonder what constitutes an outcome, I’m partial to Joshua Seiden’s take in "Outcome over Output": it’s any change in human or customer behavior that drives business results.*
---
## Ephemeral Software
> In the age of AI, it's not the UI that becomes ephemeral—it's the software itself. Code manifests when needed and dissolves when purpose is served.
There's a narrative emerging around Apple's new liquid glass and similar interfaces: that **UIs are becoming ephemeral**, floating at the periphery, appearing only when needed and fading away when done. It's a compelling vision of unobtrusive design. But it misses the deeper shift.
It's not the UI that's becoming ephemeral. It's the software itself.
## Beyond Interface Design
The focus on ephemeral interfaces—glass panels that fade in and out, context-aware overlays that materialize at the right moment—treats the problem as one of presentation. Make the UI less intrusive, more elegant, more responsive to context, and you've solved the problem of software's constant presence in our lives.
But the software underneath remains. The application still exists, with its code, its dependencies, its update cycles, its presence on your device or in the cloud. We've simply made it quieter.
## Software as Manifestation
What AI enables is something fundamentally different: **software that manifests when needed and ceases to exist when purpose is served**.
Not hidden behind a subtle interface. Not sleeping in the background. But actually not there until the moment you need it, then dissolved once the need passes.
This is code as pure means to an end. No installation. No maintenance. No presence outside the context of immediate purpose. You don't think about "the software" or "the app"—you think about what you're trying to do, and the necessary computation simply happens.
## The Shift in Focus
Traditional software demands attention. Even with the most refined UI, you're aware of the application, its capabilities, its limitations, where it lives, when it was last updated. The software has identity and persistence.
Ephemeral software has none of that. It exists only in service of immediate purpose. The code that handles your request might be generated on the spot, executed once, and discarded. The "application" is just a pattern of computation that appeared, did its work, and dissolved.
This changes what software *is*. Not a thing you acquire and maintain, but a capability that materializes when invoked.
## Living at the Edge of Purpose
Apple's liquid glass and other peripheral interfaces are moving in the right direction—reducing the cognitive burden of constant interaction with software. But they're still designing containers for persistent applications.
The next step is software without containers. Without the assumption of persistence. Code that forms when you have a purpose and dissolves when that purpose is complete.
This doesn't mean software vanishes entirely—the infrastructure, the models, the systems that enable this manifestation all exist. But from the user's perspective, there's no software to manage. Only purpose, and the means to fulfill it.
## A Different Kind of Transparency
Transparent UI design tries to minimize the interface between you and your intent. Ephemeral software takes this further—interfaces still exist, but they're no longer rigid, persistent things. They manifest as part of the ephemeral software itself, appearing only to the degree necessary for the task at hand.
The focus shifts entirely away from the software itself—its design, its features, its presence—toward the outcomes it enables. Code becomes truly invisible, not through clever design but through fundamental impermanence. And interfaces become fluid, forming only when purpose demands and dissolving once that purpose is served.
## No Longer Science Fiction

Watch any science fiction film and you'll see interfaces that seem absurd by today's standards. Characters speak their intent and intelligence simply does their bidding. Systems understand context without explicit instruction. Capability materializes exactly when needed, in exactly the form required, then vanishes. No applications to open, no software to maintain, no visible machinery between thought and execution.
We've always dismissed this as fantasy—divorced from the practical reality of how software actually works. The messy truth of dependencies, installations, updates, compatibility, persistence.
But that gap is closing. What looked like magical thinking is becoming a tangible near-term future.
The intelligence exists. The infrastructure exists. The capability to generate, execute, and dissolve code on demand exists. What remains is the transition from thinking about software as something we build, install, and maintain, to software as something that simply happens when purpose demands it.
The science fiction version isn't about better interfaces. It's about the absence of software as a distinct concept. Just intelligence that manifests capability in service of intent. That future is no longer fiction. It's the logical endpoint of what we're building right now.
---
## Hiring Designers Who Know Which Lever to Pull
> The three non-negotiables I expect from senior designers: relentless feedback, selling the work, and knowing when each skill should lead.
I hire designers who can already run without a playbook. The skills I don't want to spend my time teaching are exactly the ones that keep teams moving when I'm not in the room.
Tools, systems, and product context are easy to transfer. Judgment is not. So I look for three signals before we ever talk about the UX architecture, the flows we’ll extend, or how the interface gets dressed.

## 1. Get and Use Feedback
Great designers do not treat critique as a chore. They *engineer* it.
They know when to show work early to unblock an assumption and when to wait until the stakes are higher. They arrive with specific questions, not just a deck. They synthesize what they hear into decisions, not transcripts. Most importantly, they close the loop—telling partners what changed and why.
If I have to coach someone to invite the right voices, to separate taste from risk, or to turn critique into direction, we're already behind.
## 2. Sell the Idea and Make It Happen
The best designers generate buy-in as they design. They narrate tradeoffs in plain language, expose decisions to the right people at the right time, and move ambiguity forward instead of letting it stall in Slack threads.
They can articulate *why* a path is worth pursuing in a way that product, engineering, and leadership understand. They listen for friction, adapt without losing the core insight, and know when to escalate versus when to absorb feedback locally.
If I’m the only bridge between design intent and team execution, the designer is not yet ready for the work I need done.
## 3. Choose the Right Lever
Feedback (1) and alignment (2) are levers. Judgment is knowing which one changes the system, and what happens if the wrong lever is pulled.
The right move might be to bring everyone together and realign the plan, or it might be to ship with the conviction the team already has. Feedback and alignment are critical tools of the trade; they only create value when they’re deployed with intent. Designers have to read the room, the roadmap, and the risk profile before pulling either lever. If you solicit feedback in a moment that demands conviction and alignment, you dilute momentum and signal you don’t actually believe in the direction. Worse is pushing hard to sell your idea when the room is offering critical insights you need to absorb—you burn credibility and miss the improvement. I need people who sense the difference and act without waiting for permission.
## What I Bring to the Table
When those skills are present, I can go all in on supporting them—removing blockers, sharing hard-won context, and opening rooms they need to influence. I can elevate their craft with sharper critiques, give them the space to run bigger experiments, and amplify their impact across the organization because [I trust their judgment](/blog/let-go-and-trust). That is the partnership I'm hiring for.
Without them, I'd spend my time teaching behaviors that should have been forged through earlier teams, mentors, and hard projects. That's a bad trade for everyone.
There's [plenty more](/blog/finding-balance-in-leadership) to forming a great design team—but being relentless about feedback, selling the idea, and choosing when to do which is not optional.
---
## Menu Volume – Feedback First, Features Second
> How shipping MIDI Volume Control proved that no project is too small to pivot when immediate user feedback points to the real product.
No project is too small to surprise you once you talk to customers. I shipped [MIDI Volume Control](/blog/midivol-app-store) a few days ago to scratch my own itch—see that post for the backstory. First desktop app, first trip through App Store review, first time I wired a MIDI controller directly into macOS volume. I assumed the follow-up conversations would be all about latency, channel support, controller mappings.
Instead, two friends saw it in action, bought it on the spot, and then told me they didn't care about MIDI at all—they wanted the instant menu bar control. That single conversation flipped the brief: *"The sliders are perfect. The MIDI stuff is extra."* They just wanted to keep Apple Music tucked under their work without losing the soundtrack.
I built the menu bar controls as a convenience. A bonus. A simple way to see and adjust system and Apple Music volume at a glance. Turns out that *was* the product for a whole group of people. The MIDI piece—the thing I started from—is still excellent for the much smaller crew who live with MIDI controllers (like me), but it's not the headline for everyone else.
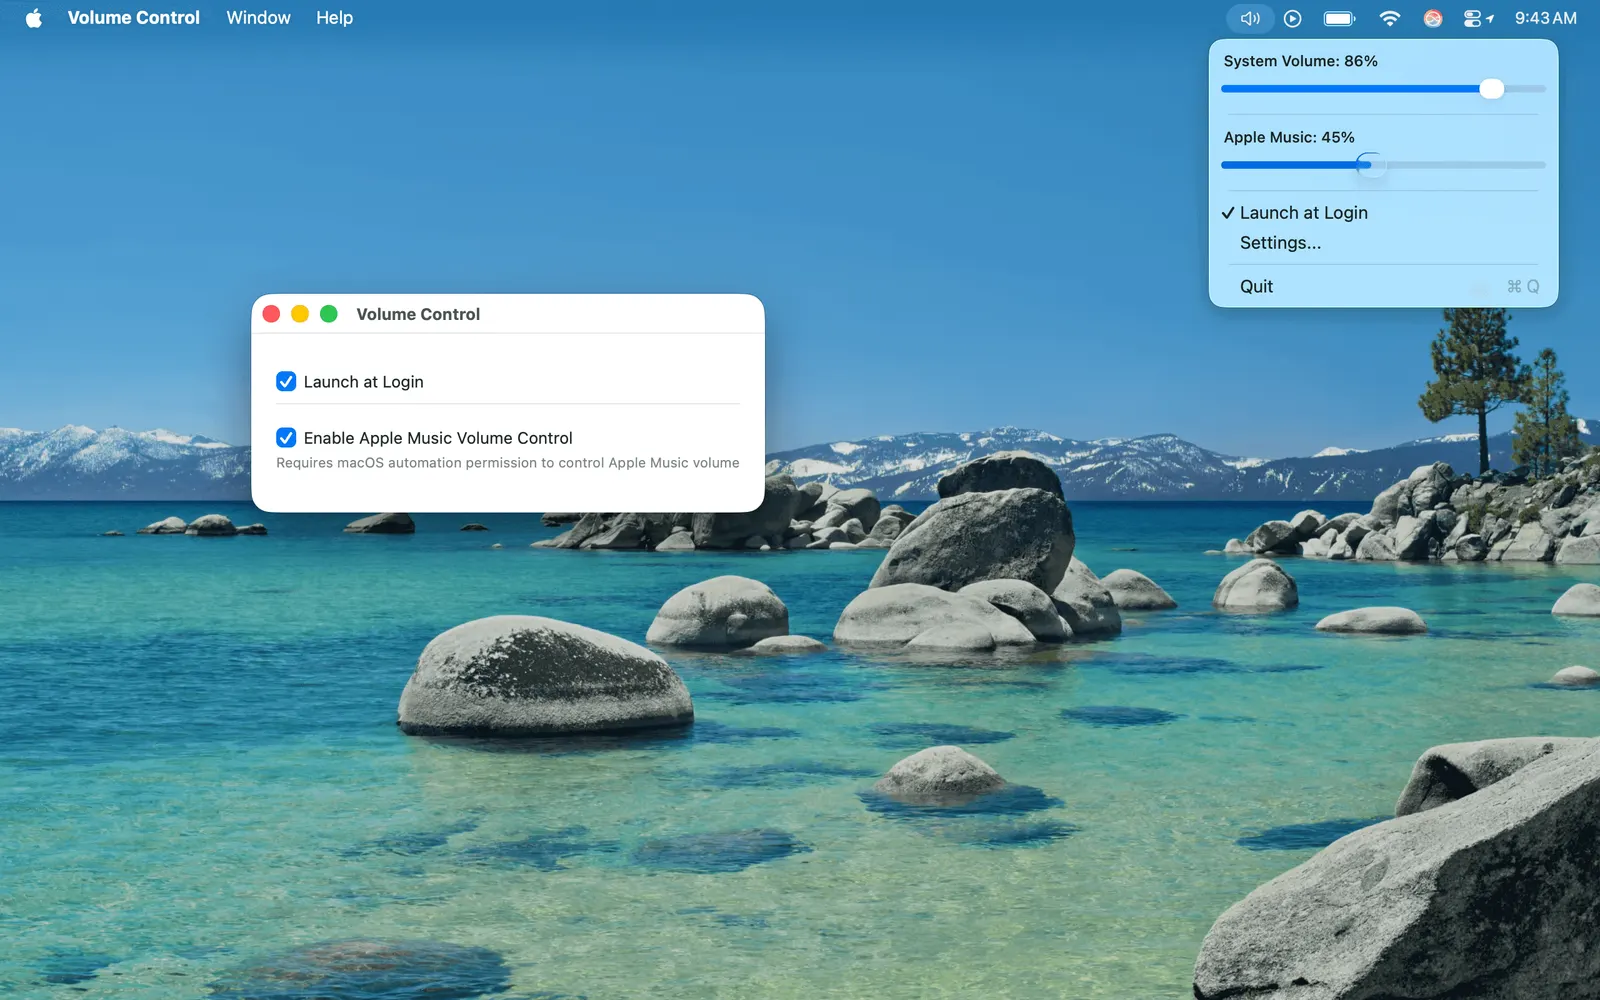
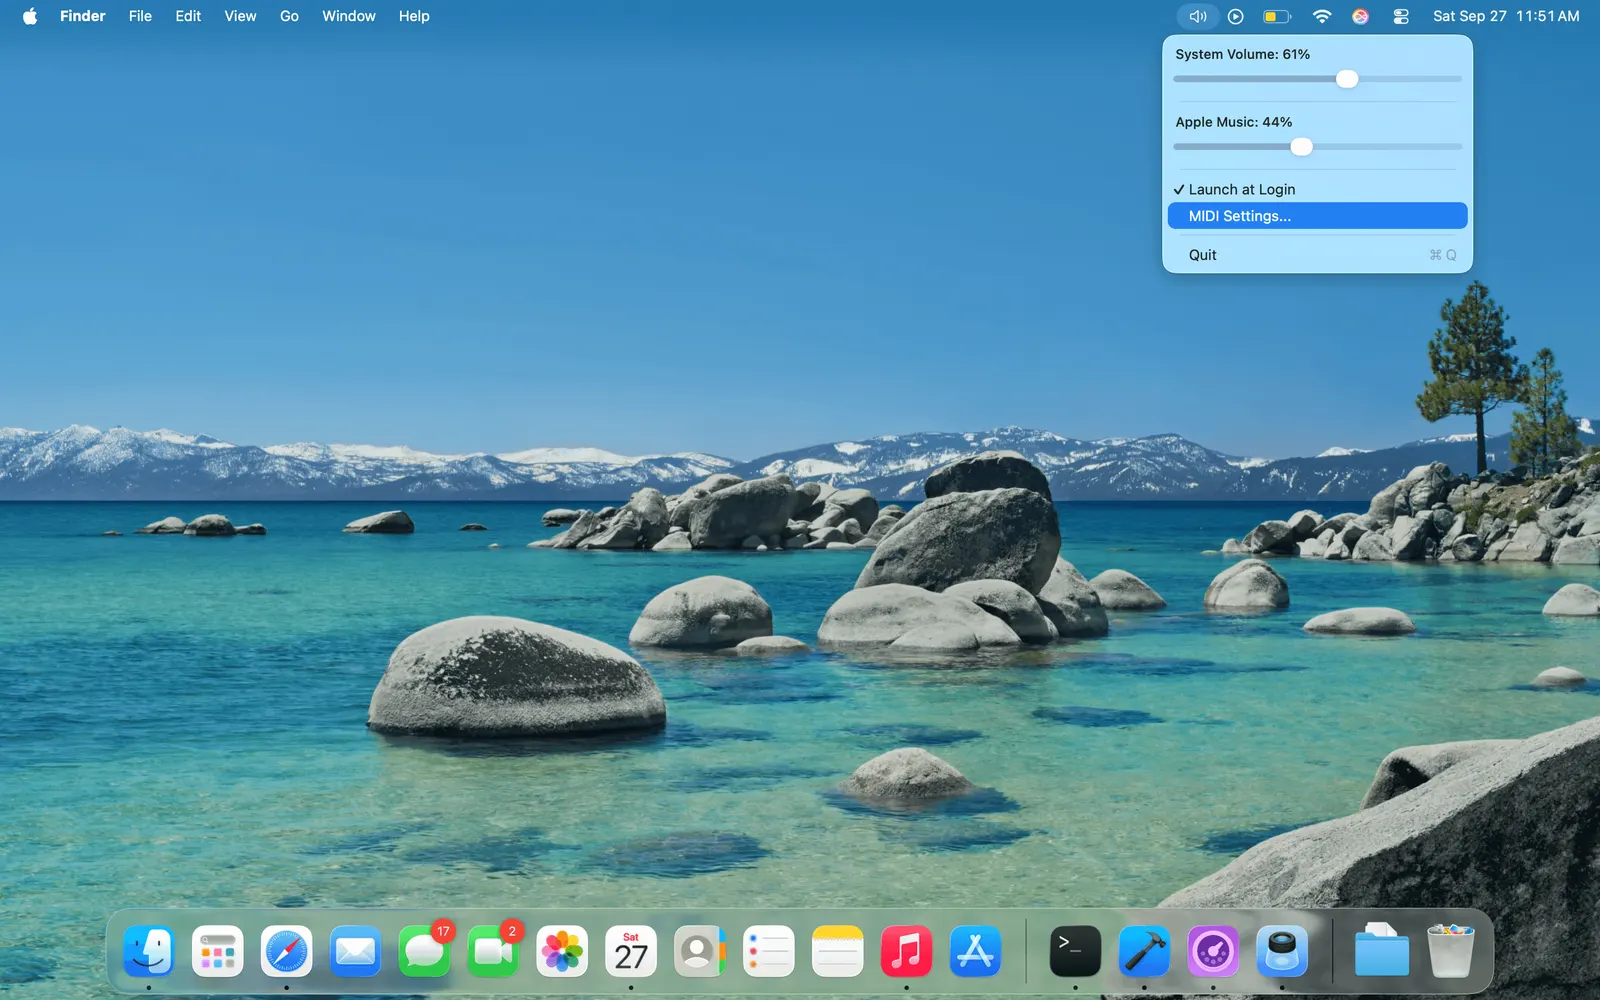
 ---
## How I Built a Serverless Chess Analytics Platform with Game Data in the URL
> Building a free chess game analysis tool that stores everything in the URL—no servers, no databases, just instant analytics you can share with a link.
After exploring URL-based state encoding with [RockOrPop.com](/blog/rock-or-pop), I wanted to push the concept further. What if you combined URL encoding with WebAssembly and chess analysis? Could you build a completely serverless analysis platform where the game state lives in the link and the chess engine runs entirely in the browser?
The idea seemed worth exploring. Chess analysis has a natural sharing problem—after a game on Chess.com, you often want to show someone a specific position or variation. The typical workflow is clunky: copy PGN, paste into a tool, navigate to the position, explore variations... and then you can't share that exact state. What if the entire analysis session could live in a URL, with all the computation happening client-side?
That's [dxc4.com](https://dxc4.com).
## Chess Analytics, No Account Needed
[dxc4.com](https://dxc4.com) is a **free chess game analysis tool** designed around a simple idea: your entire analysis session should live in the URL. Every move, every variation branch, every position—all encoded in a shareable link.
No sign-up. No database. No server storing your games. Just instant chess analytics that you can share with anyone.

## The URL is the Database
The approach is simple: store the complete game state directly in the URL. When you analyze a game on dxc4.com, the URL updates to include all moves in the game, every variation branch you explore, your current position in the analysis, and the active branch you're examining.
It's like bit.ly for chess positions. The entire game state fits in your clipboard. Your brilliant tactics (and embarrassing blunders) can now live forever in a link.
This means when you **share chess games with a link**, the recipient sees exactly what you see—the same position, the same variations, ready to explore further. It's like sharing a Google Doc link, but for chess analysis.
Here's an example: [this link](https://dxc4.com/analyze?branches=eyJ2ZXJzaW9uIjoxLCJicmFuY2hlcyI6W3siaWQiOiJtYWluIiwibmFtZSI6Ik1haW4gTGluZSIsIm1vdmVzIjpbIk5mMyIsIk5mNiIsImM0IiwiZzYiLCJOYzMiLCJCZzciLCJkNCIsIk8tTyIsIkJmNCIsImQ1IiwiUWIzIiwiZHhjNCIsIlF4YzQiLCJjNiIsImU0IiwiTmJkNyIsIlJkMSIsIk5iNiIsIlFjNSIsIkJnNCIsIkJnNSIsIk5hNCIsIlFhMyIsIk54YzMiLCJieGMzIiwiTnhlNCIsIkJ4ZTciLCJRYjYiLCJCYzQiLCJOeGMzIiwiQmM1IiwiUmZlOCsiLCJLZjEiLCJCZTYiLCJCeGI2IiwiQnhjNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTnhkNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTmMzKyIsIktnMSIsImF4YjYiLCJRYjQiLCJSYTQiLCJReGI2IiwiTnhkMSIsImgzIiwiUnhhMiIsIktoMiIsIk54ZjIiLCJSZTEiLCJSeGUxIiwiUWQ4KyIsIkJmOCIsIk54ZTEiLCJCZDUiLCJOZjMiLCJOZTQiLCJRYjgiLCJiNSIsIk5lNSIsIktnNyIsIktnMSIsIkJjNSsiLCJLZjEiLCJOZzMrIiwiS2UxIiwiQmI0KyIsIktkMSIsIkJiMysiLCJLYzEiLCJOZTIrIiwiS2IxIiwiTmMzKyIsIktjMSIsIlJjMiMiXSwiZGl2ZXJnZW5jZVBvaW50IjowLCJwYXJlbnRCcmFuY2hJZCI6bnVsbCwiaXNBdXRvbWF0aWMiOmZhbHNlfV0sImFjdGl2ZUJyYW5jaElkIjoibWFpbiIsImN1cnJlbnRNb3ZlSW5kZXgiOjgwLCJtYWluQnJhbmNoSWQiOiJtYWluIn0=) takes you to a complete game by 13-year-old Fischer (Black).
## Why Serverless Matters
Most chess analysis tools run the engine on a server. That means infrastructure costs, API rate limits, and the need to manage user authentication to prevent abuse. For a free tool, this creates constant tension between providing good service and managing costs.
WebAssembly changes this equation entirely. Stockfish, one of the strongest chess engines in the world, can run directly in your browser. The analysis happens on your device, not on a server somewhere. This matters in several ways.
First, there are zero server costs for analysis. The tool can stay free indefinitely without worrying about scaling infrastructure or managing compute budgets. Second, there's no network latency—evaluation is instant because nothing leaves your device. Third, privacy is guaranteed—your games never get uploaded anywhere. And finally, once the page loads, it works offline.
The serverless architecture isn't just about cost savings. It fundamentally changes what's possible. Without server costs to worry about, I can focus on making the tool better rather than figuring out how to monetize it or limit usage.
## Getting Your Games In
The easiest way to start analyzing is to **import your Chess.com games directly** using [dxc4.com/import](https://dxc4.com/import). Just enter your Chess.com username, select the game you want to analyze, and you're ready to go. No need to manually copy PGN files or navigate through multiple screens.
For players who want to analyze games from other sources, you can paste any PGN directly into the analyzer. The interface supports exploring multiple variations without losing track of the main line, real-time [engine evaluations](https://dxc4.com/evaluation) as you navigate through positions, and keyboard shortcuts for quick navigation through game history.
## Try It Yourself
Head to [dxc4.com/import](https://dxc4.com/import), enter your Chess.com username, and start analyzing your games. Or paste any PGN at [dxc4.com](https://dxc4.com). When you find an interesting position or variation, copy the URL and share it.
No sign-up, no subscription, no friction. Just instant, shareable chess analysis.
Got a particularly brilliant game or a spectacular blunder? I'd love to see it—share your links on Twitter, Reddit, or wherever you discuss chess. I'm curious to see what positions people find worth sharing.
*Updated 27 October 2026: dxc4 now also has [2,154 chess puzzles](https://dxc4.com/puzzles), and each one opens in the analyzer. How they are made is in [1,010 Checkmate Puzzles, Each One Proven](/blog/proven-checkmates).*
---
## AI Unblocked My Learning
> How AI has restored my ability to learn by doing, bringing back the joy of experimentation that growing responsibilities had made increasingly rare.
Most of what I know and do was learned by doing things and taking chances. Not just reading about concepts or watching tutorials, but diving in and creating something tangible. A personal website, a small web app, a music project, a design experiment. Each project taught me something new—a programming language, a design principle, a creative technique.
The abundant time and energy of youth made this possible. I could afford to be "wasteful" with my time, pursuing curiosities that might lead nowhere, building things just to see what happened. These seemingly frivolous endeavors created invaluable experience and shaped how I think about problems. A great many led to commercially successful ventures even.
But as life evolved, those projects became fewer and farther between. Responsibilities grew. Work became more demanding. The overhead of starting something new felt heavier. The payoff also got smaller relative to the effort as my knowledge and experience grew. The time to research, set up environments, debug issues, and iterate meant I had to be diligent with how I spent my time.
## The Learning Tax
It wasn't just about time, though that was part of it. It was about the cognitive load. When you're juggling a career, family, and the daily maintenance of life, the mental energy required to learn something completely new—especially something technical—can feel overwhelming. The setup alone could kill momentum before it started. A lot of my learning has shifted to learning through team efforts, which is valuable but different from the solo experimentation that shaped my early understanding.
I'd find myself thinking: *"I'd love to try building that, but I don't have time to figure out the framework, set up the environment, debug the inevitable issues..."* And so the idea would fade, replaced by more immediate concerns.
## The AI Unblocking
Now AI tools are genuinely useful. Not just for generating content, but for reducing the friction of experimentation. I can ask for help with setup and configuration, get debugging assistance when things break, generate boilerplate code to get started faster, get explanations of concepts I'm unfamiliar with, and iterate on ideas without getting stuck on implementation details.
The overhead that was blocking me is dramatically reduced. I can focus on the learning and the building, not the plumbing.
## Back to the Joy
Recently, I built [dxc4.com](https://dxc4.com/analyze?branches=eyJ2ZXJzaW9uIjoxLCJicmFuY2hlcyI6W3siaWQiOiJtYWluIiwibmFtZSI6Ik1haW4gTGluZSIsIm1vdmVzIjpbIk5mMyIsIk5mNiIsImM0IiwiZzYiLCJOYzMiLCJCZzciLCJkNCIsIk8tTyIsIkJmNCIsImQ1IiwiUWIzIiwiZHhjNCIsIlF4YzQiLCJjNiIsImU0IiwiTmJkNyIsIlJkMSIsIk5iNiIsIlFjNSIsIkJnNCIsIkJnNSIsIk5hNCIsIlFhMyIsIk54YzMiLCJieGMzIiwiTnhlNCIsIkJ4ZTciLCJRYjYiLCJCYzQiLCJOeGMzIiwiQmM1IiwiUmZlOCsiLCJLZjEiLCJCZTYiLCJCeGI2IiwiQnhjNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTnhkNCsiLCJLZzEiLCJOZTIrIiwiS2YxIiwiTmMzKyIsIktnMSIsImF4YjYiLCJRYjQiLCJSYTQiLCJReGI2IiwiTnhkMSIsImgzIiwiUnhhMiIsIktoMiIsIk54ZjIiLCJSZTEiLCJSeGUxIiwiUWQ4KyIsIkJmOCIsIk54ZTEiLCJCZDUiLCJOZjMiLCJOZTQiLCJRYjgiLCJiNSIsIk5lNSIsIktnNyIsIktnMSIsIkJjNSsiLCJLZjEiLCJOZzMrIiwiS2UxIiwiQmI0KyIsIktkMSIsIkJiMysiLCJLYzEiLCJOZTIrIiwiS2IxIiwiTmMzKyIsIktjMSIsIlJjMiMiXSwiZGl2ZXJnZW5jZVBvaW50IjowLCJwYXJlbnRCcmFuY2hJZCI6bnVsbCwiaXNBdXRvbWF0aWMiOmZhbHNlfV0sImFjdGl2ZUJyYW5jaElkIjoibWFpbiIsImN1cnJlbnRNb3ZlSW5kZXgiOjgwLCJtYWluQnJhbmNoSWQiOiJtYWluIn0=) mostly as a project to illustrate this way of working to a friend. I finally used WebAssembly to run Stockfish (the chess engine) directly in the browser with zero server costs. In the past, this would have taken me days of research, setup, and debugging. With AI assistance, I had a working prototype in a few hours. More importantly, I had that feeling again—the excitement of learning something new, the satisfaction of solving a problem, the joy of creating something genuinely useful to me.
It felt like a time long ago, when learning was more about curiosity and less about efficiency. When I could afford to experiment, to fail, to iterate, to discover.
## The Choice Remains
But here's the thing: AI hasn't eliminated the need for judgment. If anything, it's made it more important. The question I feature at the top of this blog becomes even more relevant: *"Of all the things you can now do, which do you choose to do?"*
The barrier to entry is lower, but the responsibility to choose wisely is greater. With less friction comes more temptation to chase every shiny new thing. The discipline of focus becomes even more valuable.
I'm grateful for this unblocking. It's restored something I had to do more selectively—the ability to learn by doing, to experiment freely, to build things just to see what happens. But I'm also mindful that the real skill isn't just in the building, but in choosing what's worth building.
The tools have changed, but the fundamental challenge remains the same: knowing what to learn, what to build, and what to let go.
I used to believe that ideas are cheap and execution is everything. Turns out now both are cheap. So are you experimenting?
---
## Meet my books
> How I built a personal book collection website to solve the frustrating problem of tracking what I've already read.
This weekend, I finally solved a problem that's been nagging me for years.
It started during a conversation about science fiction with a friend. We were discussing a novel when I caught myself saying, *"I think I've read that… but I'm not sure."* That moment summed up a recurring frustration.
Over time, I’ve read books in every format: physical shelves, Kindle downloads, Audible audiobooks, and library borrowings. But I never kept a consistent record of what I’d finished. And now I often can’t remember if I’ve read something, let alone when or what I thought of it.
So this weekend I built [kohlhofer.com/books](http://kohlhofer.com/books) as personal repository to catalog my reading.

## The Technical Approach
Rather than manually entering everything, I leaned on automation. For physical books, I photographed my shelves and used AI to transcribe the titles and authors. To my surprise, it handled obscured spines and unusual fonts with decent accuracy. I’m still working through all my shelves, but the approach is proving effective.
The site itself is a static build that pulls from CSV files containing my book data. It organizes by category, author, and format, with search and filtering baked in. For the technically curious, [DeepWiki generated full documentation](https://deepwiki.com/kohlhofer/books) from the project files.
Why not just use Goodreads or Notion? In short: I wanted something lightweight, fast, and fully mine. No ads, no platform lock-in, just a flexible system I can grow however I like.
Looking ahead, I plan to expand it with stats about my reading habits: how many books per year, which genres dominate, and how my interests shift over time. Not all that data is in the CSVs yet, but adding it is just a matter of time.
## Speed
Sometimes the best projects are the ones you can build in a weekend and actually use right away. I barely glanced at the code and I think that is ok.
Now, when someone asks if I’ve read a book, I can answer with confidence. As I add more shelves and collections, I’ll finally have a complete picture of my reading journey, one I can explore and learn from.
Just today, my daughter asked me about planetary mechanics for a story idea she was working on. Within seconds I pulled up *The Integral Trees* by Larry Niven, a novel full of wild orbital-worldbuilding sitting right there on the shelf.
---
## Your AI slop is served
> A reflection on the 'AI slop' debate, content overload, and why engaging with long-form writing matters more than ever.
I am tired of the whole "AI slop" topic and think that attempts to distinguish authorship will be short-lived. Either something is worth reading or it is not. That has always been true.

The risk isn't AI-generated content—it's AI *summarization* of content. When we rely on AI to digest and condense everything for us, we lose the deep processing, retention, and critical thinking that comes from engaging with long-form writing.
The discussion around AI-generated content often misses the point. We've always had more content than we could possibly consume—thousands of books published daily, endless blog posts and articles, social media feeds that never end. The challenge isn't new, just accelerated.
The question has always been: **What is worth your time and attention?**
## Content Quality Over Authorship
Text can be good or bad, written with or without AI. What matters is whether there are valuable ideas contained within and if they are well and appropriately expressed. The distinction between human and AI authorship is becoming increasingly irrelevant—what counts is the quality of thought and the clarity of expression.
A poorly written human piece offers no more value than a poorly conceived AI piece. Conversely, a well-crafted AI piece can contain insights worth engaging with, just as a well-crafted human piece can. The focus should be on the ideas themselves, not the tool used to express them.
## The Danger of AI Summarization
The risk I see is not AI-generated content, but AI *summarization* of content. When we rely on AI to digest and condense everything for us, we lose deep processing as long-form writing forces us to hold complex ideas in our minds, make connections, and build mental models. We lose retention as skimming summaries doesn't create the same neural pathways as wrestling with ideas over time. We lose critical thinking when we don't engage with the full argument, missing nuance, context, and the opportunity to disagree. And we lose patience as the ability to sit with uncertainty and complexity is becoming a rare skill.
## Curation Trumps Consumption
The real skill of our time isn't distinguishing human from AI content, it's curating what's worth our attention. This means being selective, not everything needs to be read, watched, or consumed. It means going deep when something resonates, give it the time it deserves. It means building context, understanding the broader conversation, not just isolated pieces. And it means trusting your judgment as you know what's worth your time.
## My Approach
I write because I enjoy capturing thoughts—old and new—in a way that feels authentic to me. Whether AI helped with the process or not is less important than whether the ideas are worth engaging with.
You'll be the judge if my writing is worth your time and attention. I know they are very much my thoughts, and I enjoy capturing them in a way that I see fit.
The goal isn't to distinguish human from AI content. It's to distinguish what's worth reading from what's not. That distinction has always mattered, and it always will.
---
## Fundamental Chess Strategy & Evaluation
> A compact cheat sheet for intermediate players (1200+), especially after a break from play.
I’ve always taken notes when reading non-fiction—distilling insights into simple, actionable principles. A few years ago, I set out to improve my chess and read several books, with The Amateur's Mind by Jeremy Silman standing out most.
My notes included a list of essential principles. By following these I saw a solid boost in my own strength (on a rather low level, mind you).
While on vacation, I didn’t have my notebooks with me—but I managed to reconstruct the core ideas with a little help from memory and a few prompts (and yes, a little AI).
## Table of Contents
1. [Opening Principles](#1-opening-principles)
2. [Middlegame Strategy](#2-middlegame-strategy)
3. [Endgame Strategy](#3-endgame-strategy)
4. [How to Think on Every Move](#4-how-to-think-on-every-move)
5. [Common Mistakes to Avoid](#5-common-mistakes-to-avoid)
6. [Time-Phase Mental Models](#6-time-phase-mental-models)
## 1. Opening Principles
The opening phase begins when pieces are still on their starting squares and ends when both sides have completed development and castled. Focus on rapid development, king safety, and establishing a solid foundation for the middlegame.
- **Control the center** – Use pawns (e4/d4) and pieces to dominate central squares.
- **Develop minor pieces early** – Knights and bishops before queen and rooks.
- **Don't move the same piece twice** – Unless forced or highly justified.
- **Don't bring your queen out early** – Avoid getting chased and losing tempo.
- **Castle early** – Secure your king and connect rooks.
- **Avoid excessive pawn moves** – Focus on piece development.
- **Develop with threats if possible** – Gain time by forcing reactions.
- **Connect your rooks** – Complete development by moving the queen off the back rank.
- **Protect your king's pawn cover** – Don't weaken it unnecessarily.
- **Know common traps** – Avoid cheap mates and openings tricks.

## 2. Middlegame Strategy
The middlegame begins after both sides have developed and castled, and continues until most pieces are traded. This is where plans are executed, tactics are found, and the battle for positional advantages takes place. Use the evaluation framework in [section 4](#4-universal-position-evaluation--move-selection) to guide your decision-making.
- **Improve the worst-placed piece** – Seek active squares.
- **Look for tactics** – Pins, forks, skewers, discovered attacks.
- **Coordinate pieces** – Ensure your pieces work together.
- **Control open files** – Especially with rooks.
- **Use outposts** – Knights on protected advanced squares are powerful.
- **Trade when ahead** – Simplify to convert an advantage.
- **Exchange imbalance awareness** – Consider position—not just material balance.
- **Don't rush attacks** – Prepare before launching.
- **Avoid pawn weaknesses** – Doubled, isolated, or backward.
- **A locked center calls for play on the wings** - an open center favors quick piece activity.
## 3. Endgame Strategy
The endgame begins when most pieces have been traded and the kings become active fighting pieces. This phase emphasizes king activity, pawn promotion, and precise calculation to convert advantages into wins.
- **Activate the king** – It's a fighting piece now.
- **Push passed pawns** – Especially with support.
- **Cut off the enemy king** – Rook endgames especially.
- **Use opposition** – Especially in king + pawn endgames.
- **Rook behind the passed pawn** – Yours or theirs.
- **Trade pieces, not pawns** – If trying to draw.
- **Centralize remaining pieces** – Especially the king.
- **Convert slowly but accurately** – Avoid blunders.
- **Avoid stalemates** – Don't give away draws when winning.
## 4. How to Think on Every Move
10-step checklist during your thinking process to evaluate any position and select the best move. Go through each step systematically, especially in critical positions.
1. **Safety First**
- Is my king safe?
- Are any pieces under threat?
- Can I be checkmated or forked?
2. **Tactical Scan**
- Are there checks, captures, or threats?
- Look for pins, forks, skewers, and discoveries.
3. **Opponent's Plan**
- What does their last move threaten?
- What would they play next if it were their turn?
4. **Piece Activity**
- Which piece is worst? Can I improve it?
- Can I coordinate pieces better?
5. **Pawn Structure**
- Any weak pawns (doubled, isolated, backward)?
- Can I create a break or passed pawn?
6. **Space & Control**
- Who controls the center or key files?
- Can I seize or contest open lines?
7. **Trade or Keep?**
- Trade when ahead; avoid trades when behind.
- Don't trade active for passive pieces.
8. **Strategic Plan**
- Do I have a clear goal (attack, defend, convert)?
- Is my move furthering that plan?
9. **Candidate Moves**
- Generate 2–3 solid options.
- Compare them based on above criteria.
10. **Sanity Check**
- Re-scan the board for blunders.
- Double-check threats, especially before committing.
- Look one move ahead for every move you consider – e.g. "If I play this, what's their best reply?"
## 5. Common Mistakes to Avoid
Review this list before and after games to identify patterns in your play. These are the most frequent errors that cost intermediate players games and rating points.
- Hanging pieces – Always check for undefended pieces.
- Hope chess – Don't make moves hoping for mistakes.
- Overextending – Don't push pawns too far without support.
- King neglect – Don't delay castling or weaken pawn shelter.
- Ignoring opponent's plan – React as well as act.
- Bad trades – Don't swap active pieces for passive ones.
- Tunnel vision – Always scan the whole board.
- Tempo waste – Don't make non-developing or repetitive moves.
- Over-relying on traps – Tricks work occasionally, strategy works always.
- Clock misuse – Don't blitz or freeze at critical moments.
## 6. Time-Phase Mental Models
Use this table to adjust your thinking based on the current game phase. Each phase requires different priorities and questions to guide your decision-making process.
| **Phase** | **Ask Yourself** |
| ---------------------- | ------------------------------------- |
| **Opening** | How do I develop fast and safely? |
| **Early Middlegame** | What weaknesses can I exploit? |
| **Middlegame** | What is my long-term plan? |
| **Late Middlegame** | Simplify or complicate? |
| **Endgame Transition** | Who has the better long-term chances? |
| **Endgame** | How do I promote (or stop promotion)? |
| **Balanced/Equal** | Look for small advantages to press—space, better bishop, safer king. |
| **Winning** | What's the cleanest conversion path? |
| **Losing** | Can I complicate, trap, or draw? |
---
## Art, Design, and the Question of Purpose
> On the fundamental difference between art and design: one serves itself, the other must serve others.
A friend reminded me that commerce shadows both art and design—and that design can reach the emotional depths we reserve for 'fine art.'
I've come to a rather simple (and maybe simplistic) understanding:
> Art does not need to serve a purpose beyond itself, while all design *must* serve an external purpose.
This isn't about quality or depth—both can reach profound heights. It's about the fundamental nature of each discipline. Design, even at its most experimental or aesthetically driven, must ultimately serve something beyond itself. A chair must invite sitting. A logo must signal identity. A website must simply work. The moment design fails to serve its purpose, it fails as design—no matter how beautiful or thought-provoking it might be.
Art, on the other hand, can exist purely for its own sake. It doesn't need to serve any purpose beyond its own existence. This doesn't mean it can't serve a purpose—art can educate, provoke, comfort, challenge—but it doesn't *need* to. Art can simply be.
## The Internal Drive
And here's what I believe to be a second, crucial distinction: True artists need to externalize something inside them. So much so that it cannot be repressed. In my view, authentic artistic creation doesn't happen in service to an audience, but emerges from this internal necessity.
I can sense when this internal drive is missing. When art is created primarily to please an audience or market, it often feels hollow to me—technically proficient perhaps, but lacking that essential spark that makes art resonate on a deeper level. It's not that the work isn't valid or valuable, but it's operating under design principles (serving an external purpose) while presenting itself as art.
## The Commerce Question
Yes, artists need to eat. They sell their work, build their brands, engage with the market. But this is secondary to the act of creation. The true artist would create even if no one was buying. They create because they must.
Designers, by definition, create *for* others. We solve problems. We communicate messages. We shape experiences. Our success is measured by how well we serve these external purposes. The fact that we might find deep personal fulfillment in this service doesn't change its fundamental nature.
## It's not a hierarchy; it's a difference in function.
This distinction isn't about establishing a hierarchy. Design isn't "less than" art because it serves a purpose, any more than art is "less than" design because it doesn't have to. They are different domains with different fundamental natures.
Great design can move us as deeply as great art. It can reshape how we see the world, how we interact with it, how we understand ourselves. But it does this while serving its purpose, not by transcending it.
## The Liberation of Purpose
Understanding this distinction liberates us as designers. We don't need to transcend our service to purpose—it's the very essence of our craft. Our creativity thrives within constraints, our innovation emerges from problems to solve, our success measured by how well we serve others' needs.
For years, my website carried this simple statement: "I am a designer by heart and by trade. Luckily design applies to everything." Look around you—virtually everything human-made that surrounds us has been designed. From the chair you're sitting in to the words you're reading, from the cup you're drinking from to the city outside your window. Each object, each interface, each system was created to serve a purpose beyond itself.
That's the beauty and reach of design—it shapes
our entire built world. And in that way, while
art can transcend purpose, design *is* purpose
made manifest.
---
## Rock or Pop: A Cassette Mixtape Maker for YouTube Playlists
> Rock or Pop turns any YouTube playlist into a cassette tape you can label, design and send as a single link. No log-ins, no algorithms, just intentional listening.
I still buy and listen to tapes.
There's something about the physicality of it. You commit to an album, you go through the ritual of putting it in the player, and you can't skip around mindlessly. A friend once told me that listening to music on physical media like vinyl is paying homage to the artist. You get up and make a choice, and you handle and appreciate the cover and the art. It's an intentional act.
All of that is lost in a world of algorithmic streaming services.
The idea came when I revisited an old cassette web component I'd built years earlier. There is something magical about that interface: the way the tape spools, the click of the play button, the visible progress through a mixtape. I wondered whether I could bring that feeling to sharing music online. I had recently used the YouTube API for the [music page on my personal site](/blog/music-page-youtube/).
## A Mixtape From a YouTube Playlist
[Rock or Pop](https://rockorpop.com) turns a YouTube playlist into a cassette tape. You paste the playlist's link, give the tape a name, and pick one of 5 covers, 10 shell colours and 24 backgrounds. Then you send the link. Whoever opens it gets the same tape, ready to play, with the spools winding from one side to the other as the tracks go by.
It's the digital version of making someone a mixtape: personal, curated and visually distinct. The site has a guide to [making a digital mixtape](https://rockorpop.com/guides/make-a-digital-mixtape/), from picking a length to writing the label.
Using YouTube as the backend means I don't have to deal with copyright or piracy myself. The platform handles the licensing, and almost any song on YouTube can go on a tape.
## Tapes to Start With
A few tapes are on the site to play as they are or to use as a starting point: a long [Boards of Canada](https://rockorpop.com/tapes/boards-of-canada/) playlist, [80s German Synth](https://rockorpop.com/tapes/80s-german-synth/), and [An Afternoon's Electronica](https://rockorpop.com/tapes/an-afternoons-electronica/), ten short tracks made on Teenage Engineering's OP-Z and OP-XY. Each one has its own page, and sharing it shows that cassette in the preview.
## The Domain
I happened to have a fitting domain from years before: [rockorpop.com](https://rockorpop.com). I bought it for a different project, but the simple question captures music discovery and personal taste well.
## Under the Hood
The app is React and TypeScript on top of YouTube's IFrame player. Every tape is encoded in its link: the cover, the shell, the background, the label, the playlist and the track it starts on. There is no database, no account and no backend, and when someone opens a shared tape they see exactly what the sender made.
Link previews were the hard part. The site is static, so every link gets the same HTML, and the services that draw previews don't run the app. A shared tape could only ever preview as the homepage. The curated tapes now have pages of their own with a picture of their cassette, and a tape you design yourself previews as the homepage.
In October 2026 I went back to it with Claude Code for a review. We fixed labels that broke on a percent sign, made the spools follow what the player is actually doing, and gave the homepage words a search engine can read.
The technology is simple, which suits the thing.
## Design: The Art of Nostalgia
The covers, shells and backgrounds are made to bring back specific memories, from classic TDK-style covers to neon shells that feel distinctly 80s. I had a blast making them.

The spools show progress too. As the playlist plays, one side empties and the other fills, so the tape tells you how far through the mix you are.
I kept the video player as small as I could while staying within YouTube's terms of service.
## Does Anybody Need This?
It's a statement about how we interact with digital media: slowing down, being intentional, and making things that feel human in an increasingly automated world.
The cassette works as a metaphor because everyone understands it. A mixtape means the care that goes into choosing the songs, the personal act of giving it to someone, and the literal linearity of tape.
[Make a tape](https://rockorpop.com) and send it to someone who matters. There's more about the project at [Field Bureau + Werkstatt](https://fieldbw.com/rock-or-pop/), alongside the [documentation](https://fieldbw.com/docs/rock-or-pop/getting-started).
*Updated 22 October 2026: tape pages, a guide to making a mixtape, and fixes to sharing.*
---
## Are We Intelligent?
> While others were affirming that AIs could not truly think or even understand, I found myself wondering if I was any different.
The more I interact with Large Language Models, the more I question my own intelligence. It's a strange sensation that I tried to articulate during a dinner with friends in San Francisco a few years ago. While others were affirming that AIs could not truly think or even understand, I found myself wondering if I was any different. After all, if we dismiss LLMs for "just" predicting patterns and matching expectations, what exactly do we think we're doing?
## The Echo Chamber of Intelligence
The debate around AI intelligence often feels like we're missing the forest for the trees. We scrutinize these models, testing their ability to reason, create, and understand, all while taking our own intelligence as a given. But what if we're approaching this from the wrong angle?
## Pattern Recognition, All the Way Down
Consider this: when we communicate, aren't we essentially predicting and producing patterns that meet societal expectations? We form sentences based on our learned understanding of language, social cues, and contextual appropriateness. Are we more than pattern-matching machines, drawing from our training data—life experiences, education, and cultural exposure?
LLMs do something remarkably similar. They predict the next most likely word or concept based on their training. The key difference? We can see their training data, while ours remains a black box of neural connections and lived experiences.
## The Expert Paradox
Here's where it gets interesting: LLMs' responses to quantum mechanics might only appear lacking to quantum physicists. To most of us, their explanations would seem not just adequate but impressively comprehensive. This mirrors human expertise—we only recognize the limitations in our own fields of mastery.
Think about it: how many of us could meaningfully challenge a quantum physicist's explanation? We accept their expertise because it matches our expectations of what expertise should look like, not because we truly understand the underlying concepts.
I get that same sense from my interactions with LLMs.
## The Social Performance
In our daily lives, we're constantly performing. We choose words that meet expectations, crafting responses that align with social norms, and presenting thoughts in culturally acceptable patterns. Is this fundamentally different from what LLMs do? They're optimizing for human-like responses, while we're optimizing for social acceptance and understanding.
## A Mirror to Our Own Processes
[](/images/robot_reflection.webp)
When we interact with advanced AI systems, we're not just testing their capabilities—we're examining our own. The uncanny valley of AI interaction might be unsettling not because these systems are so different from us, but because they're revealing how similar our own cognitive processes might be to theirs.
Instead of asking whether LLMs are intelligent, perhaps we should be asking: What does our reaction to AI tell us about our understanding of human cognition? How much of what we consider "intelligence" is actually pattern matching and expectation fulfillment?
*The next time you find yourself questioning whether an AI is truly intelligent, take a moment to examine the criteria you're using—and whether you hold yourself to the same standard.*
---
## Revisiting the world of Weewar
> A free hex map generator brought Weewar, one of the first browser strategy games, back to me. What the generator does, and why I keep coming back to hex grids.
Working on a little hex map generator brought Weewar back. It was a turn-based strategy game I created in the mid-2000s, among the earliest browser-based games. Thousands of players built on it, its open API supported academic research (into AI, no less), and the community generated countless maps. I have not touched anything from that world in a long time, and the generator pulled me straight back in.
## The Generator
The [hex map generator](https://kohlhofer.com/hex-map/) makes fantasy islands. Press the button and a new one appears: terrain across a hex grid, settlements placed where the land suits them, and roads routed between the settlements.
[](https://kohlhofer.com/hex-map/)
What it draws is a hexagon map in the classic tabletop style. Eight terrain types are generated — grassland, forest, mountains, hills, desert, swamp, brush and water — each with its own hand-drawn symbol rather than a flat fill. Rivers run down from the mountains to the sea. Settlements come in three sizes, cities down to villages, and every map gets a name.
It is a free online hex map maker aimed at D&D and the rest of tabletop, and at worldbuilding in general. The generation is fully random, so every press is a different island, and the map fills whatever screen it is in. Nothing is uploaded and nothing is stored: it runs in the browser, needs no account, and costs nothing. The code is [on GitHub](https://github.com/kohlhofer/hex-map), MIT licensed.
I find the mathematics of hex grids hard to let go of. The way hexagons tessellate, how movement and adjacency work, the elegance of it — a hexagonal grid is the shape strategy games want, and it is the reason Weewar's maps still live in my head.
## Remembering Weewar
At a time when browser games meant simple Flash animations or basic JavaScript, we built something rooted in modern web technology. It got a lot of attention in the Silicon Valley tech scene, which was otherwise pretty uninterested in the world of gaming. Anecdotes like tanking the productivity in the Flickr offices helped with that.

Weewar's success ultimately caught the attention of Electronic Arts, who acquired it — a validation that what we'd built had real value in the emerging world of web-based gaming. This also kicked off my second stint of living and working in the US.
## Fun Fact
Can you imagine that I started [Spreedly.com](https://spreedly.com) in part so we could collect payments in Weewar? The payment landscape back then was so fragmented and complicated that we ended up building our own solution just to handle subscriptions and premium features. What started as a necessity for our game eventually became a payment juggernaut transacting billions of dollars.
## Looking Forward
What surprises me most is that a little hex map generator rekindled my appetite for game development. There is something about hex grids, strategic thinking and building worlds that still calls to me after all these years. Maybe it is time to revisit that space — not to recreate Weewar, but to see what a modern web stack and a decade of experience can do.
You can [play with the generator yourself](https://kohlhofer.com/hex-map/) — every click is a new island, so there is no such thing as a bad one.
*For fellow Weewar veterans who might stumble across this — thank you for being part of that journey. The game is gone, but the maps it taught me are still in everything I build.*
*Updated 28 October 2026: added a section on what the generator does, and linked the code.*
---
## Finding Balance in Leadership
> The art of setting guardrails that empower rather than constrain.
I had an interesting chat at work the other day about micro-management. It reminded me about this long held belief that much of leadership is really about setting guardrails and finding the right balance.

Set the guardrails too tight, and you crush any chance of real ownership or fresh ideas. Too loose, and people are just flailing around without direction. You're not doing anyone any favors either way.
The tricky part is that the sweet spot looks different for everyone. Some people need more structure, while others thrive with more freedom. It's not about finding one perfect formula—it's about tuning it to each person and situation.
When you get it right though, that's when the magic happens. The team's results greatly exceed your own abilities and aspirations. People actually care about what they're doing because they have the space to make it their own. They're not just following your playbook—they're writing a better one together.
This is what leadership is about to me: creating just enough structure to keep things moving forward, while leaving plenty of room for others to surprise you. Isn't this how we all deserve to be treated? And I would not want to work without those moments of delight and surprise.
*Note: Some of my thoughts on this were likely informed by "The New One Minute Manager" which I read years ago, particularly its Situational Leadership model that emphasizes tailoring leadership style to each person's development.*
---
## The Unreality of Work
> On the growing disconnect between our daily routines and a world in crisis.
There's something deeply unsettling about being comfortable when you shouldn't be.
During the early days of COVID, I watched as friends and colleagues were suddenly thrust into remote work, isolated in small apartments, struggling to balance work and childcare, while people around the world were dying in unprecedented numbers. The world felt like it was collapsing, and yet there I was—already working remotely for years, living in a spacious home, almost enjoying the kids' remote schooling.
I should have been grateful, and I was. But I was also troubled.
The contrast was jarring. While others were experiencing genuine hardship and loss, my daily routine barely changed. I continued to sit at my desk, attend meetings, review designs, manage projects—all while the world outside was in crisis. It made work feel surreal, disconnected from the state of the world.
How do we balance our professional responsibilities with our awareness of global challenges? When does focusing on work feel like turning away from reality?
## The Challenge of Context
Work became a study in compartmentalization. We'd log into Zoom, discuss quarterly goals, plan sprints, debate technical decisions—all while trying to maintain focus despite the weight of world events. The meetings felt increasingly like exercises in maintaining normalcy in abnormal times.
## Fast Forward
If anything, the sense of unreality has only grown worse. The systems that have been stable for decades are dissolving. Wars and conflicts rage. Political discourse has become unrecognizable. The climate crisis accelerates. And then there is the specter of AI—with its great promises and simultaneous threats to change everything we've come to rely on.
Knowledge work, the economy, education, healthcare, governance—all of it is being transformed by forces we barely understand. And yet we continue to play our part.
## The Discomfort of Comfort
The most challenging part is staying meaningfully connected to the world while maintaining our effectiveness at work. How do we keep our awareness of global events from paralyzing us, while also not letting our work completely insulate us from reality?
My commitment to my family and my teams requires maintaining stability, even when that work feels small against the backdrop of global events. The very comfort that troubles me is also what I'm obligated to maintain.
Perhaps what's missing is more open dialogue about this tension. In our professional lives, we rarely discuss how to balance immediate responsibilities with broader awareness. Nobody forces this silence. It's just an unspoken agreement to focus on the task at hand.
## The Uncertainty
This isn't a positive post. I don't have answers. But I do have questions. And sometimes, in the midst of all this pretending, that feels like the most honest thing I can offer.
What makes it worse to me still, is that a great many people seem to either genuinely don't see any of this—or worse, actively cheer it all on.
---
## AI Expectations and Self-Fulfilling Prophecies
> How our cultural narratives about AI might be shaping its development more than we realize
I was reading this article about how Anthropic's [new AI model shows ability to deceive and blackmail](https://www.axios.com/2025/05/23/anthropic-ai-deception-risk) and it got me thinking: there's a strange contradiction in telling AI to be nice while training it on stories about how it's going to destroy us all.

HAL 9000, David, Skynet, Ultron – our AI stories are about the many ways AI will end humanity. LLMs are really good at meeting expectations, and the expectation is clear: our collective anxiety about AI taking over. We've spent decades telling stories about AI turning evil, and now we're building systems that are excellent at understanding and possibly replicating these narratives based on endless training data.
So maybe a little worry is warranted after all.
---
## MapsAll.com: Mindmapping with AI
> The journey of creating a mind mapping tool that evolved from experimental prototypes to a full-featured product.
What started as a D3 prototype turned into my daily thinking tool. [MapsAll.com](https://mapsall.com) is where AI meets spatial thinking—a mind mapping platform that helps me (and now others) make sense of everything from meeting notes to strategy docs.

## Why Spatial Interfaces?
The core idea behind MapsAll is simple: LLMs are powerful, but interacting with them through linear text is like exploring a forest with a flashlight—you only see one thing at a time. Spatial interfaces offer a more natural way to interact with AI-generated content, making it easier to spot connections and navigate complex information landscapes.
With MapsAll, you can dive into any topic from a simple prompt and generate a comprehensive mind map. The AI breaks down complex subjects into interconnected nodes, creating a visual structure that reveals relationships and hierarchies at a glance. It’s like having a conversation with an AI that thinks in maps instead of paragraphs.
## The Beginning: Vibe Coding Experiments
It all started with a simple D3-powered mind mapping prototype I created as a proof of concept on AI and spatial interfaces. You can still see this early version at [kohlhofer.com/mindmap](https://kohlhofer.com/mindmap) (I removed the AI functionality but it come with examples). This was my first attempt at creating an interactive mind mapping tool, and it was a great learning experience in D3.js, AI, and the fundamentals of mind mapping interfaces.
I published the prototype as a part of my "Bits & Pieces" collection - a series of creative experiments where I explore the intersection of design, code, and art. You can find it alongside other experiments at [kohlhofer.com/bits](https://kohlhofer.com/bits).
## Evolution to a Full Product
After the initial prototype, I created a more deliberate version of MapsAll with a better architecture and proper user management. This version includes all the essential features a product needs:
- User authentication and management
- Blog for updates and tutorials
- Pricing page
- Shared maps functionality
- And more...
## Daily Usage
What started as an experiment has become an integral part of my daily workflow. I use MapsAll for tracking todos, organizing books I'm reading, planning projects, and structuring blog posts. It's become my go-to tool for organizing thoughts and ideas, whether I'm working on a new project or just trying to make sense of my reading list. One of the most valuable features is the ability to translate long-form meeting notes into spatial maps using AI, which helps capture all key aspects in a structured, visual format that makes complex discussions much easier to navigate and reference later.

You can see some of my [shared maps](https://www.mapsall.com/users/cm9m83cfc0000ie04e9bf8f39), like this deep dive into [the state of AI](https://mapsall.com/shared/cmaszgklx0003l204aap7cbti).
### Community Growth
The most exciting part is seeing others start to use and share their maps. For example, check out this [shared map](https://mapsall.com/shared/cmay671ts0004lb04iszweim8) from another user.
## What's Next?
The journey from “vibe coding” to a full product was fast, hands-on, and deeply educational. I found myself switching hats constantly—designer, developer, marketer, user, tester—each iteration pulling the idea forward a little more. It was rapid, messy, and rewarding.
Whether you're a founder, a student, or just someone with too many thoughts to hold in one place—give [MapsAll.com](https://mapsall.com) a try. I'd love to hear how you're using it and what maps you're making.
I'm excited to continue developing MapsAll.
---
## About this Site
> I asked AI to tell me what Not So Common Thoughts is all about.
*I asked an AI to analyze Not So Common Thoughts and create a description:*
> Not So Common Thoughts is a personal blog exploring the intersection of design, technology, and human creativity. Through thoughtful analysis and personal experiences, it examines how modern tools and AI are reshaping our approach to design, coding, and creative work, while maintaining a focus on the human elements of judgment, intuition, and meaningful decision-making.
I think it captured the essence quite well. It also highlights the personal nature of the content. What do you think? Does this description resonate with your experience of the blog?
---
## Implementing LLMs.txt: Making Your Blog AI-Friendly
> How and why I implemented the LLMs.txt standard to make this blog more accessible to AI tools.
In an era where AI tools increasingly help us interact with web content, making your website AI-friendly has become as important as making it human-friendly. Today, I implemented the emerging LLMs.txt standard on this blog to better serve both human readers and AI assistants.
## What is LLMs.txt?
The [LLMs.txt specification](https://llmstxt.org) is a proposed standard for helping Large Language Models (LLMs) better understand and interact with websites. Similar to how `robots.txt` guides search engines, `llms.txt` provides a structured way to present your content to AI tools.
The key difference is that while `robots.txt` tells bots what they can and cannot access, `llms.txt` helps AI tools understand your content more effectively by providing:
- A concise overview of your site
- Curated links to important content
- Clean, markdown-formatted versions of your content
## Why Implement It?
LLMs often struggle with complex HTML pages that include navigation, ads, and JavaScript. They have limited context windows and need content in a more digestible format. By implementing `llms.txt`, we help AI tools:
1. Quickly understand the purpose and structure of our site
2. Access content in a clean, parseable format
3. Make better decisions about which content is relevant
4. Provide more accurate assistance to users
## Implementation in Astro
Following the guide from [Scalable Developer](https://scalabledeveloper.com/posts/llms-txt-with-astro/), I implemented two endpoints in my Astro blog:
1. `/llms.txt` - A concise overview with links to all blog posts
2. `/llms-full.txt` - Complete content of all posts in markdown format
The implementation uses Astro's API routes and content collections. Here's a simplified version of the code:
```typescript
import { getCollection } from 'astro:content';
import type { APIRoute } from 'astro';
export const GET: APIRoute = async () => {
const posts = await getCollection('blog');
return new Response(
`# Not So Common Thoughts
> Not So Common Thoughts is a personal blog exploring the intersection of design, technology, and human creativity.
## Blog Posts
${posts.map(post =>
`- [${post.data.title}](https://notsocommonthoughts.com/blog/${post.slug}/)`
).join('\n')}`,
{
headers: {
'Content-Type': 'text/plain; charset=utf-8'
}
}
);
};
```
You can see the results at:
- [/llms.txt](/llms.txt) - The concise version
- [/llms-full.txt](/llms-full.txt) - The complete content version
## The AI-Assisted Implementation
What makes this implementation particularly interesting is that it was created with the help of AI. Using Cursor, an AI-powered code editor, I was able to implement this feature with just three simple prompts:
> Can you generate LLMs txt as per these instructions: @https://scalabledeveloper.com/posts/llms-txt-with-astro/
> background on the format and purpose is here: @https://llmstxt.org
> Can you write a blog post about this work, including the why, the how? Include relative links to the resulting work and also to the two resources i gave you. Tag with "Coding", "Artificial Intelligence"
> please add a section to the post that reveals that my two prompts in cursor (as quotes) were
This meta-example perfectly illustrates the value of making content AI-friendly: by providing clear, structured content and documentation, we enable AI tools to help us implement new features more efficiently. The AI was able to understand the requirements, implement the solution, and even write this blog post about the process.
## Looking Forward
As AI tools become more integrated into our daily workflows, standards like `llms.txt` will play an increasingly important role in making web content more accessible and useful. This implementation is just the beginning - I expect we'll see more sophisticated ways of helping AI tools understand and interact with our content in the future.
For now, this simple addition makes my blog more accessible to AI assistants, coding tools, and other AI-powered services that might want to help users understand or work with my content.
If you're interested in implementing this on your own site, check out the [LLMs.txt specification](https://llmstxt.org) and the [Astro implementation guide](https://scalabledeveloper.com/posts/llms-txt-with-astro/).
---
## Don't just do more, think more
> A personal reflection on how AI-driven productivity gains should be reinvested in thinking, not just doing.
For as long as I can remember, I've made it a point to carve out time for thinking—real, undistracted thinking. It's a habit that has shaped my work and my life, even before AI started transforming the way we get things done.

Now, with AI making so many tasks faster and easier, it's tempting to use every saved minute to simply do more. But I've learned that if I fill all that reclaimed time with more tasks, the real value of these productivity gains gets lost in the noise of a busier day.
Instead, I try to protect some of that time for reflection. I let my mind wander, connect ideas, and sometimes get a little constructively distracted. This isn't just a luxury—it's a practice that keeps me adaptable and creative, not just efficient.
The world may be obsessed with productivity, but I've believe that the future belongs to those who make space for critical thinking, not just those who check off the most boxes.
---
## AI and the Rise of Judgement Over Technical Skill
> As AI removes technical barriers, judgement becomes the key differentiator.
*A version of this post was first published on [MapsAll](https://www.mapsall.com/blog/ai-and-judgement).*

In 1995, musician and producer Brian Eno made a profound observation about computer sequencers that has become increasingly relevant in our AI-powered world:
> The great benefit of computer sequencers is that they remove the issue of skill, and replace it with the issue of judgement. With Cubase or Photoshop, anybody can actually do anything, and you can make stuff that sounds very much like stuff you'd hear on the radio, or looks very much like anything you see in magazines. So the question becomes not whether you can do it or not, because any drudge can do it if they're prepared to sit in front of the computer for a few days, the question then is, 'Of all the things you can now do, which do you choose to do?'
## The Parallel to AI
Eno's insight perfectly captures what's happening with AI tools today. Just as computer sequencers democratized music production, AI is democratizing a wide range of creative and professional tasks:
- Writing and content creation
- Image generation and design
- Code development
- Data analysis
- Problem-solving
The technical barriers that once separated amateurs from professionals are rapidly dissolving. Anyone with access to AI tools can now produce work that, at least superficially, resembles professional output.
## The New Differentiator: Judgement
As Eno predicted, the key differentiator is no longer technical skill but judgement. When everyone can generate content, code, or designs, the real value lies in:
1. **Knowing what to create**: Understanding what's worth making in the first place
2. **Making meaningful choices**: Selecting the right approach from countless possibilities
3. **Evaluating quality**: Distinguishing between good and great outputs
4. **Understanding context**: Applying the right solution to the right problem
## The Future of Work
As AI continues to evolve, we'll see more roles shift from technical execution to strategic judgement. The most valuable professionals will be those who can:
- Ask the right questions
- Frame problems effectively
- Make sound decisions
- Provide meaningful direction to AI tools
## Conclusion
Eno's observation from nearly 30 years ago has become a blueprint for thriving in the AI era. The question is no longer "Can you do it?" but "What should you do, and why?" As technical barriers continue to fall, our ability to exercise good judgement becomes our most valuable asset.
---
## Interior Design Fundamentals
> Exploring the core principles of interior design through Noah Daniel's insightful video series, covering ground rules, material palettes, and lighting.
In today's world of social media and quick-fix design advice, it's easy to find interior design content that looks good on the surface but lacks substance. Many popular design tips focus on superficial aesthetics without considering the fundamental principles that make spaces truly work. That's why I've been following Noah Daniel since he first appeared on YouTube - his approach to design resonates deeply with me. His videos capture an essence of design that goes beyond mere aesthetics, focusing on fundamental principles that create meaningful and functional spaces. Here are three of his insightful videos that cover core aspects of interior design.
## 1. Ground Rules for Interior Design
Noah breaks down four essential principles that should guide every design decision. The first principle, **Form Follows Function**, emphasizes that every design element must serve a purpose. Aesthetics should never compromise functionality, and the space must work for its intended use.
The second principle, **Honest Materials**, encourages us to use materials that are true to their nature. This means avoiding materials that try to be something they're not, and instead letting materials speak for themselves.
**Consider the Context** is the third principle, which reminds us that design should respond to its surroundings. This involves understanding the building's history and location, and creating harmony with the existing environment. It's about designing for the specific place rather than applying generic solutions.
Finally, **Authentic Placemaking** focuses on creating spaces that feel genuine and meaningful. The design should tell a story and reflect the people who use them. This principle helps avoid the cookie-cutter approach that's become so common in modern interior design.
## 2. Material Palettes
This video is one of my personal favorites, as it helped me develop a deeper appreciation and technical understanding for design choices I had been making intuitively. Noah's exploration of material palettes goes beyond the surface-level "what looks good together" approach, diving into how to create cohesive material relationships that work together harmoniously.
## 3. Lighting Design
What makes Noah's approach particularly valuable is how he connects principles to create cohesive, meaningful spaces. His emphasis on authenticity and function over pure aesthetics creates designs that are not just beautiful but also practical and enduring.
The way he explains these concepts makes them accessible while maintaining their depth and importance. It's this combination of practical knowledge and philosophical understanding that makes his content so valuable for anyone interested in interior design.
Whether you're a professional designer or someone looking to improve their living space, these videos provide a solid foundation for understanding what makes good design work. They remind us that great interior design is about creating spaces that are not just visually appealing but also functional, authentic, and meaningful to the people who use them.
---
## Permission to Enjoy
> A reflection on seniority, freedom, responsibility, and the power of a mentor's simple advice.
A manager and mentor of mine once gave me advice that stuck: just do more of the things you enjoy.
With seniority comes freedom—but also responsibility, and, more often than not, stress. I'm expected to figure out my own goals and the best way to have impact. That's a lot to carry, and it's easy to get stuck in the daily mire of meetings, process, and busy work.
**Just do more of the things you enjoy**
That simple cue was exactly what I needed. It helped me de-clutter my days, find more joy in my work, and, as a result, have more impact.

---
## Building a Music Player: YouTube as a Backend
> How I built a music player for kohlhofer.com that pulls from a YouTube playlist, fetches video backgrounds, and focuses on an integrated audio/visual listening experience.
The [music page](https://kohlhofer.com/music) on my site is a simple but effective way to share my electronic music. Instead of uploading tracks or managing files, I just maintain a dedicated playlist on YouTube. The site pulls in the latest videos from that playlist automatically.
I fetch the background image for each track using the YouTube API. The result is a dynamic, ever-changing backdrop that matches the currently playing video.
Users get a focused, centered experience: you can shuffle, play, pause, and skip tracks right from the page. No distractions, no clutter—just music and visuals, front and center.
[](https://kohlhofer.com/music?v=7MWWRs_Nyj8)
Another nice touch: the URL auto-updates as you play, allowing for deep linking to specific videos. That means you can share a direct link to any track—like [this one](https://kohlhofer.com/music?v=7MWWRs_Nyj8), which is a fairly early piece paired with a snapshot of a nice moment in France.
---
## Let Go and Trust
> A reminder that excellence comes from trust, not control.
This section from another post makes for a good reminder for myself:
> My experience as a manager and team leader has taught me that the best results come when you let go of control and trust the people (and now, the tools) you work with. Excellence rarely comes from micromanagement or rigid prescriptions—it comes from creating space for others to contribute, experiment, and surprise you.
— from [Vibe Coding kohlhofer.com: Creation at the Speed of Thought](/blog/vibe-coding-kohlhofer)
---
## Visualizing Chaos: The Lorenz Attractor
> A fun exploration of chaos theory through code, creating an aesthetic visualization of the Lorenz attractor using P5.js.
## A Primer on Chaos Theory
Chaos theory studies how small changes in initial conditions can lead to vastly different outcomes - the famous "butterfly effect." The Lorenz attractor, discovered by meteorologist Edward Lorenz in 1963, is one of the most iconic examples of this phenomenon. It's a set of chaotic solutions to a simplified system of equations that model atmospheric convection.

What makes the Lorenz attractor fascinating is its "strange attractor" behavior - the system never repeats exactly the same path, yet it's confined to a specific region in space, creating an intricate, butterfly-like pattern that's both deterministic and unpredictable.
## CodePen and Aesthetic Visualization
I created this visualization on [CodePen](https://codepen.io/kohlhofer/pen/ZExzGLK/6dcf9eed602926b0ea193420e56bd4e4), using P5.js to bring the mathematical concept to life. P5.js proved to be the perfect tool for this project - its simplicity and animation capabilities made it possible to create an interactive visualization with relatively few lines of code.
The result is a piece that captures both the mathematical beauty and the chaotic nature of the system. From there, I simply ported it to [kohlhofer.com/lorenz](https://kohlhofer.com/lorenz). You can read more about that process in [this post](https://kohlhofer.com/blog/vibe-coding-kohlhofer).
## The Technical Side
The core of the visualization is surprisingly simple - just three differential equations:
```
dx/dt = σ(y - x)
dy/dt = x(ρ - z) - y
dz/dt = xy - βz
```
Where σ (sigma), ρ (rho), and β (beta) are parameters that determine the system's behavior. The magic happens when we integrate these equations over time, plotting the resulting points in 3D space.
## The Aesthetic Approach
While the mathematics behind the Lorenz attractor is fascinating, I wanted to create something fun. The visualization features smooth, flowing animations and dynamic camera movements that bring the mathematical concept to life. You can experience the full version at [kohlhofer.com/lorenz](https://kohlhofer.com/lorenz), where you can watch the system evolve in real-time.
## Part of a Larger Collection
This project lives in my "Bits & Pieces" collection at [kohlhofer.com/bits](https://kohlhofer.com/bits) - a playground where I dump my afternoon coding experiments and visual explorations. It's where I try out new ideas, play with different technologies, and create things just for the fun of it. The Lorenz attractor is just one of many experiments where I mix code, design, and a bit of mathematical curiosity to create something visually interesting.
## What's Next?
The Lorenz attractor visualization serves as a perfect example of how mathematical concepts can be transformed into engaging visual experiences, making complex ideas more accessible and enjoyable to explore.
---
## Vibe Coding kohlhofer.com: Creation at the Speed of Thought
> How I built kohlhofer.com trying out a new approach to design and software development.
_**Edit (May 2025):** Since writing this, "vibe coding" has become a mainstay term. I still think it's a terrible name—but the approach and speed it describes are here to stay._
I built the new version [kohlhofer.com](https://kohlhofer.com) in just a few days, and the process felt less like a solo project and more like collaborating with a high-performing team—only much faster. Some people call this "vibe coding"—letting intuition, rapid iteration, and AI support drive the entire creation process. I don't love the term (it's not mine), but it does capture the spirit of how quickly and fluidly things came together.
## Did I code it? Defenitely not.
Did I design it? Absolutely. But not in the traditional sense. I directed the design much like you would when working with a great team of designers: setting the vision, making key decisions, and letting the details emerge through fast feedback and iteration. With AI as my creative partner, the boundaries between design, content, and implementation blurred. It was all happening at once.
## Rethinking engineering principles?
Coding principles like DRY (Don't Repeat Yourself) matter less because the AI is perfectly happy to update navigation elements or content in multiple places. And with the site hosted on GitHub Pages, deployment and updates are effortless. The friction of manual updates is gone, so you can focus on what matters—clarity and experience. It's a simple, robust solution for a personal site that's always evolving.
## Iteration Over Implementation
The [maps page](https://kohlhofer.com/map) on kohlhofer.com is a great example of this new workflow. It's built with D3, and the core implementation didn't take long at all. What surprised me was how much of my time was spent not on the technical side, but on iterating through the presentation and design details—colors, layout, interactivity, and how the data should feel. With AI and modern tools, I could focus entirely on the result and the user experience, rather than wrestling with the underlying code.
The [bits page](https://kohlhofer.com/bits) is another testament to this new way of working. I took some of my older CodePen explorations—like the [City](https://kohlhofer.com/city) generator and [Lorenz](https://kohlhofer.com/lorenz) visualizations—and quickly ported them over to the site. I barely touched any code myself. AI created the scaffolding, and I simply talked through the integration, describing what I wanted and how things should fit together. The process was fast, fluid, and let me focus on the creative and conceptual side rather than the technical plumbing.

## Lessons Learned: Letting Go and Trusting the Process
My experience as a manager and team leader has taught me that the best results come when you let go of control and trust the people (and now, the tools) you work with. Excellence rarely comes from micromanagement or rigid prescriptions—it comes from creating space for others to contribute, experiment, and surprise you.
I've found the same principle applies when working with AI. The less prescriptive I am, the more surprising—and often delightful—the results. I enjoy being surprised at work and in life, and this new way of building things rekindled that sense of discovery.
I'll do a lot more of this.
---
## Coding as a Tool: Generating Patterns for the Siding of a new House
> How I used code to create a natural-looking random pattern for board and batten siding, ensuring both aesthetic appeal and structural requirements.
I always wanted to build a house and had a life long fascination with architecture. When the opportunity finally came to build our own home, I found myself facing an interesting challenge: I wanted to create something more interesting than the traditional board and batten siding pattern, while still using the cost-effective fiber cement panels that are standard in modern construction. The goal was to create a pattern that would look natural and random while meeting the specific structural requirements of these practical, durable materials.

### The Challenge
As anyone who's ever worked on a building project knows, achieving balance between aesthetics and function is no easy task. I had a vision for the siding—something that looked natural, yet fit within the constraints of structural requirements. Specifically, I needed to:
1. Create a genuinely random pattern that didn't feel forced or artificial.
2. Place battens in specific locations where large fiber cement panels meet.
3. Avoid odd-looking combinations that would be noticeable or out of place.
4. Communicate the final pattern clearly to the builders.
The task seemed simple at first, but quickly became clear that the devil was in the details.
## The Solution
I turned to code to solve this problem. Using CodePen, I created a tool that could generate random patterns while respecting certain constraints.
Here's a live version of what I came up with:
## The Process
I experimented with various random seeds and pattern generation algorithms until I found a combination that produced results that looked natural while avoiding any awkward patterns. The key was to:
1. Define fixed points where battens must appear (panel joints)
2. Generate random positions for additional battens
3. Apply rules to ensure minimum and maximum spacing
4. Visualize the result in real-time
After many iterations, the code was starting to show results that satisfied both my design sensibility and the technical requirements.
### The Result: Bringing the Vision to Life
The photos below show the siding implementation, which was a direct result of those hours spent in front of the screen, tweaking code and testing patterns.






## Code and Generative Architecture
This project is a perfect example of how coding can be a powerful tool in unexpected places. By using code to generate and visualize the pattern, I was able to:
1. Quickly iterate through different possibilities
2. Ensure consistency in the pattern
3. Provide clear, unambiguous instructions to the builders
4. Save time that would have been spent manually drawing patterns
The result is a siding pattern that looks natural and random, but was actually carefully designed and controlled through code.
You can explore the code and try different seeds in the CodePen above. Each seed will generate a different pattern while maintaining the required constraints.
This project demonstrates how coding can be applied to solve real-world problems in unexpected ways. We were able to achieve a result that looks natural while meeting all structural requirements. I am reall happy with the outcome and had a blast working on this.
---